Implicit-VidSRL
收藏资源简介:
Implicit-VidSRL数据集由爱丁堡大学和达姆施塔特工业大学联合创建,旨在帮助AI更好地理解和推理程序视频中的上下文和动作序列。该数据集包含231个视频,每个视频都包含多步骤的烹饪说明,并标注了显式和隐式论元,以帮助模型学习如何从视觉和文本上下文中推断出这些隐式论元。数据集的创建过程包括三个阶段:识别隐式实体、将多步骤指令转换为语义角色标签、手动校正自动生成的标签。该数据集可用于评估多模态模型的上下文推理能力和实体跟踪能力,旨在解决多模态程序数据中隐式论元预测的问题。
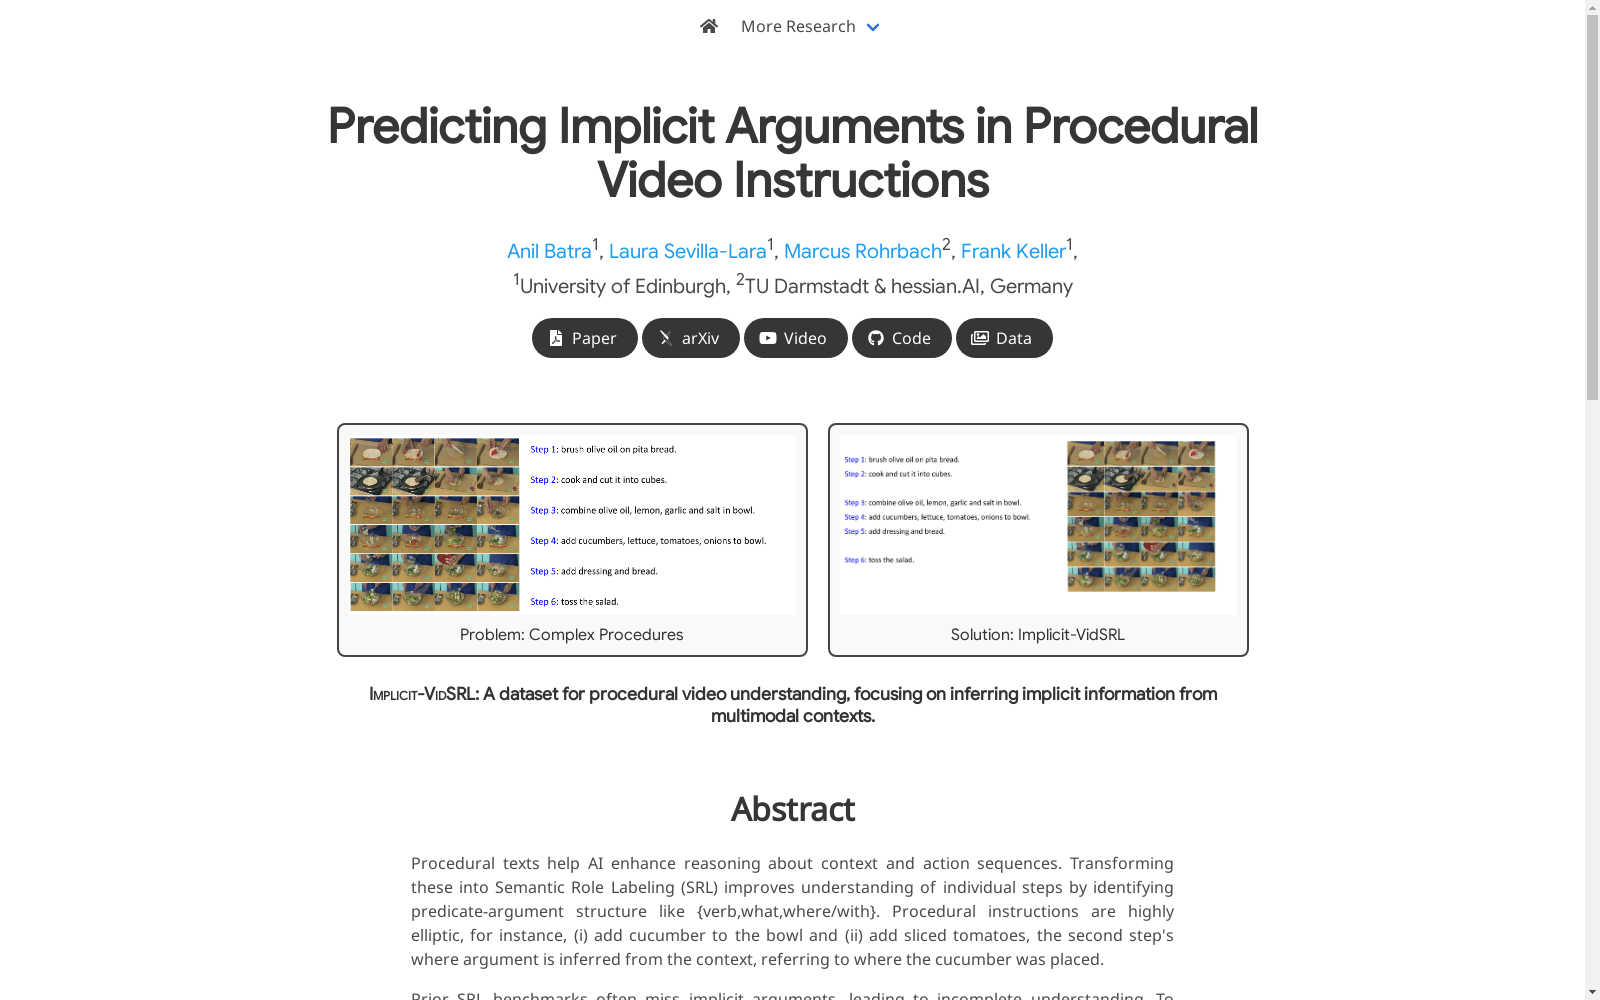
The Implicit-VidSRL dataset was jointly developed by the University of Edinburgh and Technische Universität Darmstadt, with the goal of enabling AI to better understand and reason about contexts and action sequences in procedural cooking videos. It contains 231 videos, each featuring multi-step cooking instructions, and is annotated with both explicit and implicit arguments to help models learn to infer these implicit arguments from both visual and textual contexts. The dataset construction process consists of three stages: identifying implicit entities, converting multi-step instructions into semantic role labels, and manually correcting automatically generated labels. This dataset can be utilized to evaluate the contextual reasoning and entity tracking abilities of multimodal models, and is intended to address the problem of implicit argument prediction in multimodal procedural data.