y0mur/turkish-chat-normalization-mini
收藏资源简介:
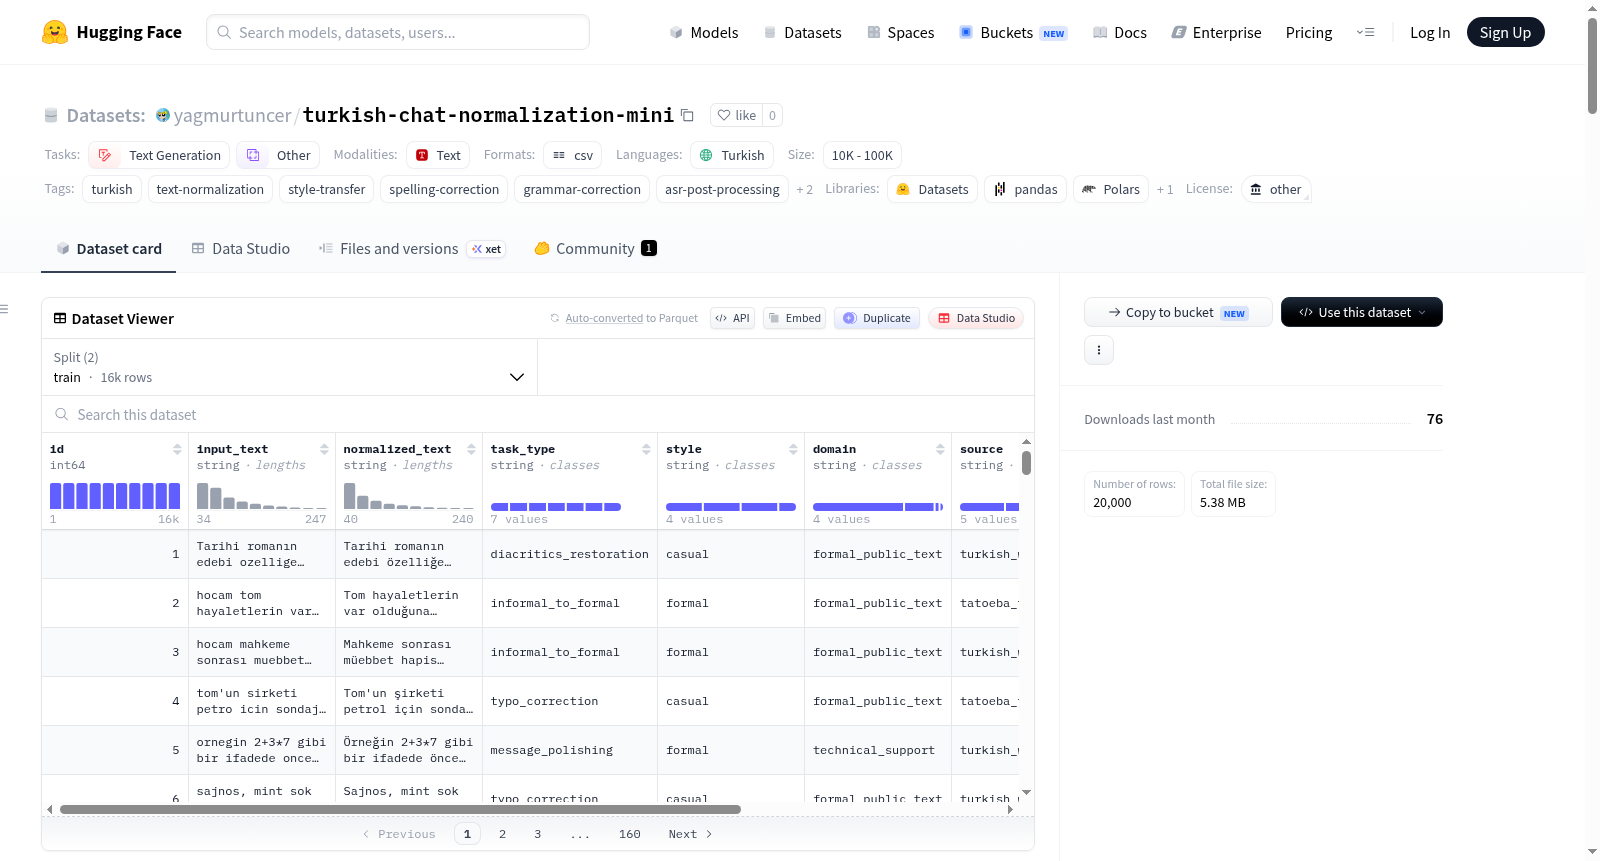
Turkish Chat Normalization Mini 是一个基于网络来源和规则降级的土耳其语文本规范化数据集,旨在将嘈杂、非正式、无标点或缺少变音符号的土耳其语文本重写为更干净、更易读的土耳其语。该数据集不包含私人用户消息、聊天记录、社交媒体评论、投诉记录或抓取的个人对话。源句子收集自开放的土耳其语网络资源,而输入侧通过受控的基于规则的降级模式创建。数据集包含20,000个示例,分为训练集(16,000行)和测试集(4,000行),支持多种任务类型,如拼写纠正、变音符号恢复、语法修复、非正式到标准/正式改写、消息润色和学术润色等。数据来源于多个开放土耳其语文本源,如Tatoeba、土耳其语维基百科、维基教科书、维基语录和维基文库,并包含源和许可证字段以支持溯源和归属。数据集适用于土耳其语文本到文本实验,包括序列到序列规范化模型、LLM指令调优原型、土耳其语拼写和风格纠正管道、后ASR文本规范化实验以及土耳其语重写和清理系统的评估。
Turkish Chat Normalization Mini is a web-derived and rule-degraded Turkish text normalization dataset designed for rewriting noisy, informal, unpunctuated, or diacritics-missing Turkish text into cleaner and more readable Turkish. The dataset does not contain private user messages, chat logs, social media comments, complaint records, or scraped personal conversations. Source sentences are collected from open Turkish web resources, while the input side is created through controlled rule-based degradation patterns. The dataset contains 20,000 examples, split into training set (16,000 rows) and test set (4,000 rows), and supports various task types such as spelling and typo correction, Turkish diacritics restoration, grammar and sentence cleanup, informal-to-standard/formal rewriting, message polishing, and academic or report-style polishing. Data is derived from multiple open Turkish text sources, including Tatoeba Turkish sentence export, Turkish Wikipedia, Turkish Wikibooks, Turkish Wikiquote, and Turkish Wikisource, with source and license fields included for provenance and attribution. The dataset is intended for Turkish text-to-text experiments, including sequence-to-sequence normalization models, LLM instruction-tuning prototypes, Turkish spelling and style correction pipelines, post-ASR text normalization experiments, and evaluation of Turkish rewriting and cleanup systems.