
eQASC, eQASC-perturbed, eOBQA
收藏资源简介:
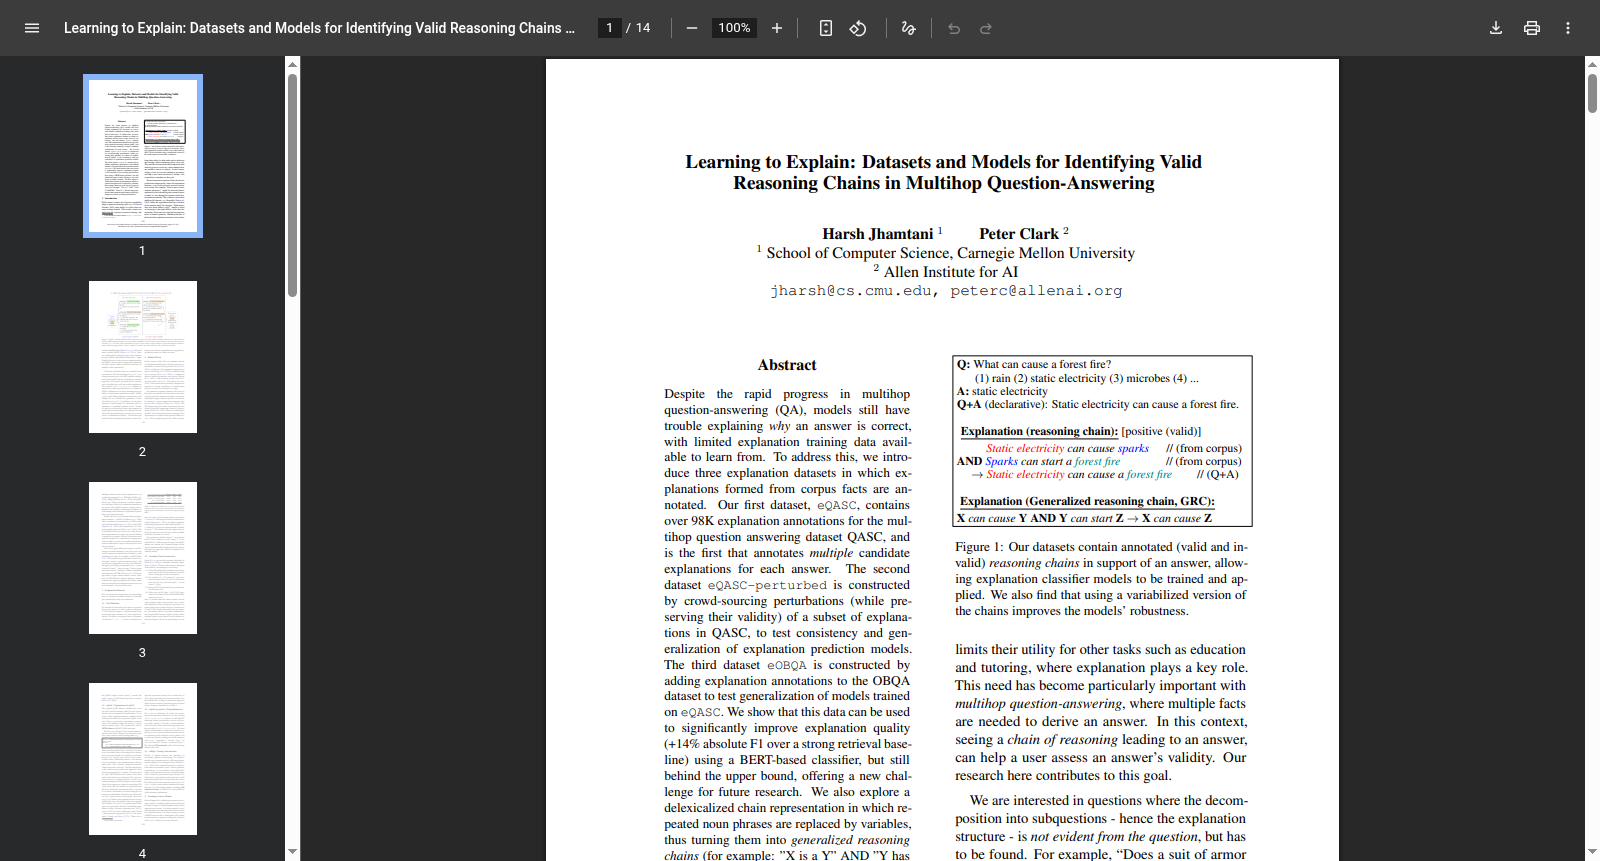
本研究引入了三个解释性数据集,旨在提升多跳问答系统中答案解释的质量。首个数据集eQASC,包含超过98,000个解释注释,针对QASC多跳问答数据集,首次为每个答案标注多个候选解释。第二个数据集eQASC-perturbed通过众包方式对QASC中部分解释进行语义不变的扰动,以测试解释预测模型的稳定性和泛化能力。第三个数据集eOBQA则是在OBQA数据集基础上添加解释注释,用于测试模型在eQASC训练后的泛化能力。这些数据集不仅支持解释分类模型的训练和评估,还通过引入去词汇化的链式表示,将重复名词短语替换为变量,形成泛化推理链,从而提高模型对特定扰动的鲁棒性。
This study introduces three explanatory datasets intended to enhance the quality of answer explanations in multi-hop question answering systems. The first dataset, eQASC, includes over 98,000 explanation annotations, and is the first to annotate multiple candidate explanations for each answer in the QASC multi-hop question answering dataset. The second dataset, eQASC-perturbed, performs semantically invariant perturbations on a subset of explanations in QASC through crowdsourcing, to test the stability and generalization performance of explanation prediction models. The third dataset, eOBQA, adds explanation annotations to the original OBQA dataset, and is used to evaluate the generalization ability of models trained on eQASC. These datasets not only support the training and evaluation of explanation classification models, but also introduce delexicalized chain representations, which replace repeated noun phrases with variables to form generalized inference chains, thereby improving the robustness of models against specific perturbations.
- 1Learning to Explain: Datasets and Models for Identifying Valid Reasoning Chains in Multihop Question-Answering卡内基梅隆大学计算机科学学院 · 2020年


