VerboVision/cem_mil_pares_5k_pt_5
收藏资源简介:
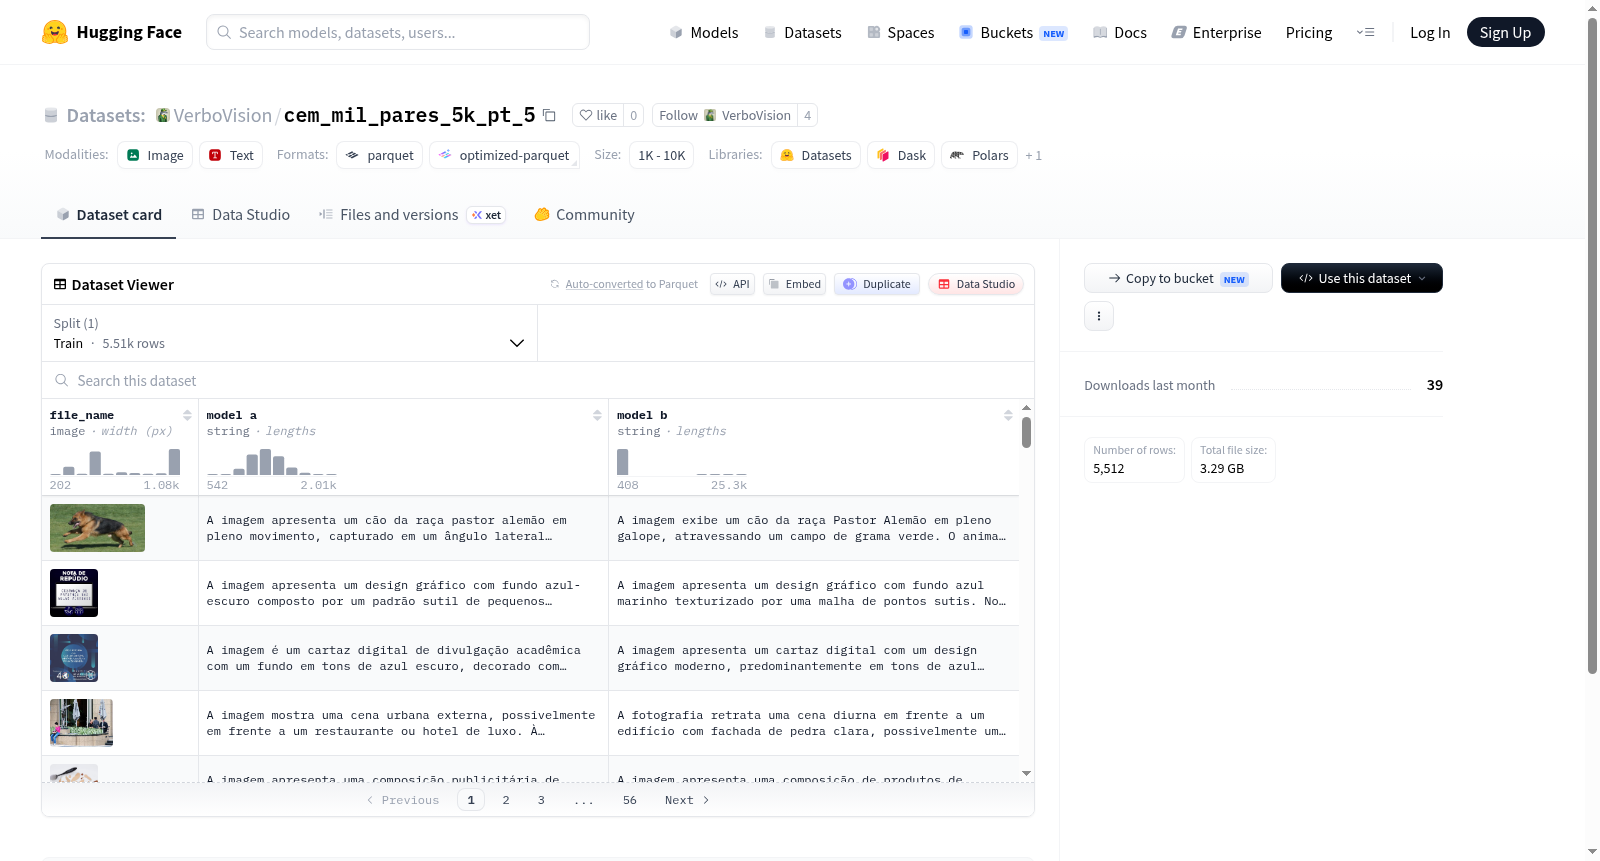
该数据集是一个图像和文本结合的数据集,主要用于训练目的。它包含5512个训练样本,总大小约为3.29GB。数据集的特征包括:file_name(图像文件)、model a(字符串类型,可能表示模型A的相关信息)和model b(字符串类型,可能表示模型B的相关信息)。这些特征暗示数据集可能涉及模型比较或评估任务,例如图像生成模型的输出对比。数据以Train分割组织,文件路径为data/Train-*。
This dataset is a combined image and text dataset primarily intended for training purposes. It includes 5512 training examples with a total size of approximately 3.29GB. The features of the dataset consist of: file_name (image file), model a (string type, possibly representing information related to model A), and model b (string type, possibly representing information related to model B). These features suggest that the dataset may involve tasks such as model comparison or evaluation, for example, comparing outputs from image generation models. The data is organized into a Train split with file paths in data/Train-*.