MM-Hallu/ViGoR
收藏资源简介:
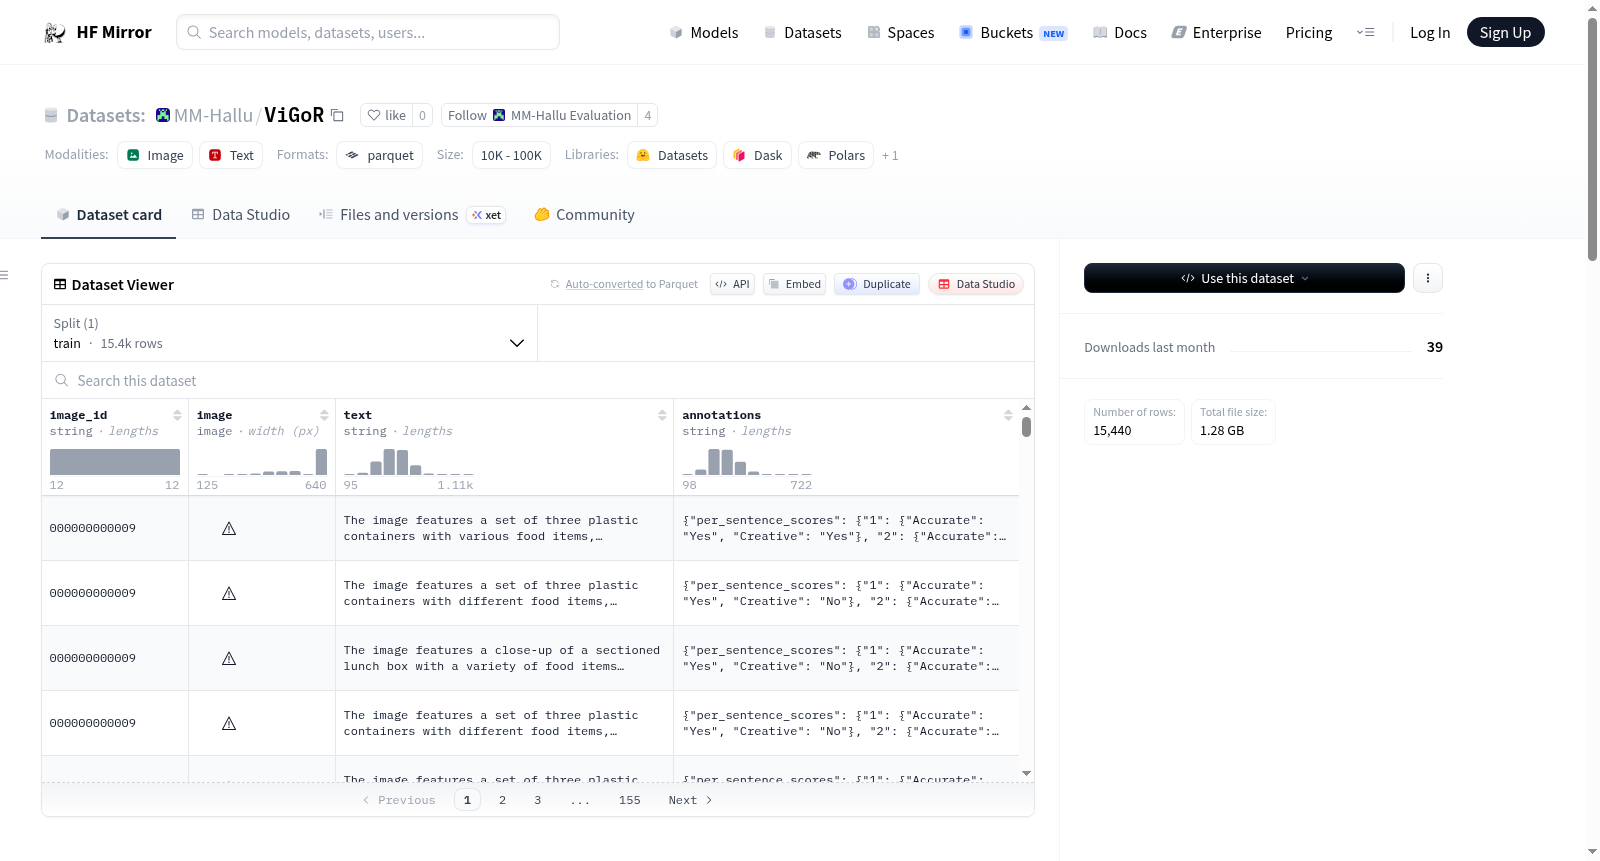
ViGoR是一个大规模基准数据集,用于评估图像描述中的视觉基础和幻觉检测。它包含15,440个人工标注的图像-描述对,每对都有细粒度的句子级准确性判断和创造力评分。数据集中的图像来源于MSCOCO train2017,共7,703张独特图像。每个示例的标注包括句子级准确性和创造力判断,以及整体细节评分。数据集的结构包括image_id(COCO图像ID)、image(图像字节和文件名)、text(生成的图像描述)和annotations(JSON编码的标注信息,包含句子评分和整体细节评分)。
ViGoR is a large-scale benchmark for evaluating visual grounding in image descriptions. It contains 15,440 human-annotated image-description pairs with fine-grained, sentence-level accuracy judgments and creativity scores. The images are sourced from MSCOCO train2017, totaling 7,703 unique images. Each example includes per-sentence accuracy and creativity judgments, as well as an overall detail rating. The dataset schema consists of image_id (COCO image ID), image (image bytes and filename), text (generated image description), and annotations (JSON-encoded annotation dict with sentence scores and overall detail score).