
RankArena
收藏资源简介:
RankArena是一个统一的平台,用于比较和分析检索、重排和RAG系统的性能,并收集人类和LLM的反馈。它支持多种评估模式,包括直接重排可视化、盲匹配对比较、监督手动文档注释和端到端RAG答案质量评估。该平台还集成了LLM-as-a-judge评估,能够比较模型生成的排名和人类真实标注。所有交互都存储为结构化评估数据集,可用于训练重排器、奖励模型、判断代理或检索策略选择器。RankArena旨在解决评估检索增强生成(RAG)和文档重排系统质量的问题,由于缺乏可扩展的、以用户为中心的、多视角的评估工具,这仍然是一个挑战。
RankArena is a unified platform for comparing and analyzing the performance of retrieval, reranking, and RAG systems, while collecting feedback from both humans and LLMs. It supports multiple evaluation modes, including direct reranking visualization, blind pairwise comparison, supervised manual document annotation, and end-to-end RAG answer quality assessment. The platform also integrates LLM-as-a-judge evaluation, which enables comparison between model-generated rankings and human ground-truth annotations. All interactions are stored as structured evaluation datasets that can be used to train rerankers, reward models, judgment agents, or retrieval strategy selectors. RankArena aims to address the challenge of evaluating the quality of retrieval-augmented generation (RAG) and document reranking systems, which remains a critical issue due to the lack of scalable, user-centric, and multi-perspective evaluation tools.
🔍 RerankArena数据集概述
🎯 核心功能
- 多模态评估:用户投票、LLM评判、基准测试分数
- 实时竞赛:竞技场式头对头比较
- 综合基准测试:BEIR、DL19、DL20和自定义数据集
- 高级分析:统计显著性、聚类、相关性
- RAG管道测试:端到端检索增强生成
📊 支持方法
- 检索:BM25、DPR、BGE、ColBERT、Contriever、在线搜索
- 重新排序:多种重新排序方法和模型
- 生成:通过Together AI使用Llama 3.3 70B
- 评估:NDCG、MAP、MRR、RBO、ELO评分
- 数据集:维基百科、MS MARCO、BEIR集合
📚 标签描述与用例
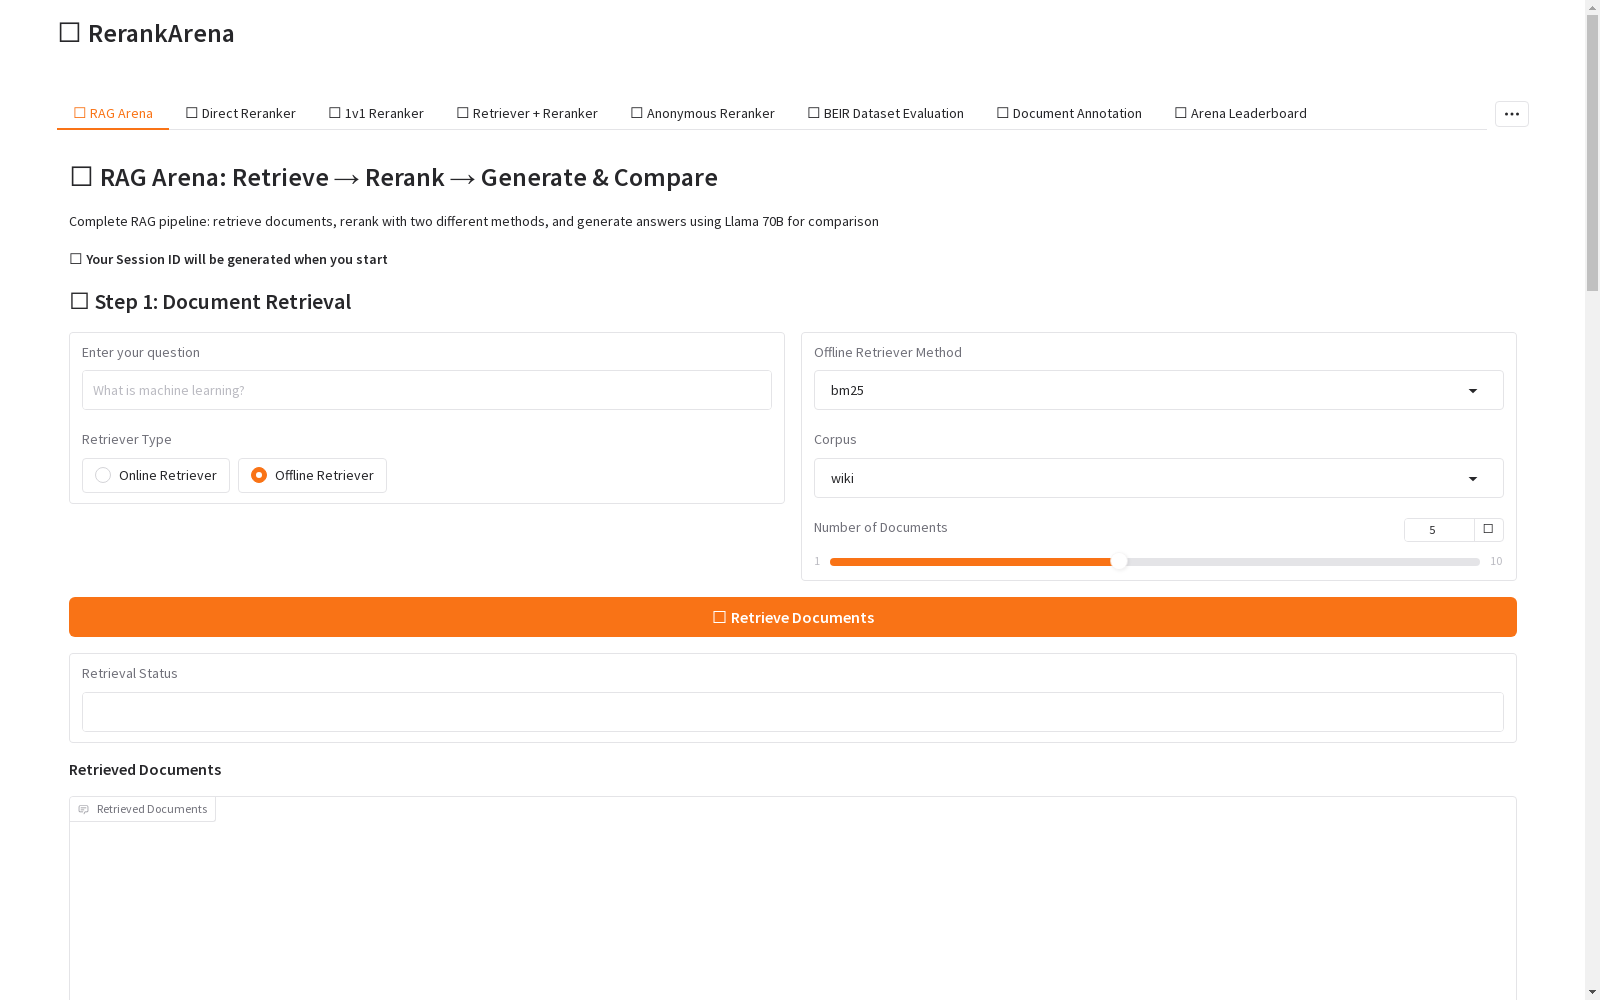
💬 RAG竞技场
- 端到端检索增强生成管道评估
- 在线和离线文档检索
- 并排重新排序比较
- LLM答案生成与来源归属
🎯 直接重新排序
- 使用自己的文档或JSON上传测试单个重新排序方法
- JSON文件上传支持
- 实时重新排序结果
⚔️ 1v1重新排序竞技场
- 头对头比较两个重新排序方法
- 用户投票系统
- LLM评判评估
🛠️ 检索器+重新排序器
- 完整检索和重新排序管道
- 多种检索方法(BM25、DPR、BGE等)
- 在线网络搜索通过Serper API
🎭 匿名竞技场
- 隐藏方法身份的公正评估
- 无偏见评估
- 统计比较
📈 BEIR评估
- 在标准BEIR数据集和TREC深度学习任务上评估方法
- 14+ BEIR数据集(COVID、NFCorpus等)
- 标准IR指标(NDCG@k、MAP@k、MRR)
✏️ 文档注释
- 通过手动排名文档相关性创建地面真实注释
- 直观的拖放排名
- 完整文档内容显示
🏆 竞技场排行榜
- 查看综合排名结合用户投票、LLM评估和基准分数
- ELO评分系统
- 多维度性能分析
🏗️ 技术架构
📚 数据层
- 用户数据:会话跟踪、投票历史
- 交互:所有活动的JSON日志记录
- 基准测试:BEIR数据集、自定义评估
- 注释:手动相关性判断
🔧 处理层
- Rankify:多种重新排序方法
- 检索器:BM25、神经检索器
- LLM评判:自动评估
- 分析:统计分析引擎
🎨 表示层
- Gradio UI:交互式Web界面
- Plotly图表:高级可视化
- 实时更新:渐进式反馈
- 导出选项:CSV、JSON下载
- 1RankArena: A Unified Platform for Evaluating Retrieval, Reranking and RAG with Human and LLM Feedback因斯布鲁克大学 · 2025年


