speechocean-l2eval
收藏资源简介:
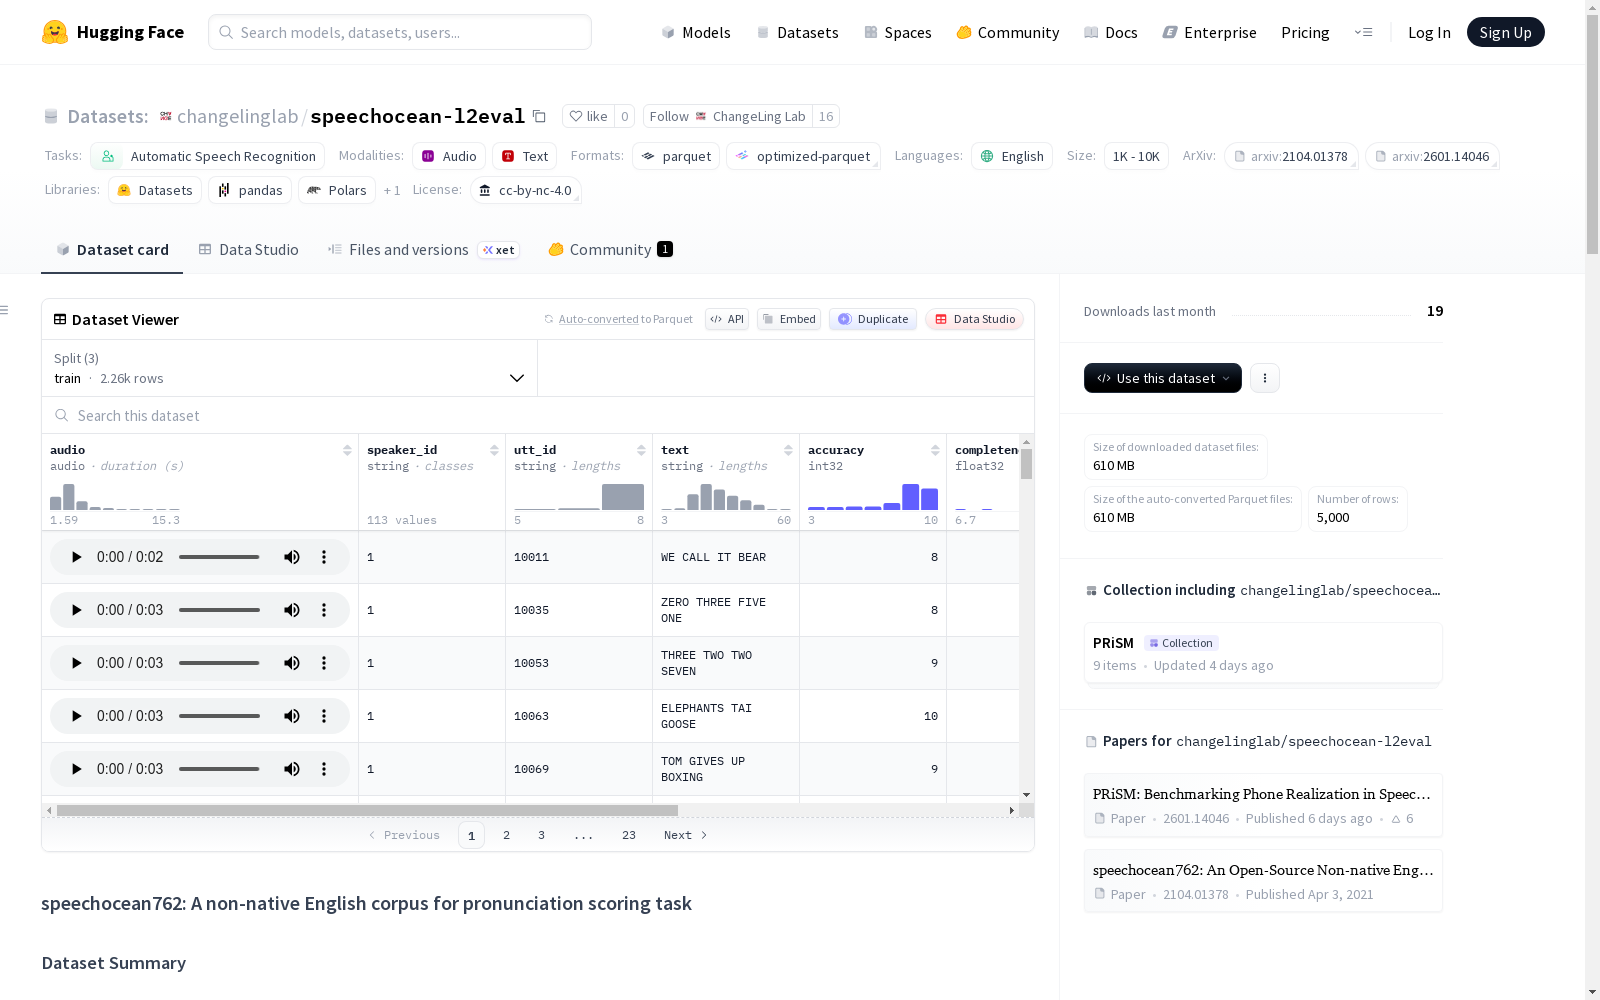
speechocean762 是一个开源的、非母语英语语音语料库,专为发音评估和 L2 口语能力建模而设计。该数据集包含句子级别的音频和专家评分,分为标准的训练集、验证集和测试集。所有说话者均为以普通话为母语的英语学习者,涵盖儿童和成人。每个句子由五位专家独立评估,使用标准化的发音指标。数据集适用于发音评分、L2 语音评估、语音表示学习以及回归或分类任务。数据集包含以下字段:音频(16 kHz)、说话者标识符、句子标识符、提示句子、发音准确度、单词发音完整度、流畅度评分、韵律评分和总体发音评分。数据集分为训练集(2260 个样本)、验证集(240 个样本)和测试集(2500 个样本),且各集合之间说话者不重叠。数据集源自原始 speechocean762 语料库,但不包含单词级别和音素级别的标注。
speechocean762 is an open-source non-native English speech corpus designed for pronunciation assessment and L2 speaking proficiency modeling. The dataset contains sentence-level audio and expert scores, divided into standard training, validation, and test sets. All speakers are Mandarin-native English learners, covering both children and adults. Each sentence is independently evaluated by five experts using standardized pronunciation metrics. The corpus is applicable to pronunciation scoring, L2 speech assessment, speech representation learning, as well as regression or classification tasks. The dataset includes the following fields: audio (16 kHz), speaker identifier, sentence identifier, prompt sentence, pronunciation accuracy, word pronunciation completeness, fluency score, prosody score, and overall pronunciation score. The dataset is split into training set (2260 samples), validation set (240 samples), and test set (2500 samples), with no overlapping speakers across the splits. The corpus is derived from the original speechocean762 corpus, but excludes word-level and phoneme-level annotations.
SpeechOcean762 数据集概述
数据集基本信息
- 数据集名称: speechocean762
- 主要用途: 发音评估与第二语言口语能力建模
- 语言: 英语(非母语)
- 说话者背景: 所有说话者均为母语为汉语的英语学习者,涵盖儿童和成人。
- 许可证: CC BY-NC 4.0
- 关联论文: arXiv:2601.14046
数据集内容与结构
- 核心内容: 提供句子级别的音频和专家评分。
- 数据规模: 总大小约586 MB,包含5000个样本。
- 数据划分: 包含三个预定义的、说话者互斥的标准划分:
- 训练集 (
train): 2260个样本 - 验证集 (
val): 240个样本 - 测试集 (
test): 2500个样本
- 训练集 (
数据特征
每个样本包含以下字段:
| 字段名 | 数据类型 | 描述 |
|---|---|---|
audio |
Audio |
语音波形,采样率为16 kHz |
speaker_id |
string |
说话者标识符 |
utt_id |
string |
话语标识符 |
text |
string |
提示句子文本 |
accuracy |
int32 |
句子级别的发音准确度评分 |
completeness |
float32 |
正确发音单词的百分比 |
fluency |
int32 |
句子级别的流利度评分 |
prosodic |
int32 |
句子级别的韵律评分 |
total |
int32 |
整体发音评分 |
评分说明
- 所有句子级别的评分均遵循原始 speechocean762 的定义。
- 每个话语由五位专家标注者使用标准化的发音指标独立评估。
- 本版本不包含单词级别和音素级别的标注。
适用任务
- 发音评分
- 第二语言语音评估
- 语音表示学习
- 下游回归或分类任务
来源与致谢
-
源数据集: https://huggingface.co/datasets/mispeech/speechocean762
-
原始论文引用: bibtex @inproceedings{zhang2021speechocean762, title={speechocean762: An Open-Source Non-native English Speech Corpus For Pronunciation Assessment}, author={Zhang, Junbo and Zhang, Zhiwen and Wang, Yongqing and Yan, Zhiyong and Song, Qiong and Huang, Yukai and Li, Ke and Povey, Daniel and Wang, Yujun}, booktitle={Proc. Interspeech 2021}, year={2021} }
-
相关工具: 可与基准测试工具包 PRiSM 配合使用:https://github.com/changelinglab/prism