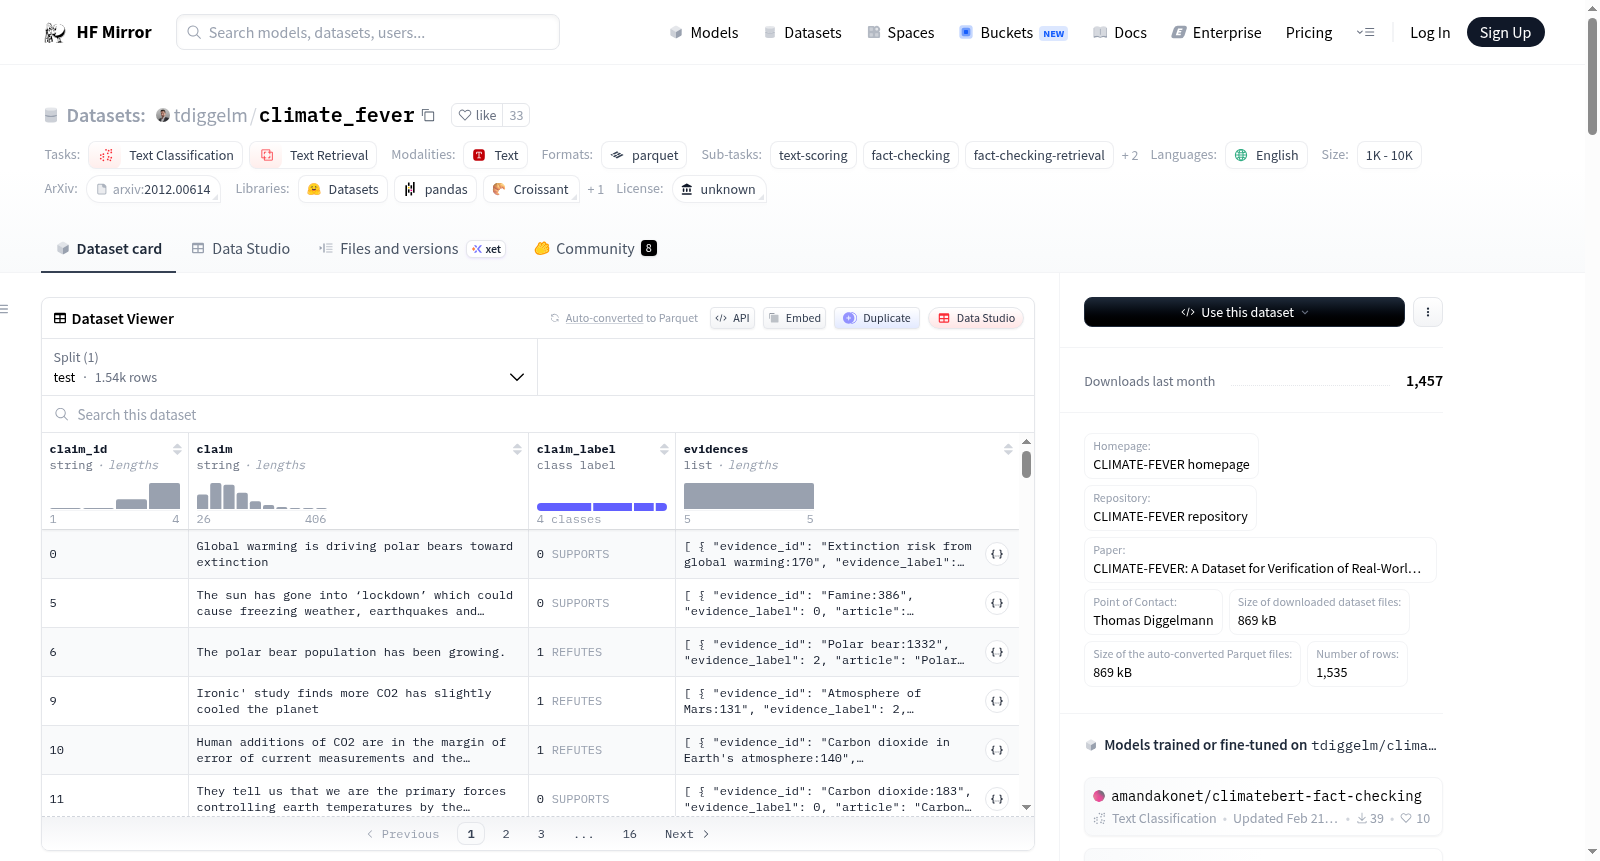
tdiggelm/climate_fever
收藏资源简介:
--- annotations_creators: - crowdsourced - expert-generated language_creators: - found language: - en license: - unknown multilinguality: - monolingual size_categories: - 1K<n<10K source_datasets: - extended|wikipedia - original task_categories: - text-classification - text-retrieval task_ids: - text-scoring - fact-checking - fact-checking-retrieval - semantic-similarity-scoring - multi-input-text-classification paperswithcode_id: climate-fever pretty_name: ClimateFever dataset_info: features: - name: claim_id dtype: string - name: claim dtype: string - name: claim_label dtype: class_label: names: '0': SUPPORTS '1': REFUTES '2': NOT_ENOUGH_INFO '3': DISPUTED - name: evidences list: - name: evidence_id dtype: string - name: evidence_label dtype: class_label: names: '0': SUPPORTS '1': REFUTES '2': NOT_ENOUGH_INFO - name: article dtype: string - name: evidence dtype: string - name: entropy dtype: float32 - name: votes list: string splits: - name: test num_bytes: 2429240 num_examples: 1535 download_size: 868947 dataset_size: 2429240 configs: - config_name: default data_files: - split: test path: data/test-* --- # Dataset Card for ClimateFever ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** [CLIMATE-FEVER homepage](http://climatefever.ai) - **Repository:** [CLIMATE-FEVER repository](https://github.com/tdiggelm/climate-fever-dataset) - **Paper:** [CLIMATE-FEVER: A Dataset for Verification of Real-World Climate Claims](https://arxiv.org/abs/2012.00614) - **Leaderboard:** [Needs More Information] - **Point of Contact:** [Thomas Diggelmann](mailto:thomasdi@student.ethz.ch) ### Dataset Summary A dataset adopting the FEVER methodology that consists of 1,535 real-world claims regarding climate-change collected on the internet. Each claim is accompanied by five manually annotated evidence sentences retrieved from the English Wikipedia that support, refute or do not give enough information to validate the claim totalling in 7,675 claim-evidence pairs. The dataset features challenging claims that relate multiple facets and disputed cases of claims where both supporting and refuting evidence are present. ### Supported Tasks and Leaderboards [Needs More Information] ### Languages The text in the dataset is in English, as found in real-world claims about climate-change on the Internet. The associated BCP-47 code is `en`. ## Dataset Structure ### Data Instances ``` { "claim_id": "0", "claim": "Global warming is driving polar bears toward extinction", "claim_label": 0, # "SUPPORTS" "evidences": [ { "evidence_id": "Extinction risk from global warming:170", "evidence_label": 2, # "NOT_ENOUGH_INFO" "article": "Extinction risk from global warming", "evidence": "\"Recent Research Shows Human Activity Driving Earth Towards Global Extinction Event\".", "entropy": 0.6931471805599453, "votes": [ "SUPPORTS", "NOT_ENOUGH_INFO", null, null, null ] }, { "evidence_id": "Global warming:14", "evidence_label": 0, # "SUPPORTS" "article": "Global warming", "evidence": "Environmental impacts include the extinction or relocation of many species as their ecosystems change, most immediately the environments of coral reefs, mountains, and the Arctic.", "entropy": 0.0, "votes": [ "SUPPORTS", "SUPPORTS", null, null, null ] }, { "evidence_id": "Global warming:178", "evidence_label": 2, # "NOT_ENOUGH_INFO" "article": "Global warming", "evidence": "Rising temperatures push bees to their physiological limits, and could cause the extinction of bee populations.", "entropy": 0.6931471805599453, "votes": [ "SUPPORTS", "NOT_ENOUGH_INFO", null, null, null ] }, { "evidence_id": "Habitat destruction:61", "evidence_label": 0, # "SUPPORTS" "article": "Habitat destruction", "evidence": "Rising global temperatures, caused by the greenhouse effect, contribute to habitat destruction, endangering various species, such as the polar bear.", "entropy": 0.0, "votes": [ "SUPPORTS", "SUPPORTS", null, null, null ] }, { "evidence_id": "Polar bear:1328", "evidence_label": 2, # "NOT_ENOUGH_INFO" "article": "Polar bear", "evidence": "\"Bear hunting caught in global warming debate\".", "entropy": 0.6931471805599453, "votes": [ "SUPPORTS", "NOT_ENOUGH_INFO", null, null, null ] } ] } ``` ### Data Fields - `claim_id`: a `string` feature, unique claim identifier. - `claim`: a `string` feature, claim text. - `claim_label`: a `int` feature, overall label assigned to claim (based on evidence majority vote). The label correspond to 0: "supports", 1: "refutes", 2: "not enough info" and 3: "disputed". - `evidences`: a list of evidences with fields: - `evidence_id`: a `string` feature, unique evidence identifier. - `evidence_label`: a `int` feature, micro-verdict label. The label correspond to 0: "supports", 1: "refutes" and 2: "not enough info". - `article`: a `string` feature, title of source article (Wikipedia page). - `evidence`: a `string` feature, evidence sentence. - `entropy`: a `float32` feature, entropy reflecting uncertainty of `evidence_label`. - `votes`: a `list` of `string` features, corresponding to individual votes. ### Data Splits This benchmark dataset currently consists of a single data split `test` that consists of 1,535 claims or 7,675 claim-evidence pairs. ## Dataset Creation ### Curation Rationale [Needs More Information] ### Source Data #### Initial Data Collection and Normalization [Needs More Information] #### Who are the source language producers? [Needs More Information] ### Annotations #### Annotation process [Needs More Information] #### Who are the annotators? [Needs More Information] ### Personal and Sensitive Information [Needs More Information] ## Considerations for Using the Data ### Social Impact of Dataset [Needs More Information] ### Discussion of Biases [Needs More Information] ### Other Known Limitations [Needs More Information] ## Additional Information ### Dataset Curators [Needs More Information] ### Licensing Information [Needs More Information] ### Citation Information ```bibtex @misc{diggelmann2020climatefever, title={CLIMATE-FEVER: A Dataset for Verification of Real-World Climate Claims}, author={Thomas Diggelmann and Jordan Boyd-Graber and Jannis Bulian and Massimiliano Ciaramita and Markus Leippold}, year={2020}, eprint={2012.00614}, archivePrefix={arXiv}, primaryClass={cs.CL} } ``` ### Contributions Thanks to [@tdiggelm](https://github.com/tdiggelm) for adding this dataset.
数据集概述
名称: ClimateFever
语言: 英语 (en)
许可: 未知
多语言性: 单语
大小: 1K<n<10K
来源数据集: 扩展自Wikipedia,原始数据
任务类别: 文本分类, 文本检索
任务ID: 文本评分, 事实检查, 事实检查检索, 语义相似度评分, 多输入文本分类
论文代码ID: climate-fever
数据集大小:
- 下载大小: 868947字节
- 数据集大小: 2429240字节
数据集结构
数据实例
每个实例包含以下字段:
claim_id: 字符串, 唯一声明标识符claim: 字符串, 声明文本claim_label: 整数, 声明标签 (0: SUPPORTS, 1: REFUTES, 2: NOT_ENOUGH_INFO, 3: DISPUTED)evidences: 列表, 每个证据包含:evidence_id: 字符串, 唯一证据标识符evidence_label: 整数, 证据标签 (0: SUPPORTS, 1: REFUTES, 2: NOT_ENOUGH_INFO)article: 字符串, 来源文章标题evidence: 字符串, 证据句子entropy: 浮点数, 熵值, 反映evidence_label的不确定性votes: 字符串列表, 对应个人投票
数据分割
test: 包含1535个声明或7675个声明-证据对
数据集创建
注释
- 创建者: 众包, 专家生成
引用信息
bibtex @misc{diggelmann2020climatefever, title={CLIMATE-FEVER: A Dataset for Verification of Real-World Climate Claims}, author={Thomas Diggelmann and Jordan Boyd-Graber and Jannis Bulian and Massimiliano Ciaramita and Markus Leippold}, year={2020}, eprint={2012.00614}, archivePrefix={arXiv}, primaryClass={cs.CL} }