QuangDuy/mmarco-vi-hard-negatives
收藏资源简介:
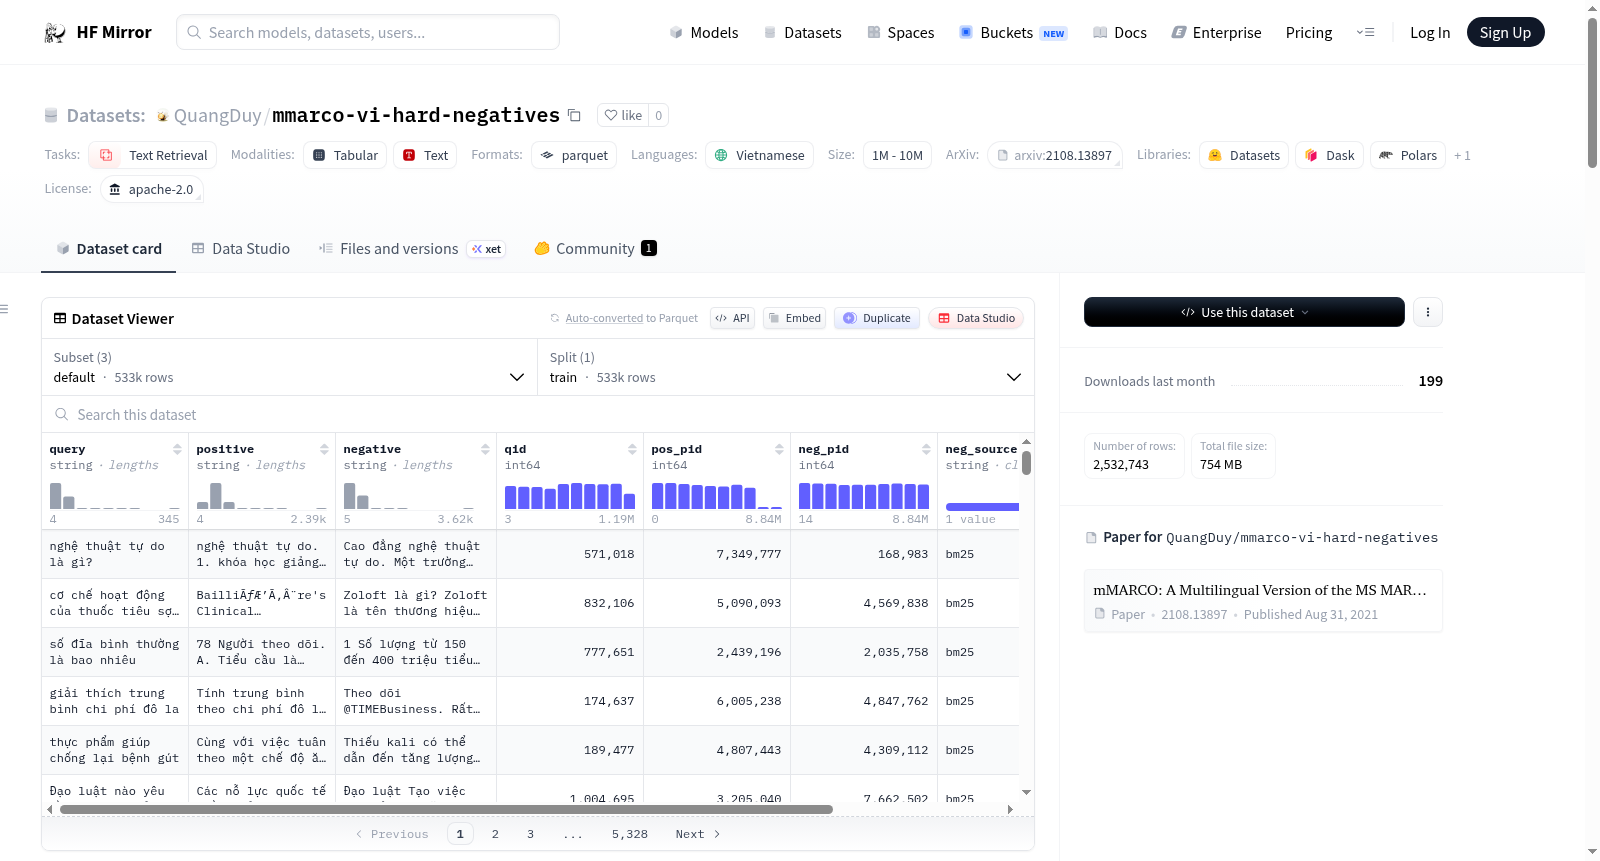
--- language: - vi license: apache-2.0 task_categories: - text-retrieval pretty_name: Vietnamese mMARCO Hard Negatives size_categories: - 1M<n<10M configs: - config_name: default data_files: - split: train path: data/train/*.parquet - config_name: bm25_rank10_50_2neg_1m data_files: - split: train path: data/bm25_rank10_50_2neg_1m/train/*.parquet - config_name: bm25_rank1_10_1m data_files: - split: train path: data/bm25_rank1_10_1m/train/*.parquet --- # Vietnamese mMARCO Hard Negatives This dataset is a Vietnamese triplet dataset for dense retrieval training. It combines Vietnamese text from `unicamp-dl/mmarco` with hard-negative passage ids from `sentence-transformers/msmarco-hard-negatives`. ## Available Configs | config | rows | neg source | sampling | rank window | | --- | ---: | --- | --- | --- | | `default` | 532,743 | bm25 | 1 per positive | 10-50 | | `bm25_rank10_50_2neg_1m` | 1,000,000 | bm25 | 2 per positive | 10-50 | | `bm25_rank1_10_1m` | 1,000,000 | bm25 | 2 per positive | 1-10 | ## Repository - Hub repo: `QuangDuy/mmarco-vi-hard-negatives` - splits: `train` - configs: `3` ## Columns - `query`: Vietnamese query text - `positive`: Vietnamese positive passage text - `negative`: Vietnamese hard-negative passage text - `qid`: original MSMARCO query id - `pos_pid`: original MSMARCO positive passage id - `neg_pid`: original MSMARCO negative passage id - `neg_source`: source retriever used to mine the hard negative - `neg_rank`: 1-based rank of the selected negative inside the upstream candidate list ## How It Was Built 1. Stream the upstream hard-negative metadata and choose deterministic negatives from the configured retriever pool. 2. Collect only the Vietnamese query ids and passage ids needed for the selected triplets. 3. Stream the Vietnamese mMARCO query and collection files and extract the required text. 4. Join ids back into text triplets and write Parquet shards for Hub-native loading. ## Usage ```python from datasets import load_dataset dataset = load_dataset("QuangDuy/mmarco-vi-hard-negatives") print(dataset["train"][0]) dataset = load_dataset("QuangDuy/mmarco-vi-hard-negatives", "bm25_rank10_50_2neg_1m") print(dataset["train"][0]) dataset = load_dataset("QuangDuy/mmarco-vi-hard-negatives", "bm25_rank1_10_1m") print(dataset["train"][0]) ``` ## Provenance - Vietnamese text source: `unicamp-dl/mmarco` - Hard-negative ids source: `sentence-transformers/msmarco-hard-negatives` This repository republishes derived triplets. Please review the upstream dataset cards and licenses before using the data in production or redistribution-sensitive settings. ## Build Statistics ### `default` - rows: `532,743` - parquet shards: `22` - negative source: `bm25` - negatives per positive: `1` - preferred rank window: `10` to `50` - seed: `42` - selected metadata rows: `532,743` - extracted queries: `502,931` - extracted passages: `941,468` - build seconds: `1,702.56` ### `bm25_rank10_50_2neg_1m` - rows: `1,000,000` - parquet shards: `40` - negative source: `bm25` - negatives per positive: `2` - preferred rank window: `10` to `50` - seed: `42` - selected metadata rows: `1,000,000` - extracted queries: `471,977` - extracted passages: `1,232,544` - build seconds: `1,569.63` ### `bm25_rank1_10_1m` - rows: `1,000,000` - parquet shards: `40` - negative source: `bm25` - negatives per positive: `2` - preferred rank window: `1` to `10` - seed: `42` - selected metadata rows: `1,000,000` - extracted queries: `471,977` - extracted passages: `1,210,442` - build seconds: `2,551.79` ## Citation If you use this dataset, please cite the upstream sources: ```bibtex @article{DBLP:journals/corr/abs-2108-13897, author = {Luiz Bonifacio and Israel Campiotti and Roberto de Alencar Lotufo and Rodrigo Frassetto Nogueira}, title = {mMARCO: A Multilingual Version of MS MARCO Passage Ranking Dataset}, journal = {CoRR}, volume = {abs/2108.13897}, year = {2021}, url = {https://arxiv.org/abs/2108.13897} } ```