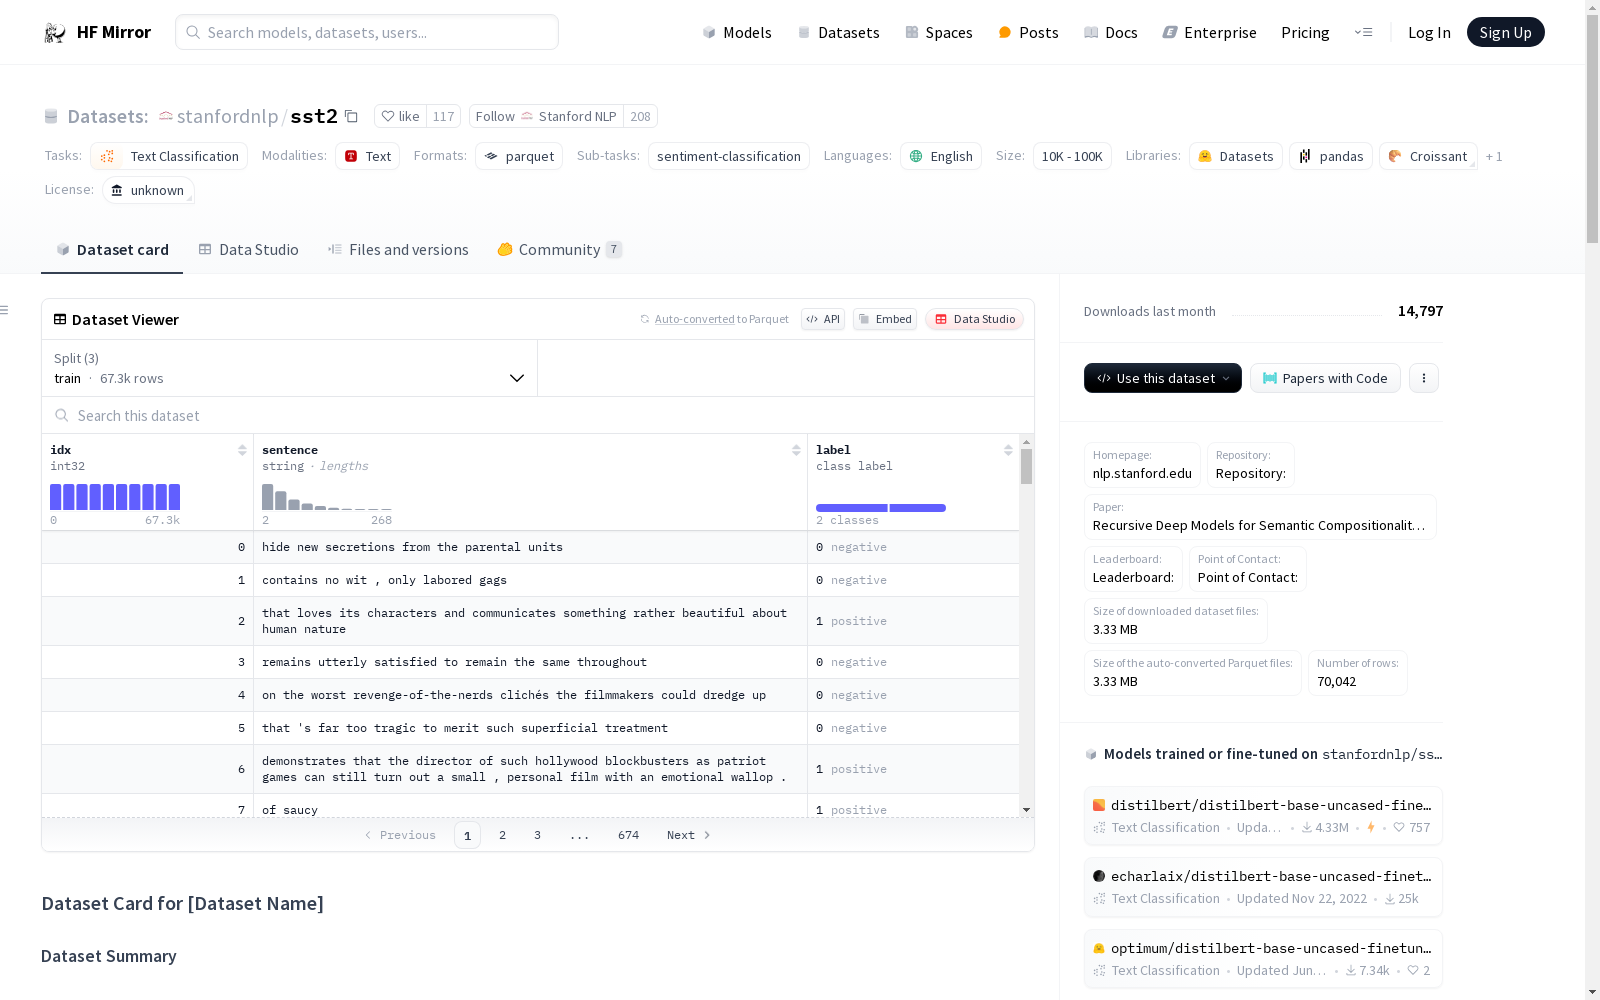
stanfordnlp/sst2
收藏资源简介:
--- annotations_creators: - crowdsourced language_creators: - found language: - en license: - unknown multilinguality: - monolingual size_categories: - 10K<n<100K source_datasets: - original task_categories: - text-classification task_ids: - sentiment-classification paperswithcode_id: sst pretty_name: Stanford Sentiment Treebank v2 dataset_info: features: - name: idx dtype: int32 - name: sentence dtype: string - name: label dtype: class_label: names: '0': negative '1': positive splits: - name: train num_bytes: 4681603 num_examples: 67349 - name: validation num_bytes: 106252 num_examples: 872 - name: test num_bytes: 216640 num_examples: 1821 download_size: 3331058 dataset_size: 5004495 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* - split: test path: data/test-* --- # Dataset Card for [Dataset Name] ## Table of Contents - [Table of Contents](#table-of-contents) - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** https://nlp.stanford.edu/sentiment/ - **Repository:** - **Paper:** [Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank](https://www.aclweb.org/anthology/D13-1170/) - **Leaderboard:** - **Point of Contact:** ### Dataset Summary The Stanford Sentiment Treebank is a corpus with fully labeled parse trees that allows for a complete analysis of the compositional effects of sentiment in language. The corpus is based on the dataset introduced by Pang and Lee (2005) and consists of 11,855 single sentences extracted from movie reviews. It was parsed with the Stanford parser and includes a total of 215,154 unique phrases from those parse trees, each annotated by 3 human judges. Binary classification experiments on full sentences (negative or somewhat negative vs somewhat positive or positive with neutral sentences discarded) refer to the dataset as SST-2 or SST binary. ### Supported Tasks and Leaderboards - `sentiment-classification` ### Languages The text in the dataset is in English (`en`). ## Dataset Structure ### Data Instances ``` {'idx': 0, 'sentence': 'hide new secretions from the parental units ', 'label': 0} ``` ### Data Fields - `idx`: Monotonically increasing index ID. - `sentence`: Complete sentence expressing an opinion about a film. - `label`: Sentiment of the opinion, either "negative" (0) or positive (1). The test set labels are hidden (-1). ### Data Splits | | train | validation | test | |--------------------|---------:|-----------:|-----:| | Number of examples | 67349 | 872 | 1821 | ## Dataset Creation ### Curation Rationale [More Information Needed] ### Source Data #### Initial Data Collection and Normalization [More Information Needed] #### Who are the source language producers? Rotten Tomatoes reviewers. ### Annotations #### Annotation process [More Information Needed] #### Who are the annotators? [More Information Needed] ### Personal and Sensitive Information [More Information Needed] ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed] ### Discussion of Biases [More Information Needed] ### Other Known Limitations [More Information Needed] ## Additional Information ### Dataset Curators [More Information Needed] ### Licensing Information Unknown. ### Citation Information ```bibtex @inproceedings{socher-etal-2013-recursive, title = "Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank", author = "Socher, Richard and Perelygin, Alex and Wu, Jean and Chuang, Jason and Manning, Christopher D. and Ng, Andrew and Potts, Christopher", booktitle = "Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing", month = oct, year = "2013", address = "Seattle, Washington, USA", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/D13-1170", pages = "1631--1642", } ``` ### Contributions Thanks to [@albertvillanova](https://github.com/albertvillanova) for adding this dataset.
annotations_creators: - 众包(crowdsourced) language_creators: - 公开采集(found) language: - 英语(en) license: - 未知 multilinguality: - 单语言(monolingual) size_categories: - 10K<n<100K source_datasets: - 原创数据集(original) task_categories: - 文本分类(text-classification) task_ids: - 情感分类(sentiment-classification) paperswithcode_id: sst pretty_name: 斯坦福情感树库v2(Stanford Sentiment Treebank v2) dataset_info: features: - name: idx dtype: int32 - name: sentence dtype: 字符串(string) - name: label dtype: class_label: names: '0': 消极(negative) '1': 积极(positive) splits: - name: train num_bytes: 4681603 num_examples: 67349 - name: validation num_bytes: 106252 num_examples: 872 - name: test num_bytes: 216640 num_examples: 1821 download_size: 3331058 dataset_size: 5004495 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* - split: test path: data/test-* # 数据集卡片 [数据集名称] ## 目录 - [目录](#目录) - [数据集描述](#数据集描述) - [数据集概述](#数据集概述) - [支持任务与排行榜](#支持任务与排行榜) - [语言](#语言) - [数据集结构](#数据集结构) - [数据实例](#数据实例) - [数据字段](#数据字段) - [数据划分](#数据划分) - [数据集构建](#数据集构建) - [构建初衷](#构建初衷) - [源数据](#源数据) - [注释](#注释) - [个人与敏感信息](#个人与敏感信息) - [数据使用注意事项](#数据使用注意事项) - [数据集的社会影响](#数据集的社会影响) - [偏差讨论](#偏差讨论) - [其他已知局限性](#其他已知局限性) - [附加信息](#附加信息) - [数据集维护者](#数据集维护者) - [授权信息](#授权信息) - [引用信息](#引用信息) - [贡献](#贡献) ## 数据集描述 - **主页**:https://nlp.stanford.edu/sentiment/ - **代码仓库**: - **论文**:[面向情感树库语义组合性的递归深度模型](https://www.aclweb.org/anthology/D13-1170/) - **排行榜**: - **联系方式**: ### 数据集概述 斯坦福情感树库(Stanford Sentiment Treebank)是一套带有完整标注句法树的语料库,可用于全面分析语言中情感的组合效应。该语料库基于Pang与Lee(2005)提出的数据集构建,包含从电影评论中提取的11855条独立句子。语料使用斯坦福句法分析器进行句法分析,共包含来自这些句法树的215154个唯一短语,每个短语均由3名人类标注者进行注释。 针对完整句子的二分类实验(丢弃中性句子,将样本划分为"消极/偏消极"与"积极/偏积极"两类)将该数据集称为SST-2或SST二分类数据集。 ### 支持任务与排行榜 - `情感分类(sentiment-classification)` ### 语言 数据集中的文本为英语(en)。 ## 数据集结构 ### 数据实例 {'idx': 0, 'sentence': 'hide new secretions from the parental units ', 'label': 0} ### 数据字段 - `idx`:单调递增的索引ID。 - `sentence`:表达对某部电影观点的完整句子。 - `label`:观点的情感倾向,分为"消极(0)"与"积极(1)"两类。测试集的标签被隐藏(值为-1)。 ### 数据划分 | | 训练集 | 验证集 | 测试集 | |--------------------|---------:|-----------:|-----:| | 样本数量 | 67349 | 872 | 1821 | ## 数据集构建 ### 构建初衷 [需更多信息] ### 源数据 #### 初始数据收集与标准化 [需更多信息] #### 源语言生产者是谁? 烂番茄(Rotten Tomatoes)影评人。 ### 注释 #### 注释流程 [需更多信息] #### 标注者是谁? [需更多信息] ### 个人与敏感信息 [需更多信息] ## 数据使用注意事项 ### 数据集的社会影响 [需更多信息] ### 偏差讨论 [需更多信息] ### 其他已知局限性 [需更多信息] ## 附加信息 ### 数据集维护者 [需更多信息] ### 授权信息 未知。 ### 引用信息 bibtex @inproceedings{socher-etal-2013-recursive, title = "面向情感树库语义组合性的递归深度模型", author = "Socher, Richard 与 Perelygin, Alex 与 Wu, Jean 与 Chuang, Jason 与 Manning, Christopher D. 与 Ng, Andrew 与 Potts, Christopher", booktitle = "2013年自然语言处理经验方法会议论文集", month = oct, year = "2013", address = "美国华盛顿州西雅图", publisher = "国际计算语言学协会", url = "https://www.aclweb.org/anthology/D13-1170", pages = "1631--1642", } ### 贡献 感谢 [@albertvillanova](https://github.com/albertvillanova) 添加本数据集。
数据集概述
数据集名称
- Pretty Name: Stanford Sentiment Treebank v2
- Paperswithcode ID: sst
数据集描述
- 语言: 英语 (
en) - 许可证: 未知
- 多语言性: 单语种
- 大小类别: 10K<n<100K
- 源数据集: 原始数据
- 任务类别: 文本分类
- 任务ID: 情感分类 (
sentiment-classification)
数据集结构
-
数据实例:
{idx: 0, sentence: hide new secretions from the parental units , label: 0}
-
数据字段:
idx: 单调递增的索引ID。sentence: 关于电影的完整意见表达句子。label: 意见的情感,分为“负面”(0) 或 “正面”(1)。
-
数据分割:
分割 训练 验证 测试 示例数 67349 872 1821
数据集创建
- 源语言生产者: Rotten Tomatoes 评论者
- 许可证信息: 未知
- 引用信息: bibtex @inproceedings{socher-etal-2013-recursive, title = "Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank", author = "Socher, Richard and Perelygin, Alex and Wu, Jean and Chuang, Jason and Manning, Christopher D. and Ng, Andrew and Potts, Christopher", booktitle = "Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing", month = oct, year = "2013", address = "Seattle, Washington, USA", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/D13-1170", pages = "1631--1642", }