neomatrix369/py-bug-trace-gpt-4-1-mini-l1-rollouts
收藏资源简介:
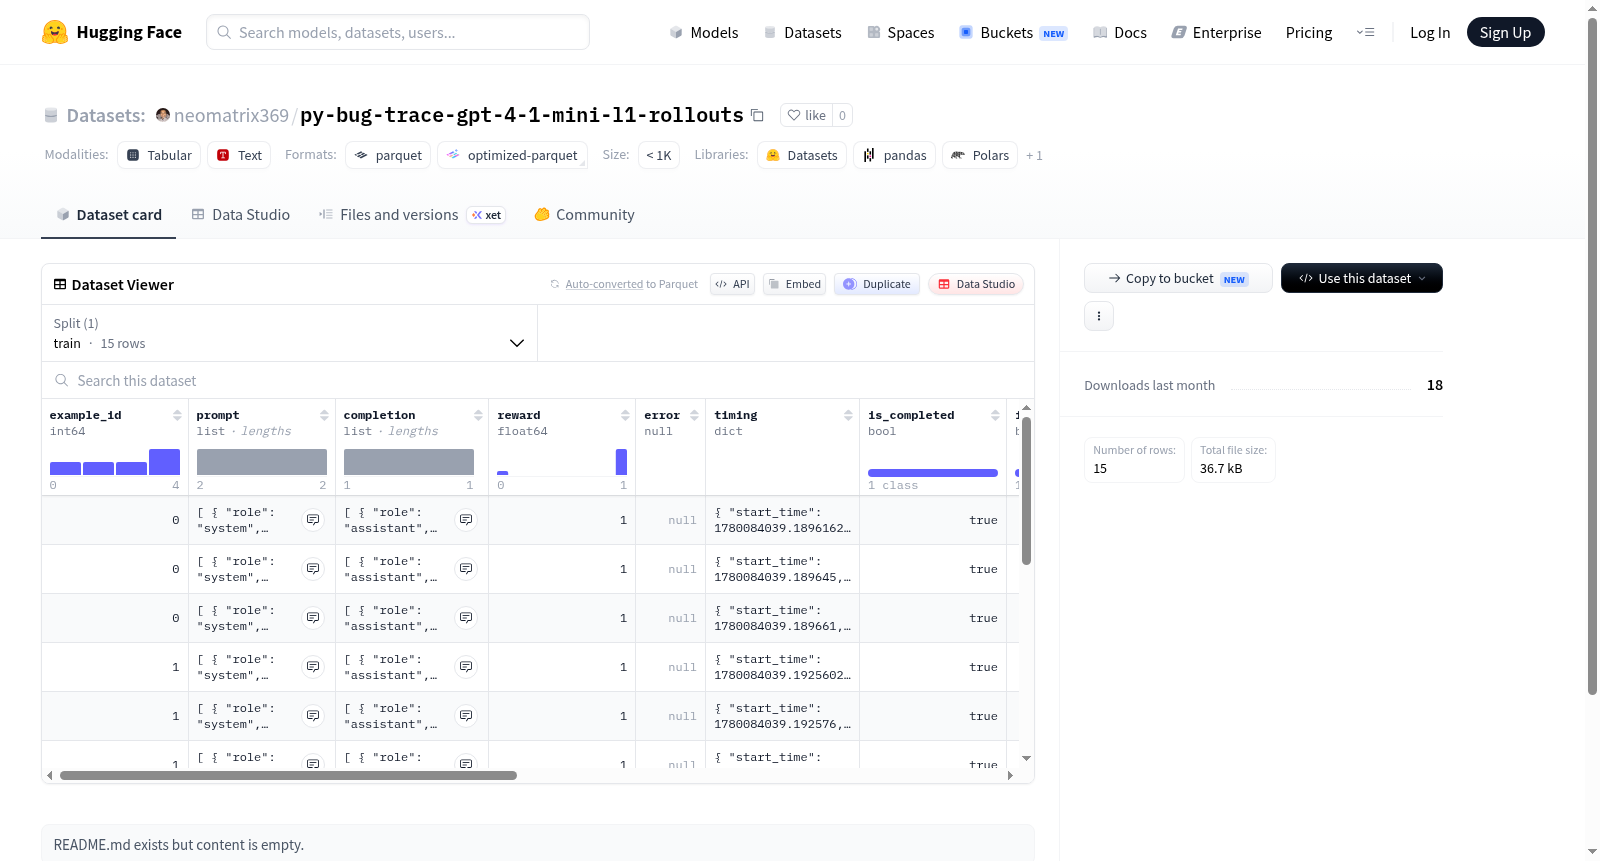
该数据集包含用于训练或评估的对话数据,每个样本具有唯一标识符(example_id)、提示(prompt)和完成(completion)字段,其中提示和完成由角色和内容组成。此外,还包括奖励值(reward)、错误信息(error)、时间记录(timing)、完成状态(is_completed)、截断状态(is_truncated)、停止条件(stop_condition)、评估指标(如精确匹配奖励和回合数)、工具定义(tool_defs)、令牌使用情况(token_usage)等元数据。数据集分为训练集,包含15个样本,总大小为14353字节。
This dataset contains dialogue data for training or evaluation, with each sample including a unique identifier (example_id), prompt, and completion fields, where both prompt and completion consist of role and content. Additionally, it includes reward value (reward), error information (error), timing records (timing), completion status (is_completed), truncation status (is_truncated), stop condition (stop_condition), evaluation metrics (such as exact match reward and number of turns), tool definitions (tool_defs), token usage (token_usage), and other metadata. The dataset is split into a training set with 15 examples and a total size of 14353 bytes.