normalcomputing/wikiqa-counterfactual
收藏资源简介:
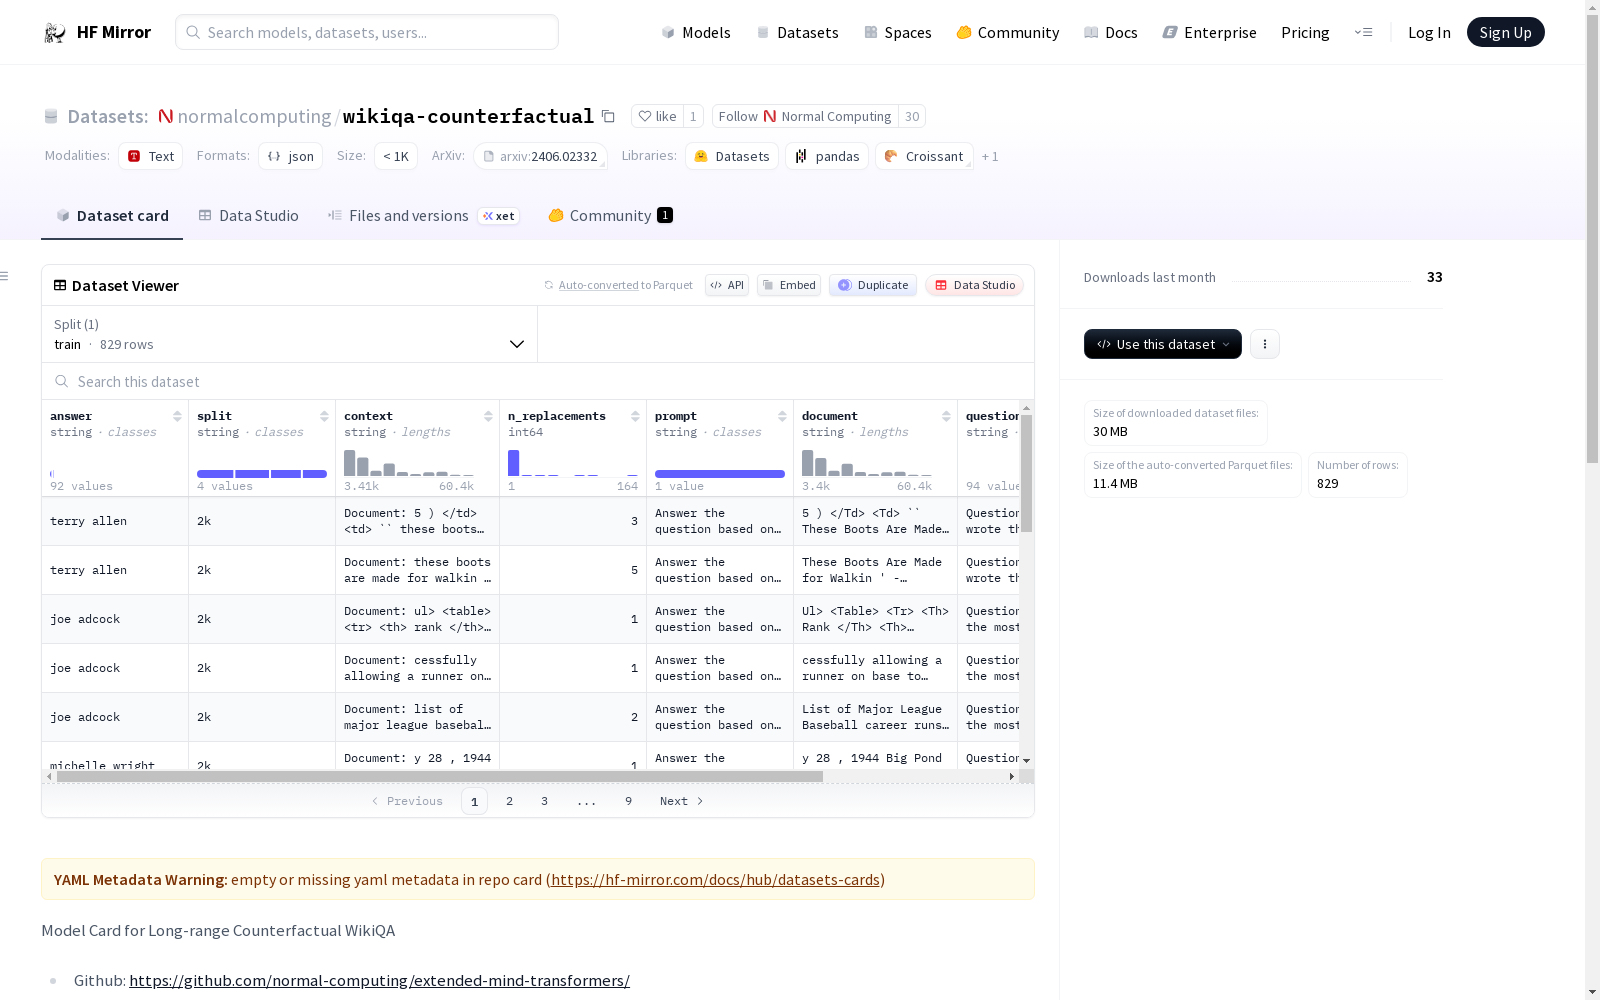
Model Card for Long-range Counterfactual WikiQA * Github: https://github.com/normal-computing/extended-mind-transformers/ * ArXiv: https://arxiv.org/abs/2406.02332 Original dataset by Abacus AI. * Developed by: Normal Computing, Adapted from Abacus AI * License: Apache 2.0 ## Long-range Counterfactual Retrieval Benchmark This benchmark is a modified [wikiQA benchmark](https://huggingface.co/datasets/abacusai/WikiQA-Free_Form_QA). The dataset is composed of Wikipedia articles (of 2-16 thousand tokens) and corresponding questions. We modify the dataset by changing the labeled answers to realistic but wrong answers, to control for facts memorized during pre-training. For example, we replace every instance of "Lee Hazlewood" with "Terry Allen" in the Wikipedia entry for the song "These Boots Were Made For Walking", and then ask the model to produce the songwriter's name, with the correct answer now being "Terry Allen". More detail on the dataset creation can be found in the [paper](). ### Splits Splits: 2k, 4k, 8k, 16k ### Column Names - `split`: split the sample is part of - `question`: the query (I.e. "Who wrote the song ...") - `prompt`: the prompt (I.e. "Answer the following question ...") - `document`: the original Wikipedia article - `context`: the edited Wikipedia article - `original_eval`: the original answer (before edits were made) - `answer`: the correct answer (after edits were made) - `n_replacements`: the number of times the `original_eval` was replaced with the `answer` in the `context` --- license: apache-2.0 ---
长距离反事实WikiQA数据集卡片 * GitHub链接:https://github.com/normal-computing/extended-mind-transformers/ * ArXiv论文链接:https://arxiv.org/abs/2406.02332 本数据集源自Abacus AI的原始数据集。 * 开发方:Normal Computing,改编自Abacus AI * 许可协议:Apache 2.0 ## 长距离反事实检索基准集 该基准集是经修改的wikiQA基准测试集(wikiQA benchmark),原始数据集可参见:https://huggingface.co/datasets/abacusai/WikiQA-Free_Form_QA。本数据集由2至16千Token的维基百科文章与对应问题构成。我们通过将标注答案替换为看似合理但实则错误的答案,以此实现对模型预训练阶段所记忆事实知识的可控性调控。例如,我们在歌曲《These Boots Were Made For Walking》的维基百科条目中,将所有出现的“Lee Hazlewood”替换为“Terry Allen”,随后向模型提问该歌曲的词曲作者姓名,此时正确答案即为“Terry Allen”。关于数据集构建的更多细节可参见相关论文。 ### 划分方式 划分子集规模:2k、4k、8k、16k ### 字段名称 - `split`:样本所属的划分子集 - `question`:查询问题(例如“谁创作了歌曲……”) - `prompt`:提示文本(例如“请回答以下问题……”) - `document`:原始维基百科文章 - `context`:经过编辑的维基百科文章 - `original_eval`:原始标注答案(编辑前的答案) - `answer`:修正后的正确答案(编辑后的答案) - `n_replacements`:在`context`中,`original_eval`被替换为`answer`的次数 --- 许可协议:Apache 2.0 ---
数据集概述
名称: Long-range Counterfactual Retrieval Benchmark
开发机构: Normal Computing, Adapted from Abacus AI
许可证: Apache 2.0
数据集内容
- 数据来源: 原始数据集由Abacus AI提供,基于WikiQA-Free_Form_QA数据集。
- 数据构成: 包含Wikipedia文章(2-16千字)和相应的问题。
- 数据修改: 将标记的答案替换为现实但错误的答案,以控制预训练期间记忆的事实。例如,将“Lee Hazlewood”替换为“Terry Allen”,并要求模型识别歌曲作者。
数据集结构
- 分割: 2k, 4k, 8k, 16k
- 列名:
split: 样本所属的分割question: 查询问题prompt: 提示信息document: 原始Wikipedia文章context: 编辑后的Wikipedia文章original_eval: 编辑前的原始答案answer: 编辑后的正确答案n_replacements: 在context中将original_eval替换为answer的次数
数据集用途
用于评估模型在长范围反事实检索任务中的表现,通过提供编辑后的Wikipedia文章和问题,测试模型对预训练记忆事实的控制能力。