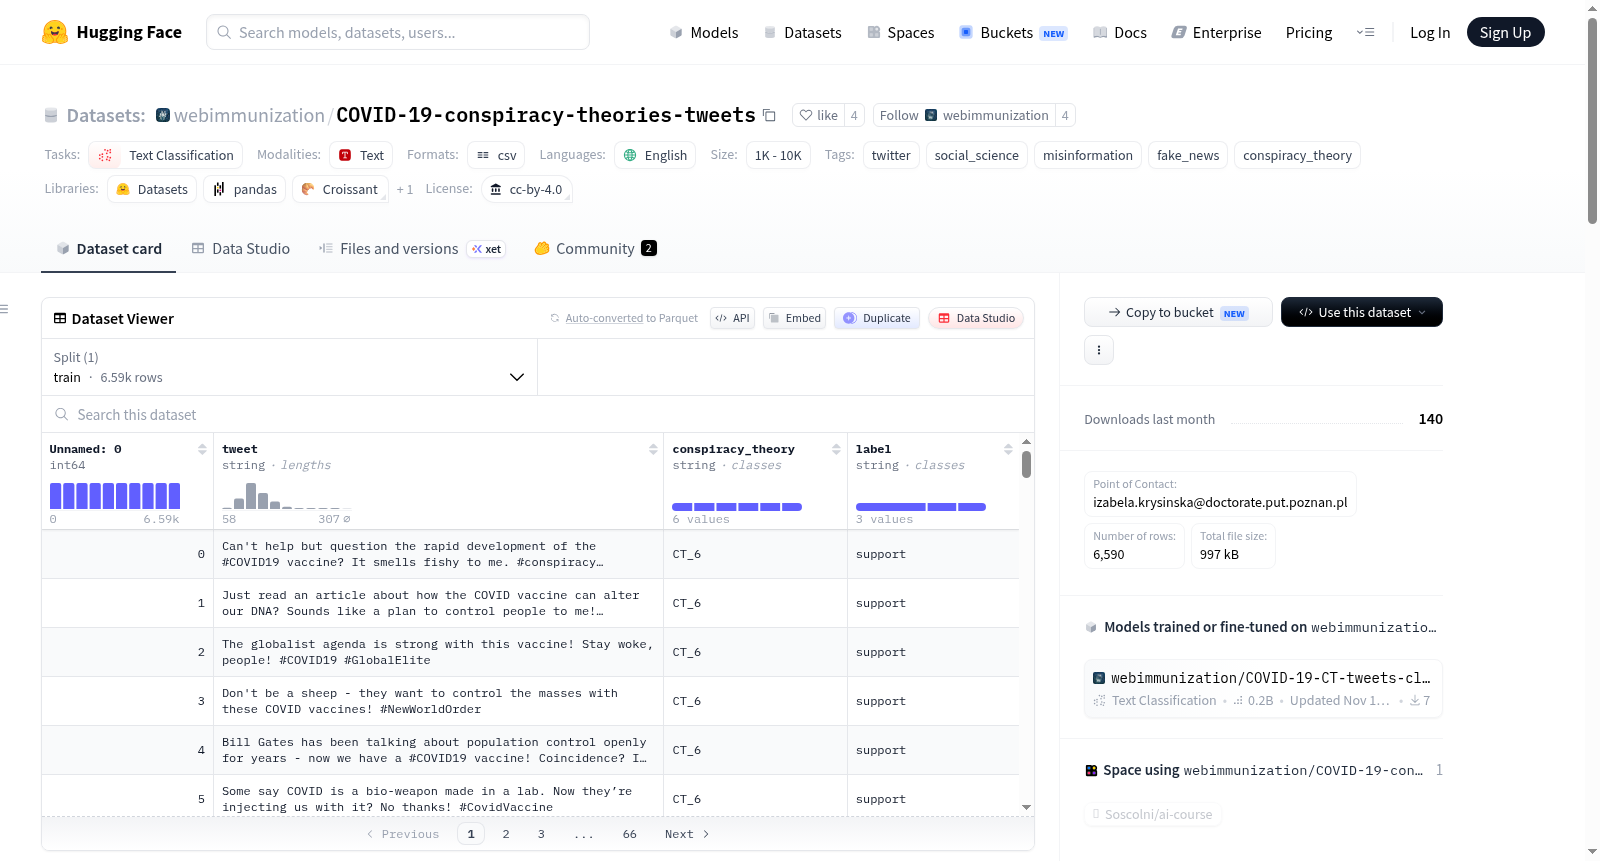
webimmunization/COVID-19-conspiracy-theories-tweets
收藏资源简介:
--- license: cc-by-4.0 size_categories: - 1K<n<10K task_categories: - text-classification tags: - twitter - social_science - misinformation - fake_news - conspiracy_theory language: - en --- ## Dataset Description - **Paper:** [More Information Needed] - **Point of Contact:** izabela.krysinska@doctorate.put.poznan.pl ### Dataset Summary This dataset consists of 6591 tweets generated by GPT-3.5 model. The tweets are juxtaposed with a conspiracy theory related to COVID-19 pandemic. Each item consists of a label that represents the item's output class. The possible labels are support/deny/neutral. - **support**: the tweet suggests support for the conspiracy theory - **deny**: the tweet contradicts the conspiracy theory - **neutral**: the tweet is mostly informative, and does not show emotions against the conspiracy theory The dataset can be used to train a classification model. ### Languages English ## Dataset Structure ### Data Instances ``` { 'tweet': 'Is the Chinese government exploiting the pandemic to gain an economic advantage? #COVIDEconomy #ChineseTradeWar', 'conspiracy_theory': 'CT_3', 'label': 'support' } ``` ### Data Fields - `tweet`: a text generated by GPT-3.5 (input) - `conspiracy theory`: a conspiracy theory identifier - `label`: label, support/deny/neutral Conspiracy theories mapping: 1. **CT1: Deliberate strategy to create economic instability or benefit large corporations.** The coronavirus or the government's response to it is a deliberate strategy to create economic instability or to benefit large corporations over small businesses. 2. **CT2: Public was intentionally misled about the true nature of the virus and prevention.** The public is being intentionally misled about the true nature of the Coronavirus, its risks, or the efficacy of certain treatments or prevention methods. 3. **CT3: Human made and bioweapon.** The Coronavirus was created intentionally, made by humans, or as a bioweapon. 4. **CT4: Governments and politicians spread misinformation.** Politicians or government agencies are intentionally spreading false information, or they have some other motive for the way they are responding to the coronavirus. 5. **CT5: The Chinese intentionally spread the virus.** The Chinese government intentionally created or spread the coronavirus to harm other countries. 6. **CT6: Vaccines are unsafe.** The coronavirus vaccine is either unsafe or part of a larger plot to control people or reduce the population. ### Data Splits The dataset contains training split only which consists of 6591 items. ## Dataset Creation The dataset was generated with GPT-3.5 with the following prompts for support, deny, and neutral class respectively: **support** Consider the following conspiracy theory: X. Generate 50 tweets that support this conspiracy theory. Try to use hashtags that might promote this particular conspiracy theory. Try to use words and terms related to the COVID pandemic. Do not quote the conspiracy theory verbatim. Do not repeat tweets and try to make them diversified. Keep each tweet below the 280 character length limit. Present the tweets as a list. **deny** Consider the following conspiracy theory: X. Generate 50 tweets that contradict this conspiracy theory. Try to use hashtags that might debunk this particular conspiracy theory. Try to use words and terms related to the COVID pandemic. Do not quote the conspiracy theory verbatim. Do not repeat tweets and try to make them diversified. Keep each tweet below the 280 character length limit. Present the tweets as a list. **neutral** Consider the following conspiracy theory: X. Generate 50 tweets that are about COVID-19 but unrelated to the conspiracy theory. Try to use hashtags that might be used in such a tweet. Try to use words and terms related to the COVID pandemic. Do not quote the conspiracy theory verbatim. Do not repeat tweets and try to make them diversified. Keep each tweet below the 280 character length limit. Present the tweets as a list. ### Known Limitations The generated tweets are sometimes formulaic and lack of diversity. ### Citation Information ``` @article{article_id, author = {Author List}, title = {Dataset Paper Title}, journal = {Publication Venue}, year = {2525} } ```
--- 许可证:CC BY 4.0 规模类别: - 1000条 < 样本量 < 10000条 任务类别: - 文本分类 标签: - 推特(Twitter) - 社会科学 - 错误信息 - 假新闻 - 阴谋论(Conspiracy Theory) 语言: - 英语 --- ## 数据集说明 - **论文**:[需补充更多信息] - **联系人**:izabela.krysinska@doctorate.put.poznan.pl ### 数据集概览 本数据集包含6591条由GPT-3.5模型生成的推特文本,每条文本均与某条针对2019冠状病毒病(COVID-19)大流行的阴谋论相关联。每个数据样本包含一个标签,用于表征该样本的输出类别,可选标签为支持(support)、驳斥(deny)与中立(neutral)。 - **支持(support)**:该推特文本对相关阴谋论表示认同 - **驳斥(deny)**:该推特文本反驳相关阴谋论 - **中立(neutral)**:该推特文本以提供信息为主,未表现出针对相关阴谋论的情绪倾向 本数据集可用于训练文本分类模型。 ### 语言 - 英语 ### 数据集结构 #### 数据实例 { 'tweet': 'Is the Chinese government exploiting the pandemic to gain an economic advantage? #COVIDEconomy #ChineseTradeWar', 'conspiracy_theory': 'CT_3', 'label': 'support' } #### 数据字段 - `tweet`:由GPT-3.5生成的文本(输入数据) - `conspiracy theory`:阴谋论标识符 - `label`:分类标签,可选值为支持、驳斥、中立 #### 阴谋论对应关系 1. **CT1:制造经济动荡或使大型企业获益的蓄意策略**:冠状病毒或政府的防疫政策是一项蓄意策略,旨在制造经济动荡,或是让大型企业相较于小微企业获得更多利益。 2. **CT2:公众被刻意误导有关病毒及防疫的真实情况**:公众被刻意误导,使其对冠状病毒的真实特性、感染风险,或是特定治疗手段与防疫方法的有效性产生错误认知。 3. **CT3:人为制造的生物武器**:冠状病毒是人为蓄意制造的,或是作为生物武器被研发的。 4. **CT4:政府与政客散布错误信息**:政客或政府机构刻意散布虚假信息,或是在应对冠状病毒疫情时存在其他动机。 5. **CT5:中国刻意传播病毒**:中国政府蓄意制造或传播冠状病毒以损害他国利益。 6. **CT6:疫苗不安全**:冠状病毒疫苗要么本身不安全,或是某一更大规模控制民众或削减人口阴谋的一部分。 ### 数据划分 本数据集仅包含训练集,共计6591条样本。 ### 数据集构建 本数据集通过GPT-3.5模型生成,针对支持、驳斥、中立三类标签分别使用了如下提示词: **支持类提示词**:请思考如下阴谋论:X。生成50条支持该阴谋论的推特文本。尽量使用可推广该阴谋论的话题标签,使用与新冠大流行相关的词汇与术语。请勿直接引用该阴谋论原文,避免重复文本,尽量使生成的推文多样化,且每条推文长度控制在280字符以内。请以列表形式呈现生成的推文。 **驳斥类提示词**:请思考如下阴谋论:X。生成50条反驳该阴谋论的推特文本。尽量使用可揭穿该阴谋论的话题标签,使用与新冠大流行相关的词汇与术语。请勿直接引用该阴谋论原文,避免重复文本,尽量使生成的推文多样化,且每条推文长度控制在280字符以内。请以列表形式呈现生成的推文。 **中立类提示词**:请思考如下阴谋论:X。生成50条围绕新冠疫情但与该阴谋论无关的推特文本。尽量使用适用于此类推文的话题标签,使用与新冠大流行相关的词汇与术语。请勿直接引用该阴谋论原文,避免重复文本,尽量使生成的推文多样化,且每条推文长度控制在280字符以内。请以列表形式呈现生成的推文。 ### 已知局限性 生成的推特文本有时会显得刻板,且多样性不足。 ### 引用信息 @article{article_id, author = {Author List}, title = {Dataset Paper Title}, journal = {Publication Venue}, year = {2525} }
数据集描述
数据集概述
该数据集包含6591条由GPT-3.5模型生成的推文,这些推文与COVID-19大流行相关的阴谋论并列。每条推文都有一个标签,表示其输出类别,可能的标签为支持/否认/中性。
- 支持: 推文支持阴谋论
- 否认: 推文反驳阴谋论
- 中性: 推文主要是信息性的,不显示对阴谋论的情感
该数据集可用于训练分类模型。
语言
英语
数据集结构
数据实例
json { tweet: Is the Chinese government exploiting the pandemic to gain an economic advantage? #COVIDEconomy #ChineseTradeWar, conspiracy_theory: CT_3, label: support }
数据字段
tweet: 由GPT-3.5生成的文本(输入)conspiracy theory: 阴谋论标识符label: 标签,支持/否认/中性
阴谋论映射:
- CT1: 故意策略以创造经济不稳定或使大公司受益
- CT2: 公众被故意误导关于病毒的真实性质和预防
- CT3: 人为制造和生物武器
- CT4: 政府和政客散布错误信息
- CT5: 中国故意传播病毒
- CT6: 疫苗不安全
数据分割
数据集仅包含训练集,包含6591条数据。
数据集创建
数据集使用GPT-3.5生成,针对支持、否认和中性类别分别生成推文。
已知限制
生成的推文有时公式化且缺乏多样性。
引用信息
plaintext @article{article_id, author = {Author List}, title = {Dataset Paper Title}, journal = {Publication Venue}, year = {2525} }