open-law-data-thailand/soc-ratchakitcha
收藏资源简介:
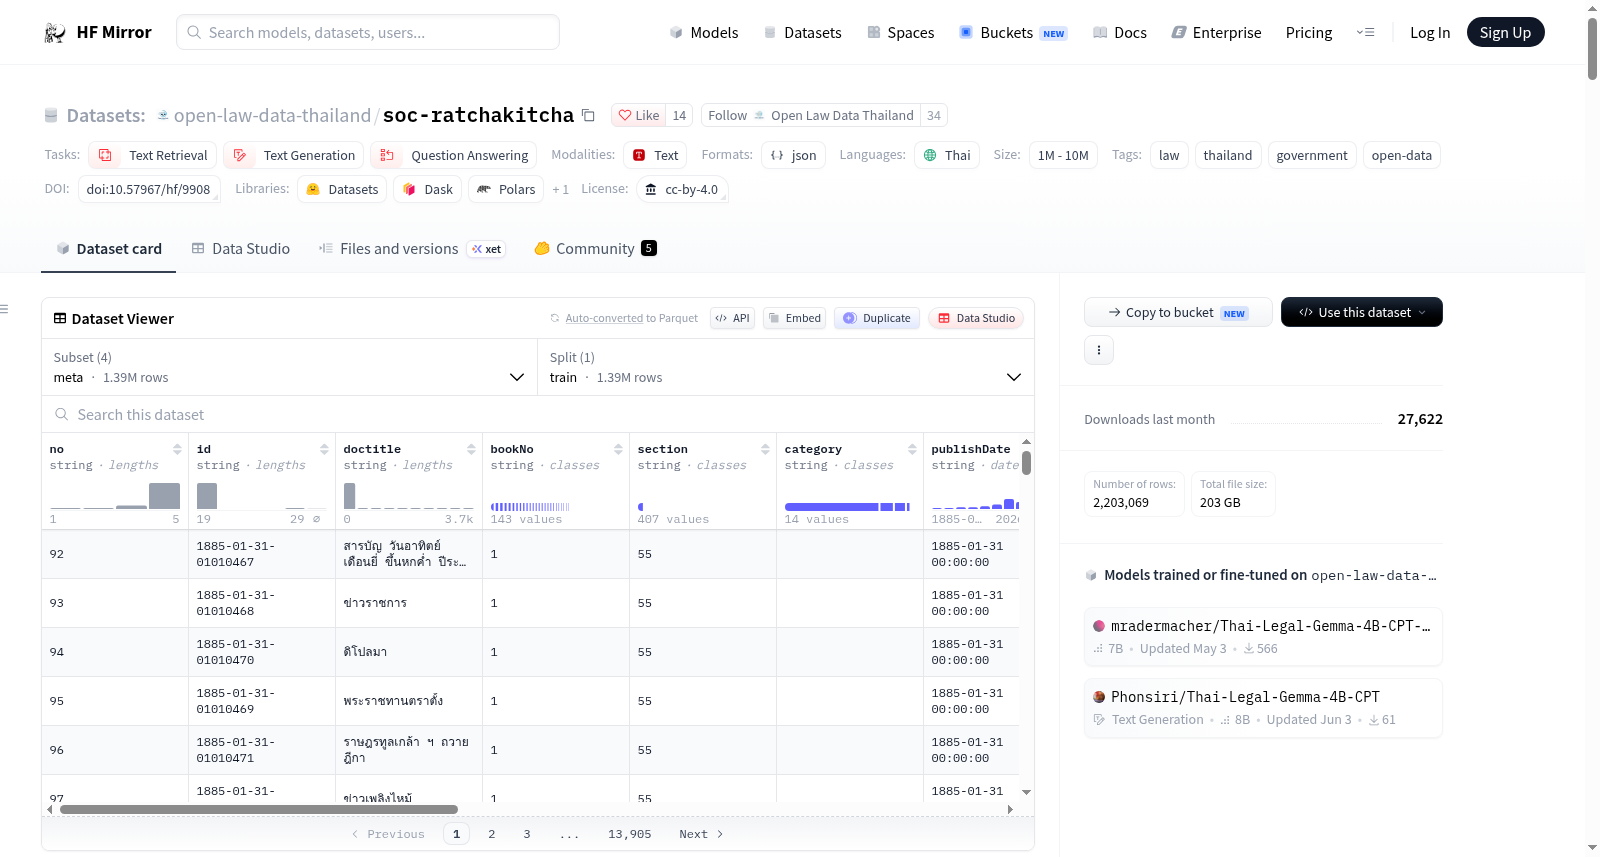
--- license: cc-by-4.0 task_categories: - text-retrieval - text-generation - question-answering language: - th pretty_name: Royal Gazette Thailand (Ratchakitcha) size_categories: - 1M<n<10M tags: - law - thailand - government - open-data dataset_info: # Default configuration config_name: ocr configs: # ========================================================= # MAIN CONFIGURATIONS (Type-based) # ========================================================= # --- Subset: All OCR Data (All Engines, All Years) --- - config_name: ocr data_files: - split: train path: "ocr/**/*.jsonl" # --- Subset: All Metadata --- - config_name: meta data_files: - split: train path: "meta/**/*.jsonl" # --- Subset: Recent PDFs --- - config_name: pdf_recent data_files: - split: train path: "pdf/**/*.pdf" # --- Subset: PDF Archives (ZIP) --- - config_name: pdf_archive data_files: - split: train path: "zip/**/*.zip" # ========================================================= # DECADE SUBSETS (Time-based: OCR + Metadata) # ========================================================= # --- 2020s (2020 - 2029 A.D. / 2563 - 2572 B.E.) --- - config_name: subset_2020s data_files: - split: train path: - "ocr/*/202*/*.jsonl" - "meta/202*/*.jsonl" # --- 2010s (2010 - 2019 A.D. / 2553 - 2562 B.E.) --- - config_name: subset_2010s data_files: - split: train path: - "ocr/*/201*/*.jsonl" - "meta/201*/*.jsonl" # --- 2000s (2000 - 2009 A.D. / 2543 - 2552 B.E.) --- - config_name: subset_2000s data_files: - split: train path: - "ocr/*/200*/*.jsonl" - "meta/200*/*.jsonl" # --- 1990s (1990 - 1999 A.D. / 2533 - 2542 B.E.) --- - config_name: subset_1990s data_files: - split: train path: - "ocr/*/199*/*.jsonl" - "meta/199*/*.jsonl" # --- 1980s (1980 - 1989 A.D. / 2523 - 2532 B.E.) --- - config_name: subset_1980s data_files: - split: train path: - "ocr/*/198*/*.jsonl" - "meta/198*/*.jsonl" # --- 1970s (1970 - 1979 A.D. / 2513 - 2522 B.E.) --- - config_name: subset_1970s data_files: - split: train path: - "ocr/*/197*/*.jsonl" - "meta/197*/*.jsonl" # --- 1960s (1960 - 1969 A.D. / 2503 - 2512 B.E.) --- - config_name: subset_1960s data_files: - split: train path: - "ocr/*/196*/*.jsonl" - "meta/196*/*.jsonl" # --- Historical (Pre-1960 A.D. / Pre-2503 B.E.) --- # Covers 1884 - 1959 - config_name: subset_pre_1960 data_files: - split: train path: - "ocr/*/18*/*.jsonl" - "ocr/*/19[0-5]*/*.jsonl" - "meta/18*/*.jsonl" - "meta/19[0-5]*/*.jsonl" --- # Royal Gazette Thailand (Ratchakitcha) Dataset **ชุดข้อมูลราชกิจจานุเบกษา (แบบ Machine Readable)** โครงการ **Open Law Data Thailand** ร่วมกับคณะกรรมาธิการการพาณิชย์และการอุตสาหกรรม วุฒิสภา ได้รับความอนุเคราะห์ข้อมูลจาก **สำนักเลขาธิการคณะรัฐมนตรี (สลค.)** เพื่อเผยแพร่ข้อมูลกฎหมายไทยสู่สาธารณะในรูปแบบที่ประมวลผลได้ด้วยคอมพิวเตอร์ (Machine Readable) เพื่อส่งเสริมนวัตกรรม Legal Tech และ AI ของประเทศไทย ## Dataset Description ชุดข้อมูลนี้รวบรวมรายการประกาศในราชกิจจานุเบกษา ประกอบด้วยชื่อเรื่อง เล่ม ตอน วันที่ประกาศ และลิงก์ไปยังต้นฉบับ PDF เหมาะสำหรับการทำ RAG (Retrieval-Augmented Generation), การสืบค้นกฎหมาย, และการวิเคราะห์ข้อมูลภาครัฐ - **Source:** สำนักเลขาธิการคณะรัฐมนตรี (The Secretariat of the Cabinet) - **Official Collaboration Reference:** หนังสือด่วนที่สุด ที่ นร ๐๕๐๓/๘๗๓๙ (29 ก.ค. 2568) - **Homepage:** [Open Law Data Thailand](https://www.openlawdatathailand.org/) ## Usage Instruction ท่านสามารถเลือกดาวน์โหลดข้อมูลได้หลายรูปแบบผ่าน Library `datasets` ของ Hugging Face โดยระบุชื่อ `name` ในพารามิเตอร์ (Config) ### 1. สำหรับงาน AI / NLP (แนะนำ) ⭐ หากต้องการข้อความ (Text) เพื่อนำไปเทรนโมเดล หรือทำ Search Engine ท่านสามารถเลือกโหลดข้อมูลแยกเป็น **"รายทศวรรษ"** (Decade Subsets) ได้ ซึ่งจะได้ทั้งไฟล์ OCR และ Metadata ควบคู่กัน ```python from datasets import load_dataset # ตัวอย่าง: โหลดข้อมูลยุคปัจจุบัน (2020 - 2029 / พ.ศ. 2563 - 2572) # จะได้ทั้ง Text (OCR) และ Metadata ds = load_dataset("open-law-data-thailand/soc-ratchakitcha", name="subset_2020s") print(ds['train'][0]) ```` **รายชื่อ Subset ที่รองรับ:** * `subset_2020s` (ปัจจุบัน) * `subset_2010s`, `subset_2000s`, `subset_1990s`, ... จนถึง `subset_1960s` * `subset_pre_1960` (ข้อมูลประวัติศาสตร์ก่อนปี 1960/2503) ### 2\. สำหรับการวิเคราะห์ข้อมูล (Metadata Only) หากต้องการวิเคราะห์สถิติ เช่น จำนวนกฎหมายในแต่ละปี หรือค้นหาชื่อเรื่อง โดยไม่ต้องการเนื้อหา Text ```python # โหลดเฉพาะ Metadata ทั้งหมด (ไฟล์เล็ก โหลดเร็ว) ds_meta = load_dataset("open-law-data-thailand/soc-ratchakitcha", name="meta") ``` ### 3\. สำหรับการดึงไฟล์ต้นฉบับ (PDF) ชุดข้อมูลนี้จัดเก็บไฟล์ PDF แบบ **Hot/Cold Storage** เพื่อประสิทธิภาพ: * **`pdf_recent`**: ไฟล์ PDF รายฉบับ **เฉพาะ 3 เดือนล่าสุด** (Hot Data) * **`pdf_archive`**: ไฟล์ PDF ย้อนหลังตั้งแต่ปี 1884 ที่ถูกบีบอัดเป็น **ZIP รายเดือน** (Cold Data) ```python # ตัวอย่าง: โหลด PDF ล่าสุด ds_pdf = load_dataset("open-law-data-thailand/soc-ratchakitcha", name="pdf_recent") ``` ## Data Fields | Field Name | Description (TH) | Description (EN) | | :--- | :--- | :--- | | `no` | ลำดับที่เอกสาร | Document ID / Number | | `doctitle` | ชื่อเรื่องหรือหัวข้อของเอกสาร | Title or topic of the document | | `bookNo` | เล่มของราชกิจจานุเบกษา | Book number | | `section` | ตอนของราชกิจจานุเบกษา | Section number | | `category` | ประเภท (เช่น ก, ข, ง) | Category (e.g., A, B, D) | | `publishDate` | วันที่ประกาศในราชกิจจานุเบกษา | Publication date | | `pageNo` | หมายเลขหน้า | Page number | | `pdf_file` | ชื่อไฟล์ PDF ต้นฉบับ | Filename of the source PDF | ## Legal & License ข้อมูลนี้ได้รับการสนับสนุนจาก **สำนักเลขาธิการคณะรัฐมนตรี** ตามหนังสือตอบข้อหารือ "ด่วนที่สุด ที่ นร ๐๕๐๓/๘๗๓๙" ลงวันที่ 29 กรกฎาคม 2568 เพื่อประโยชน์สาธารณะและการพัฒนาเทคโนโลยีปัญญาประดิษฐ์ (AI) **Disclaimer:** ข้อมูลนี้จัดทำขึ้นเพื่อความสะดวกในการเข้าถึงและวิเคราะห์ข้อมูลเท่านั้น การอ้างอิงทางกฎหมายอย่างเป็นทางการควรตรวจสอบกับต้นฉบับ PDF จากเว็บไซต์ [ratchakitcha.soc.go.th](https://ratchakitcha.soc.go.th/) โดยตรง ## Contact - **Project:** Open Law Data Thailand - **Website:** https://www.openlawdatathailand.org/
This dataset is the Thai Royal Gazette collection, including gazette documents from the year 2427 BE to the present, in PDF format and converted text format via OCR technology. The target users include developers, researchers, legal professionals, and the general public, aiming to provide foundational data for legal technology innovation and to enhance government transparency.