Emotional Voices Database (EmoV)
收藏资源简介:
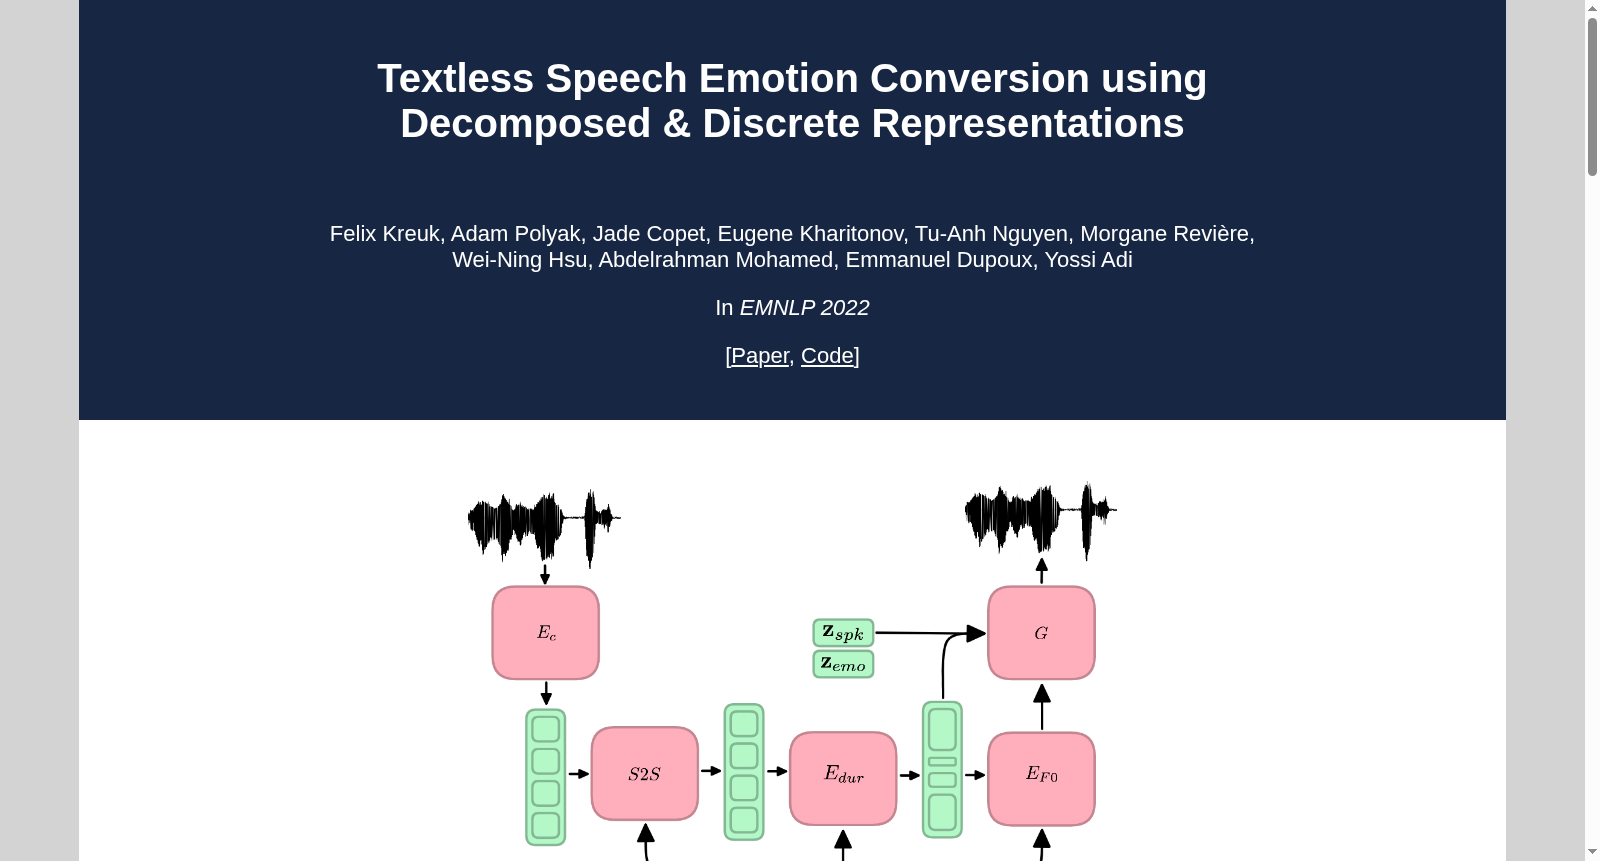
该数据集名为EmoV,包含了7000个语音发音,这些发音基于CMU北极数据库的转录文本,由多位母语者以多种表演情绪录制而成。这使得可以基于相同的转录文本创建发音对,但录制时带有不同的表演情绪。此外,该数据集被划分为训练集、验证集和测试集,比例分别为90%、5%和5%,确保了各集合之间发音的不重叠。该数据集的规模为78,324对,其任务是语音情感转换。
This dataset is named EmoV. It consists of 7,000 speech utterances derived from the transcriptions of the CMU Arctic Database, recorded by multiple native speakers with a variety of acted emotions. This enables the creation of utterance pairs that share the exact same transcription text but are recorded with different acted emotions. Furthermore, the dataset is split into training, validation, and test sets at a ratio of 90%, 5%, and 5% respectively, ensuring no overlapping utterances across these subsets. The total size of the dataset amounts to 78,324 utterance pairs, and its core downstream task is speech emotion conversion.