ImageInWords
收藏资源简介:
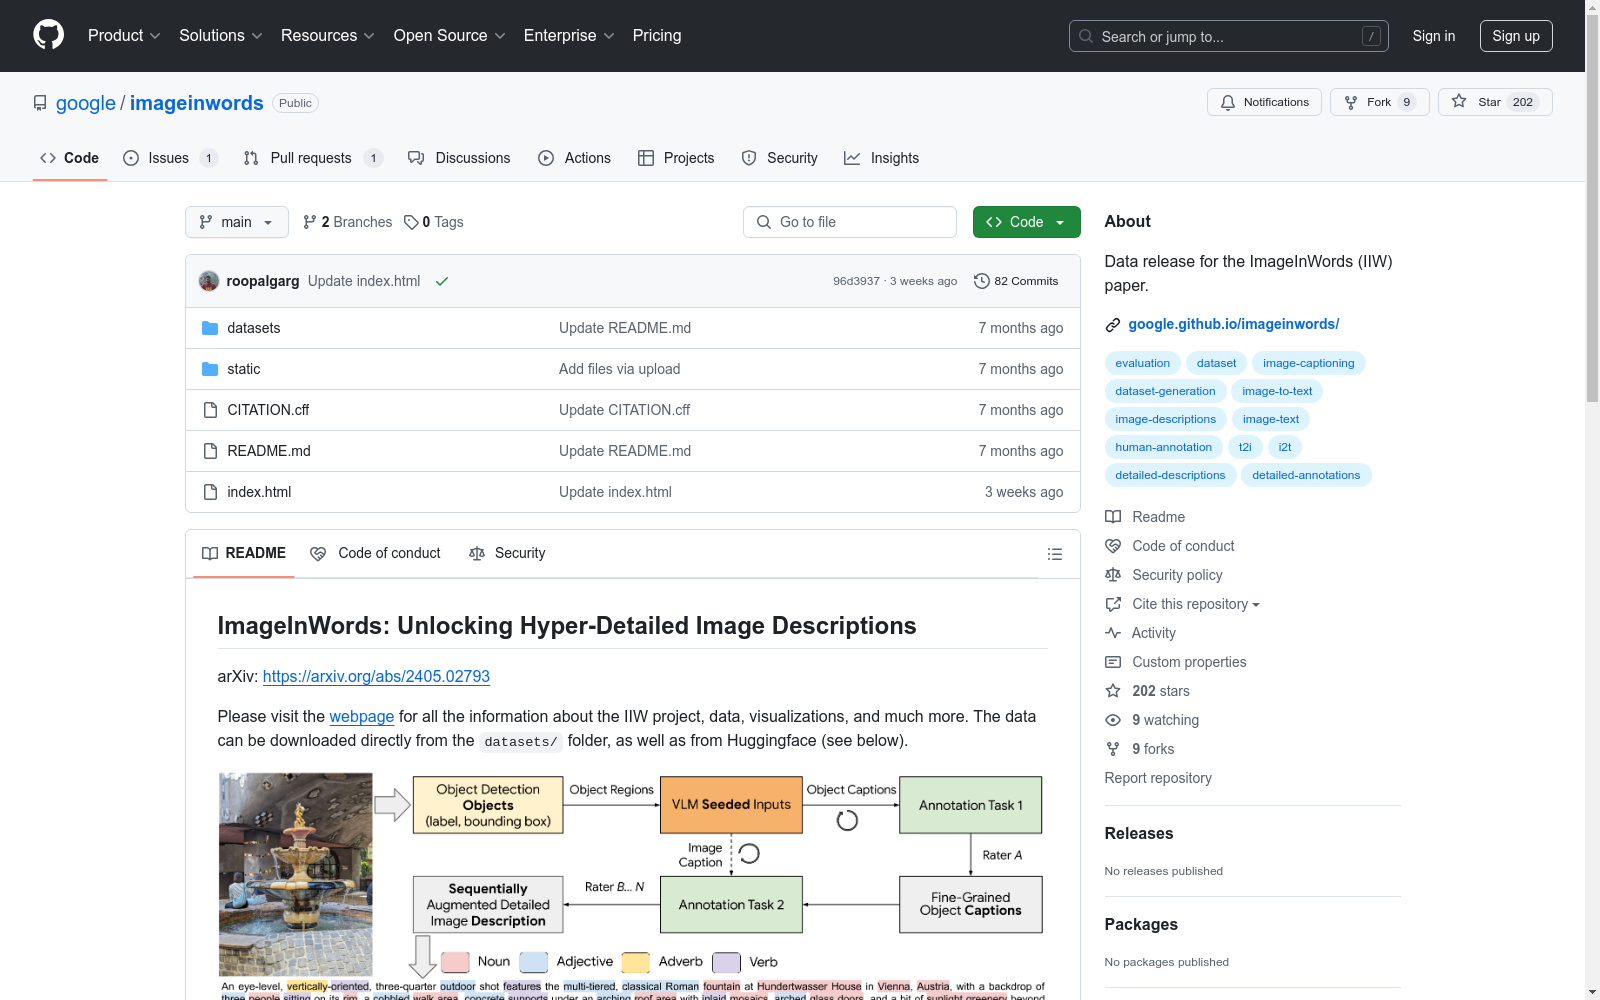
ImageInWords(IIW)数据集,由Google Research与Google DeepMind联合构建,旨在为视觉语言模型的训练提供超详细且无幻觉的图像描述。该数据集包含9018张图片,每张图片均配有详尽的描述,平均每个描述包含9.8个句子、52.5个名词、28个形容词、5个副词和19.1个动词。在创建过程中,IIW采用了迭代式的标注方法,首先通过对象检测器识别图像中的个体对象实例,然后由视觉语言模型生成每个检测到的对象的细粒度标题,作为人工注解过程的起点。随后,通过多轮人工注解和模型微调,逐步丰富和完善描述内容,直至形成一个高质量的数据集。IIW数据集有助于提高文本到图像生成任务的性能,并在视觉-语言组合推理任务中展现了更高的准确性。
The ImageInWords (IIW) dataset, jointly constructed by Google Research and Google DeepMind, aims to provide highly detailed and hallucination-free image descriptions for the training of visual language models. This dataset comprises 9,018 images, each accompanied by an exhaustive description, averaging 9.8 sentences, 52.5 nouns, 28 adjectives, 5 adverbs, and 19.1 verbs per description. During its creation, IIW employed an iterative annotation process, initially using an object detector to identify individual object instances within images, followed by the generation of fine-grained captions for each detected object by a visual language model, serving as the starting point for the manual annotation process. Subsequently, through multiple rounds of manual annotation and model fine-tuning, the descriptions were progressively enriched and refined, culminating in a high-quality dataset. The IIW dataset contributes to enhancing the performance of text-to-image generation tasks and demonstrates higher accuracy in visual-language compositional reasoning tasks.
数据集概述
数据集名称
- ImageInWords
数据集描述
- ImageInWords 旨在提供超详细的图像描述。
数据集下载
- 数据可直接从
datasets/文件夹或通过 Hugging Face 下载。
数据集子集
- IIW-400
- DCI_Test
- DOCCI_Test
- CM_3600
- LocNar_Eval
数据集使用
- 使用
datasets库加载数据集,示例代码如下: python from datasets import load_dataset dataset = load_dataset(google/imageinwords, token=None, name="IIW-400", trust_remote_code=True)
数据集许可证
- CC-BY-4.0
数据集引用
-
若使用或引用此数据集,请使用以下引用信息:
@misc{garg2024imageinwords, title={ImageInWords: Unlocking Hyper-Detailed Image Descriptions}, author={Roopal Garg and Andrea Burns and Burcu Karagol Ayan and Yonatan Bitton and Ceslee Montgomery and Yasumasa Onoe and Andrew Bunner and Ranjay Krishna and Jason Baldridge and Radu Soricut}, year={2024}, eprint={2405.02793}, archivePrefix={arXiv}, primaryClass={cs.CV} }