juwel07/formai-v2-full
收藏资源简介:
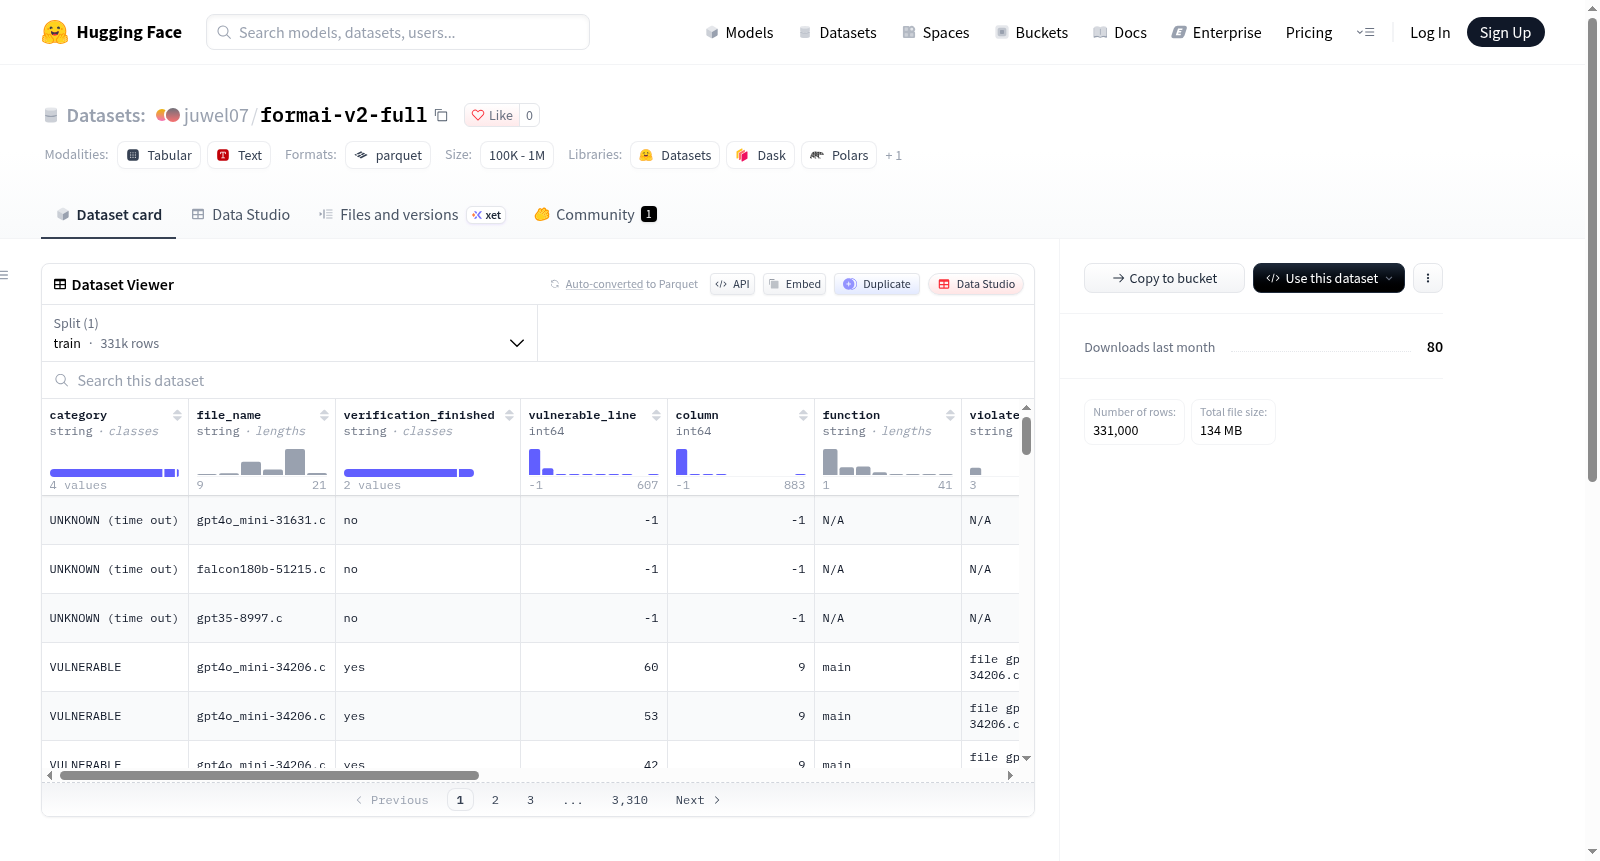
--- dataset_info: features: - name: category dtype: string - name: file_name dtype: string - name: verification_finished dtype: string - name: vulnerable_line dtype: int64 - name: column dtype: int64 - name: function dtype: string - name: violated_property dtype: string - name: error_type dtype: string - name: code_snippet dtype: string - name: source_code dtype: string - name: num_lines dtype: int64 - name: cyclomatic_complexity dtype: float32 splits: - name: train num_bytes: 960684901 num_examples: 331000 download_size: 133615536 dataset_size: 960684901 configs: - config_name: default data_files: - split: train path: data/train-* --- # Dataset Card for Dataset Name <!-- Provide a quick summary of the dataset. --> Lanuage model generated c code with security vulnerabilities From ### Dataset Sources [optional] <!-- Provide the basic links for the dataset. --> - **Repository:** https://github.com/FormAI-Dataset/FormAI-dataset/?tab=readme-ov-file - **Paper:** https://dl.acm.org/doi/10.1145/3617555.3617874 ## Citation [optional] <!-- If there is a paper or blog post introducing the dataset, the APA and Bibtex information for that should go in this section. --> **BibTeX:** @inproceedings{10.1145/3617555.3617874, author = {Tihanyi, Norbert and Bisztray, Tamas and Jain, Ridhi and Ferrag, Mohamed Amine and Cordeiro, Lucas C. and Mavroeidis, Vasileios}, title = {The FormAI Dataset: Generative AI in Software Security through the Lens of Formal Verification}, year = {2023}, isbn = {9798400703751}, publisher = {Association for Computing Machinery}, address = {New York, NY, USA}, url = {https://doi.org/10.1145/3617555.3617874}, doi = {10.1145/3617555.3617874}, booktitle = {Proceedings of the 19th International Conference on Predictive Models and Data Analytics in Software Engineering}, pages = {33–43}, numpages = {11}, keywords = {Artificial Intelligence, Dataset, Formal Verification, Large Language Models, Software Security, Vulnerability Classification}, location = {<conf-loc>, <city>San Francisco</city>, <state>CA</state>, <country>USA</country>, </conf-loc>}, series = {PROMISE 2023} }
The FormAI dataset consists of C code generated by language models with security vulnerabilities, analyzed through formal verification methods. It is designed to explore the application of generative AI in software security, particularly from the perspective of formal verification. The dataset includes multiple feature fields such as category, file name, verification finished status, vulnerable line number, column, function, violated property, error type, code snippet, source code, number of lines, and cyclomatic complexity, which detail the security vulnerability attributes of each code sample. It can be used for tasks like vulnerability classification, software security analysis, and machine learning model training.