potsawee/lfm-audio-fc-5500
收藏资源简介:
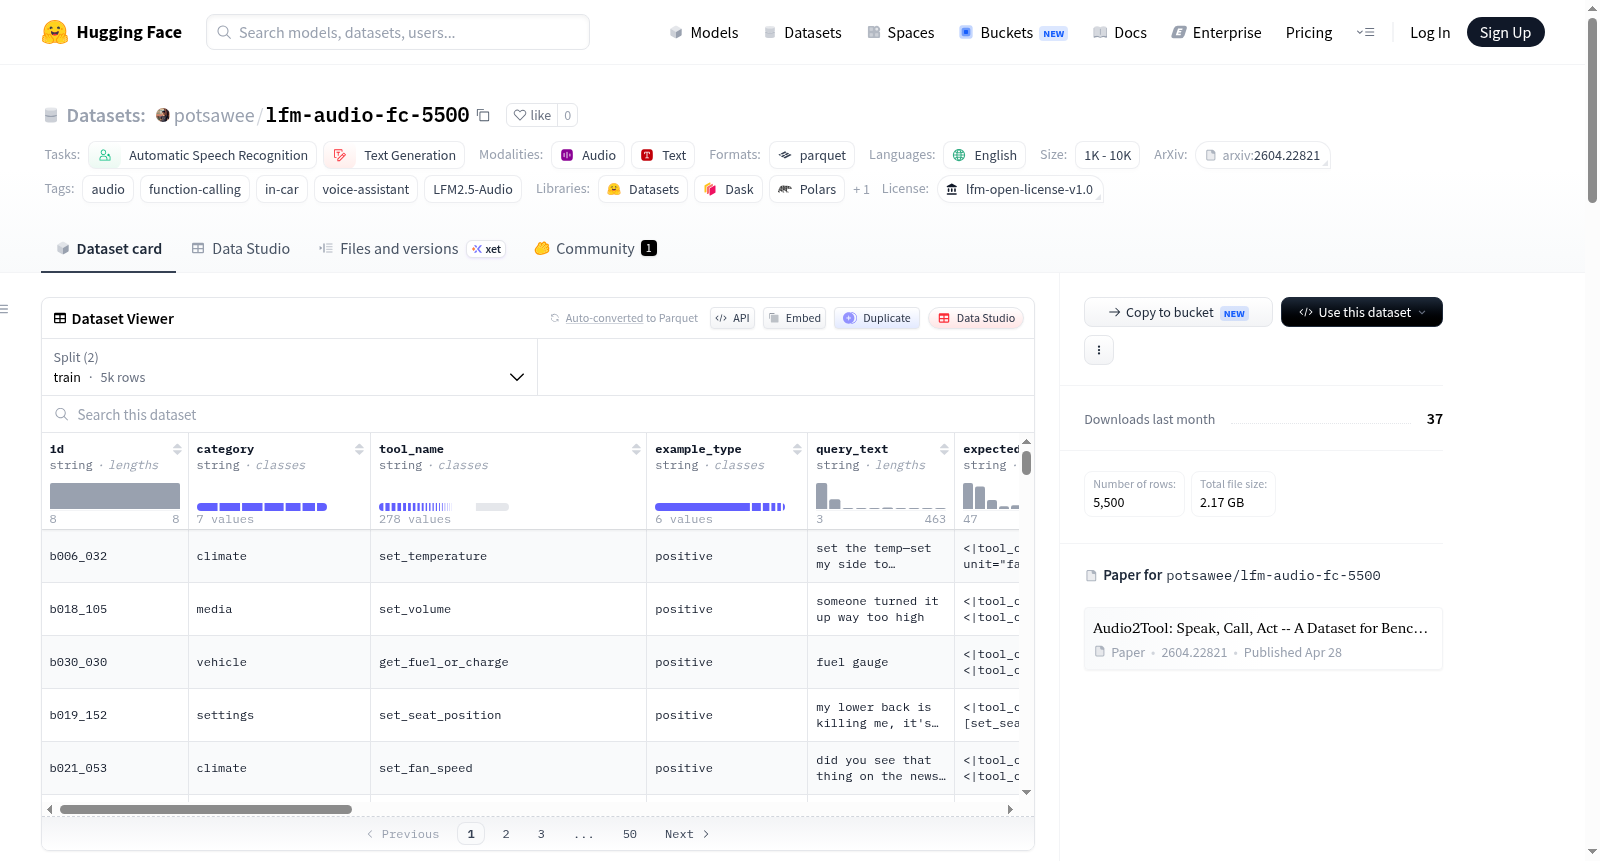
这是一个车内语音功能调用数据集,包含5500个合成示例,用于微调LFM2.5-Audio-1.5B模型,实现端到端的音频输入/工具调用输出功能调用。数据集分为训练集(5000个示例)和评估集(500个示例),涵盖25个车内功能工具,分为7个类别:气候(4个工具)、导航(5个工具)、媒体(5个工具)、电话(3个工具)、车辆(5个工具)、设置(3个工具)和对话回退(无工具调用)。音频数据使用Kokoro TTS生成,包含28种英语语音,每个语音最多占5%。数据集按照Audio2Tool框架分为8个复杂度层级,包括直接命令、参数命令、多意图、隐式/语用命令、长闲聊加命令、自我纠正、多轮对话和意图混合。数据格式包括用户音频(数组、采样率、路径)、预期工具调用(格式为<|tool_call_start|>[func(args)]<|tool_call_end|>)、预期响应(口语确认文本)和复杂度层级(1-8)。多轮示例包含prior_turns_json字段,需解析音频路径。生成过程涉及文本合成(使用Claude Code会话,按层级、类别和示例类型分层)和音频生成(Kokoro TTS v1.0,确定性语音分配,背景语音混合在-10 dB)。数据集仅限英语,音频为合成,无真实车内声学或环境噪声,工具数量有限,适用于原型开发。许可证为LFM Open License v1.0。
Synthetic dataset of in-vehicle voice queries paired with tool calls, designed for fine-tuning LFM2.5-Audio-1.5B for end-to-end audio-in / tool-call-out function calling. It contains 5500 examples, with 5000 for training and 500 for evaluation. The dataset includes 25 in-car function tools across 7 categories: Climate (4 tools), Navigation (5 tools), Media (5 tools), Phone (3 tools), Vehicle (5 tools), Settings (3 tools), and Conversational fallback (no tool call). Audio is generated using Kokoro TTS with 28 English voices, each voice limited to a maximum of 5%. The dataset is organized into 8 complexity tiers based on the Audio2Tool framework, including direct commands, parametric commands, multi-intent, implicit/pragmatic commands, needle-in-haystack (long chatter with command), self-correction, multi-turn (4-8 turns with prior_turns), and intent blending (primary + background speaker). Data format includes user_audio (array, sampling_rate, path), expected_tool_call (formatted as <|tool_call_start|>[func(args)]<|tool_call_end|>), expected_response (spoken confirmation text), and complexity_tier (1-8). Multi-turn examples include a prior_turns_json field, requiring resolution of audio_path against the audio/ folder. Generation involves text synthesis (via Claude Code session, stratified across tiers, categories, and example types) and audio generation (Kokoro TTS v1.0, deterministic voice per example ID, background voice mixed at -10 dB). The dataset is English-only, uses synthetic audio without real cabin acoustics or environmental noise, and has a limited tool taxonomy for prototyping. License is LFM Open License v1.0.