DexGraspVLA 机器人抓握数据集
收藏资源简介:
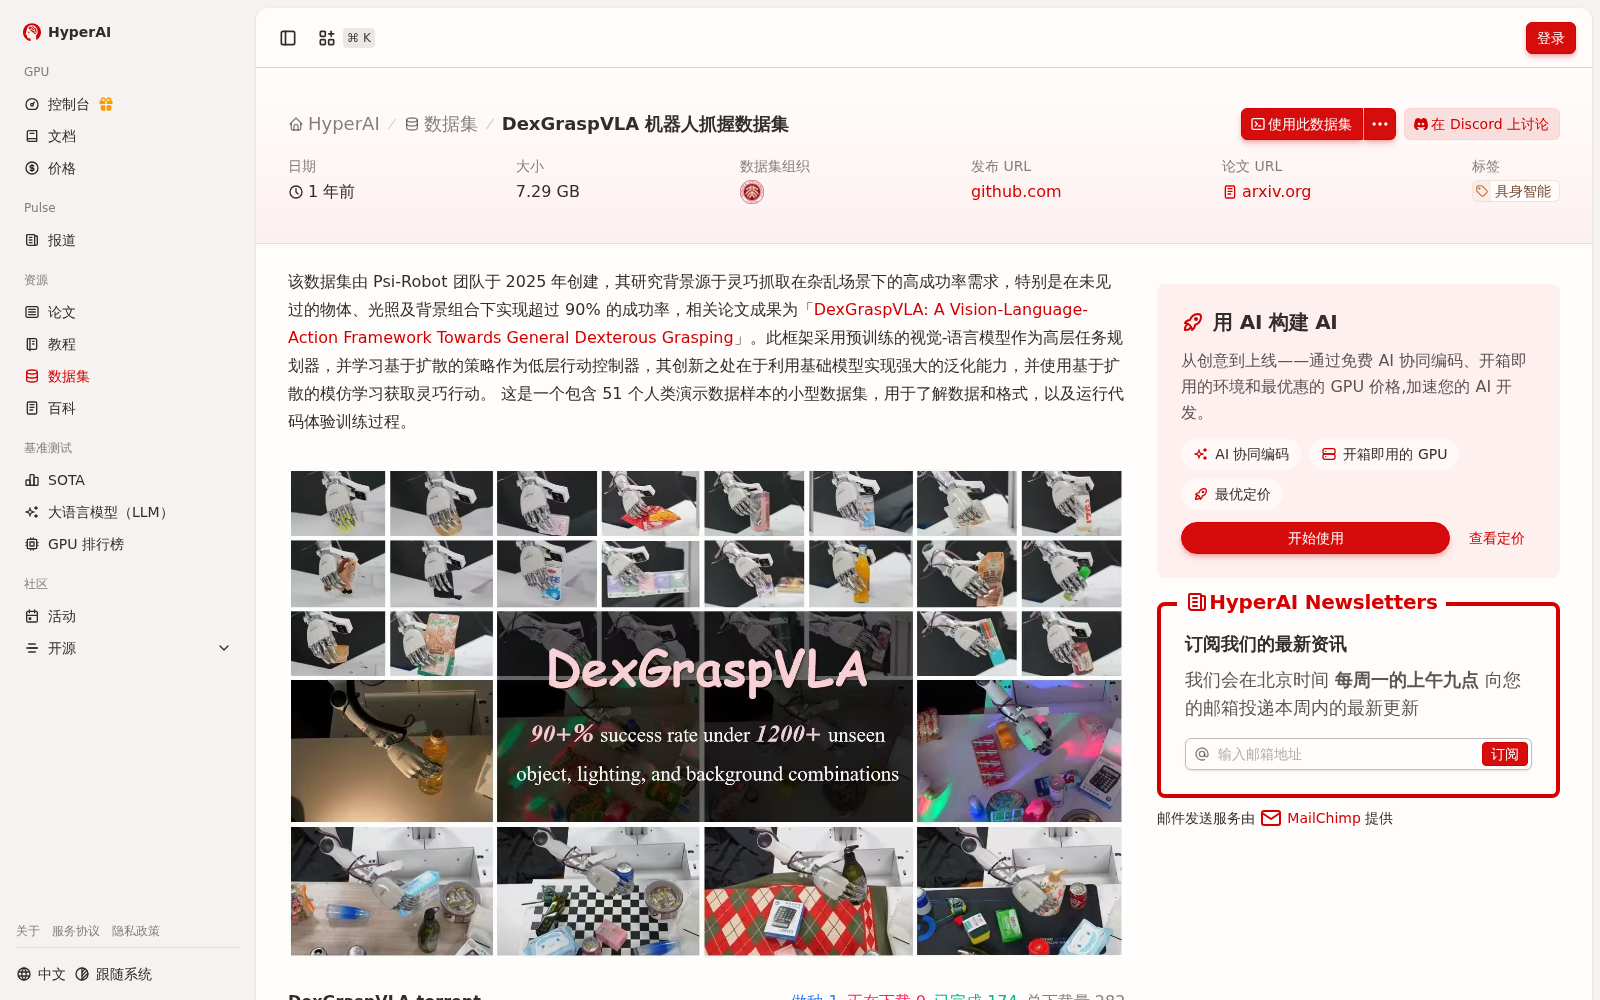
该数据集由 Psi-Robot 团队于 2025 年创建,其研究背景源于灵巧抓取在杂乱场景下的高成功率需求,特别是在未见过的物体、光照及背景组合下实现超过 90% 的成功率,相关论文成果为「DexGraspVLA: A Vision-Language-Action Framework Towards General Dexterous Grasping」。此框架采用预训练的视觉-语言模型作为高层任务规划器,并学习基于扩散的策略作为低层行动控制器,其创新之处在于利用基础模型实现强大的泛化能力,并使用基于扩散的模仿学习获取灵巧行动。
This dataset was developed by the Psi-Robot team in 2025. Its research background originates from the demand for high success rates of dexterous grasping in cluttered scenes, specifically achieving a success rate exceeding 90% when encountering unseen objects, lighting conditions, and background contexts. The associated academic paper is titled "DexGraspVLA: A Vision-Language-Action Framework Towards General Dexterous Grasping". This framework employs a pre-trained vision-language model as the high-level task planner, and learns diffusion-based policies to serve as the low-level action controller. Its core innovation lies in leveraging foundation models to enable robust generalization abilities, and adopting diffusion-based imitation learning to acquire dexterous grasping actions.