ego2act-bench
收藏资源简介:
Ego2Act Benchmark是一个用于评估以目标为导向的操作的自我中心视频生成基准。它要求视频模型基于单张自我中心起始帧和一个高层次目标(例如“笔记本电脑盖打开,钥匙和笔一起放在笔记本电脑左侧”)生成真实的多步操作视频。该数据集包含任务本身以及人类参考录制视频。cases子集(默认)每行对应一个任务,包含任务标识符、起始图像、目标描述、生成提示、领域(如厨房/食物准备、办公室/学习空间、家庭组织/存储、个人护理/公用设施等)、所需动作类型、动作族、物体族、涉及物体数量、人类成功录制的平均操作步数、平均时长,以及各类视频数量。人类录制视频位于human/目录下,以480p H.264格式提供,每项任务最多有3个成功和3个失败的模拟录制视频。数据集用于评估图像到视频模型作为目标导向操作模拟器的性能,以及研究自动视频评估器。数据规模小于1000个样本。许可为CC BY 4.0。
The Ego2Act Benchmark is a benchmark for evaluating goal-oriented action in egocentric video generation. It requires video models to generate realistic multi-step operation videos based on a single egocentric starting frame and a high-level goal (e.g., laptop lid open, keys and pen placed together on the left side of the laptop). The dataset contains task descriptions and human reference recordings. The cases subset (default) has one row per task, including task identifier, starting image, goal description, generation prompt, domain (e.g., kitchen/food preparation, office/study space, home organization/storage, personal care/utilities, etc.), required action type, action family, object family, number of objects involved, average number of operation steps for successful human recordings, average duration, and counts of various videos. Human recordings are in the human/ directory, provided in 480p H.264 format, with up to 3 successful and 3 failed simulated recordings per task. The dataset is used to evaluate image-to-video models as goal-oriented action simulators and to study automatic video evaluators. The data size is less than 1000 samples. License: CC BY 4.0.
Ego2Act Benchmark 数据集概述
基本信息
- 数据集名称:Ego2Act Benchmark
- 许可证:CC BY 4.0(代码为 MIT 许可)
- 语言:英语
- 任务类别:image-to-video、video-classification
- 标签:egocentric、video-generation、world-models、manipulation、benchmark
- 数据规模:n<1K
- 默认配置:cases(data/cases.parquet)
数据集简介
Ego2Act 要求视频模型从单张第一视角(egocentric)起始帧和一个高层级目标出发,执行真实的、多步骤的操作任务(例如“笔记本电脑盖子打开,钥匙和笔一起放在笔记本电脑左侧”)。本仓库包含基准测试本身,即任务与人类参考录像。模型输出及所有评分(Ego2ActJudge、基线及人工评分)位于 ego2act/ego2act-vidgen。
快速开始
python from datasets import load_dataset
cases = load_dataset("ego2act/ego2act-bench", "cases", split="train") print(cases[0]["goal"])
下载所需文件示例:
bash huggingface-cli download ego2act/ego2act-bench --repo-type dataset --include "cases/*" --local-dir ego2act
人类录像为 human/ 下的独立 480p 文件,可逐个任务下载。
子集说明
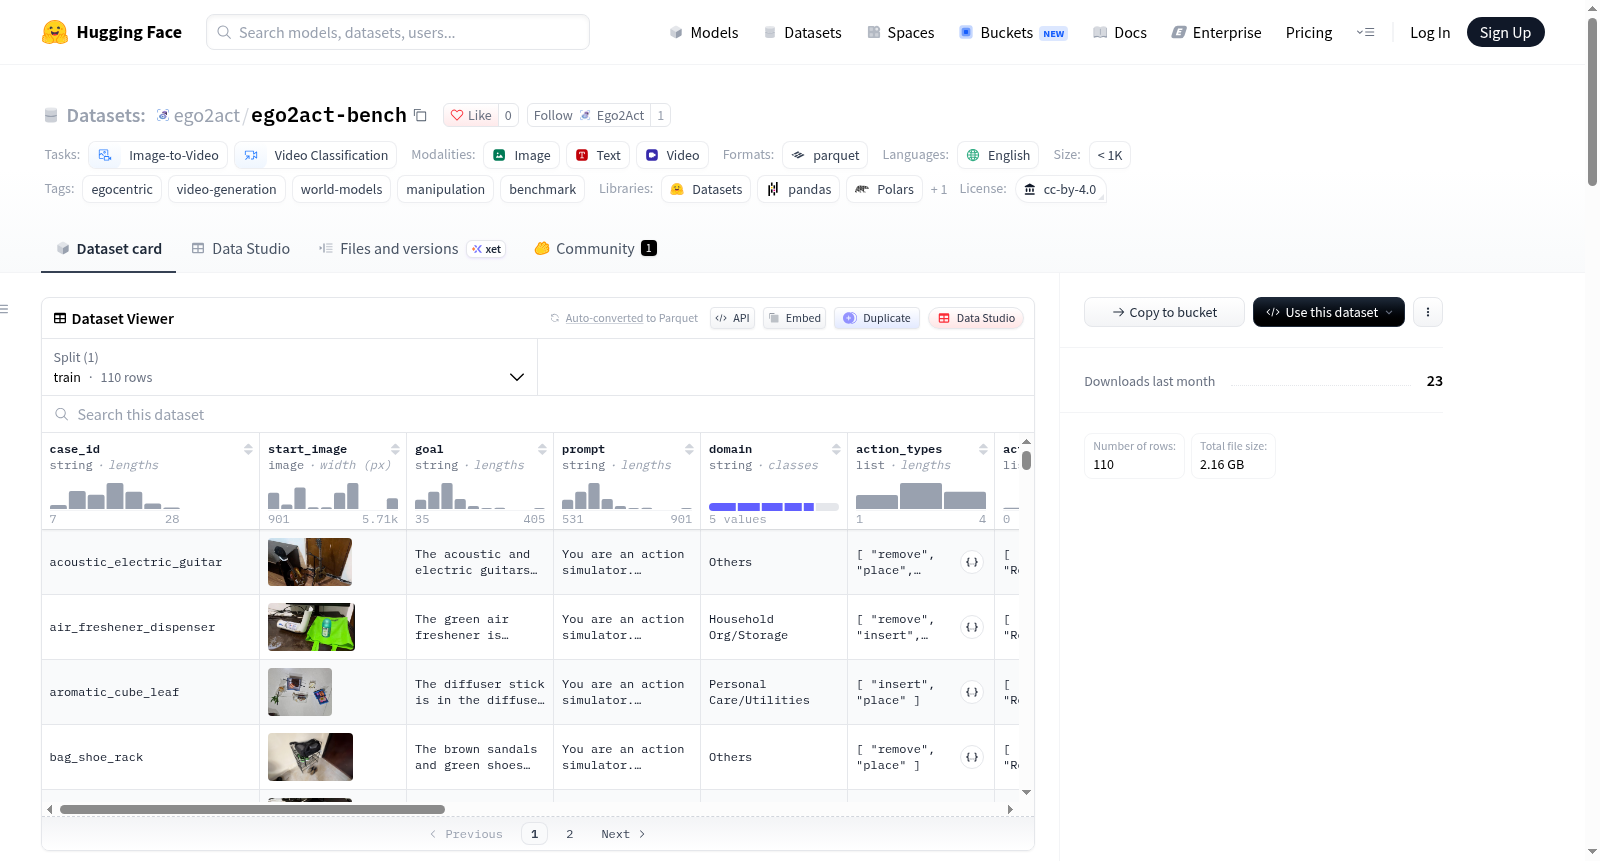
cases(默认),每行一个任务
| 列名 | 类型 | 描述 |
|---|---|---|
case_id |
string | 任务标识符,所有文件和表共享 |
start_image |
image | 提供给每个视频模型的初始第一视角场景 |
goal |
string | 操作必须达成的高层级目标 |
prompt |
string | 精确的生成提示(指令后接目标) |
domain |
string | Kitchen/Food Prep、Office/Study Workspace、Household Org/Storage、Personal Care/Utilities 或 Others,未标注时为空 |
action_types |
list[string] | 任务所需的动词,如 open、place、attach |
action_families |
list[string] | 覆盖的动作族,如“Opening, closing and securing” |
object_family |
list[string] | 涉及物体的类别 |
involved_object_count |
int | 涉及的实体物体数量 |
mean_observed_steps |
float | 成功人类录像中的平均操作步骤数 |
mean_human_duration_s |
float | 成功人类录像的平均时长(秒) |
n_human_correct、n_human_wrong、n_generated |
int | 该任务各类视频数量,n_generated 统计 ego2act-vidgen 中的视频 |
in_human_panel |
bool | 该任务是否属于 25 任务人工评分面板 |
人类录像,human/metadata.csv
480p 录像索引于 human/metadata.csv,每行一条录像。
| 列名 | 类型 | 描述 |
|---|---|---|
file_name |
string | human/ 下 480p H.264 录像路径(24 fps,无音频) |
video_id |
string | <case_id>::correct_<n> 或 <case_id>::wrong_<n>,所有评分表使用的键 |
case_id |
string | 任务 |
label |
string | correct 达成目标,wrong 为逼真的失败尝试 |
duration_s、width、height |
float、int | 从文件中测量得出 |
大多数任务有三条 correct 和三条 wrong 录像,部分数量更少或更多(计数见 n_human_correct 和 n_human_wrong)。录像由作者以第一视角拍摄。有两个任务各含一对字节完全相同的副本(bottle_pot_pebble 的 wrong_2 与 wrong_3,three_spice_and_weight 的 correct_1 与 correct_2),两者均保留以使每条录像都有评分。480p 副本是每个评估器(Ego2ActJudge 及所有基线)接收的精确输入。
文件结构
| 路径 | 内容 |
|---|---|
data/cases.parquet |
cases 表 |
cases/<case_id>/ |
start.jpg、prompt.txt 及 metadata.json(目标、动作类型、物体、逐录像备注) |
human/{correct,wrong}/<case_id>/*.mp4 |
480p 人类录像,以 human/metadata.csv 为索引 |
评分方式
Ego2ActJudge 将目标拆分为子目标,并用任务门 T1(initiation)、T2(process)、T3(end state)以及物理门 P1(continuity)、P2(causation)、P3(interaction)、P4(persistence)逐一检查,遇到首个失败即停止。Task 与 Physics 按子目标在 0–100 尺度上取平均,并组合为最终分数 S = √(T · P)。每个视频的分数位于 ego2act-vidgen。
预期用途与局限性
Ego2Act 旨在评估图像到视频模型作为目标导向操作模拟器的能力,以及研究自动视频评判器。任务是由一小组人在有限数量的家庭和办公室中录制的日常桌面操作,因此未覆盖所有环境、手部或相机设置。被录制者同意发布录像。录像仅显示手部和家用物体。
引用
bibtex @article{ego2act2026, title = {Ego2Act: Evaluating Goal-Directed Manipulation in Egocentric Video Generation}, author = {Irawan, Patrick Amadeus and Parlambang, Iskandar Muda Rizky and Maulana, Rava and Cui, Qinrong and Fuadi, Erland Hilman and Zuhri, Zayd M. K. and Absar, Nanda Ryaas and Elshabrawy, Ahmed and Mulyawan, Wilfried Ariel and Yu, Shoubin and Zhang, Yue and Bansal, Mohit and Aji, Alham Fikri}, year = {2026} }