MegaScience
收藏资源简介:
MegaScience是一个包含125万个实例的大规模高质量开源科学推理数据集。它由多个公开数据集混合而成,经过综合的数据选择和清洗过程,为科学推理任务提供了高质量的数据子集。数据集支持训练大规模模型,并在性能上超越了官方的指令模型。
MegaScience is a large-scale high-quality open-source scientific reasoning dataset containing 1.25 million instances. It is curated from multiple public datasets and has undergone a comprehensive data selection and cleaning pipeline, providing high-quality data subsets tailored for scientific reasoning tasks. This dataset supports the training of large-scale models and outperforms official instruction-tuned models in terms of performance.
MegaScience数据集概述
基本信息
- 许可证: CC-BY-NC-SA 4.0
- 任务类别: 文本生成
- 语言: 英语
- 规模: 1M<n<10M
数据集结构
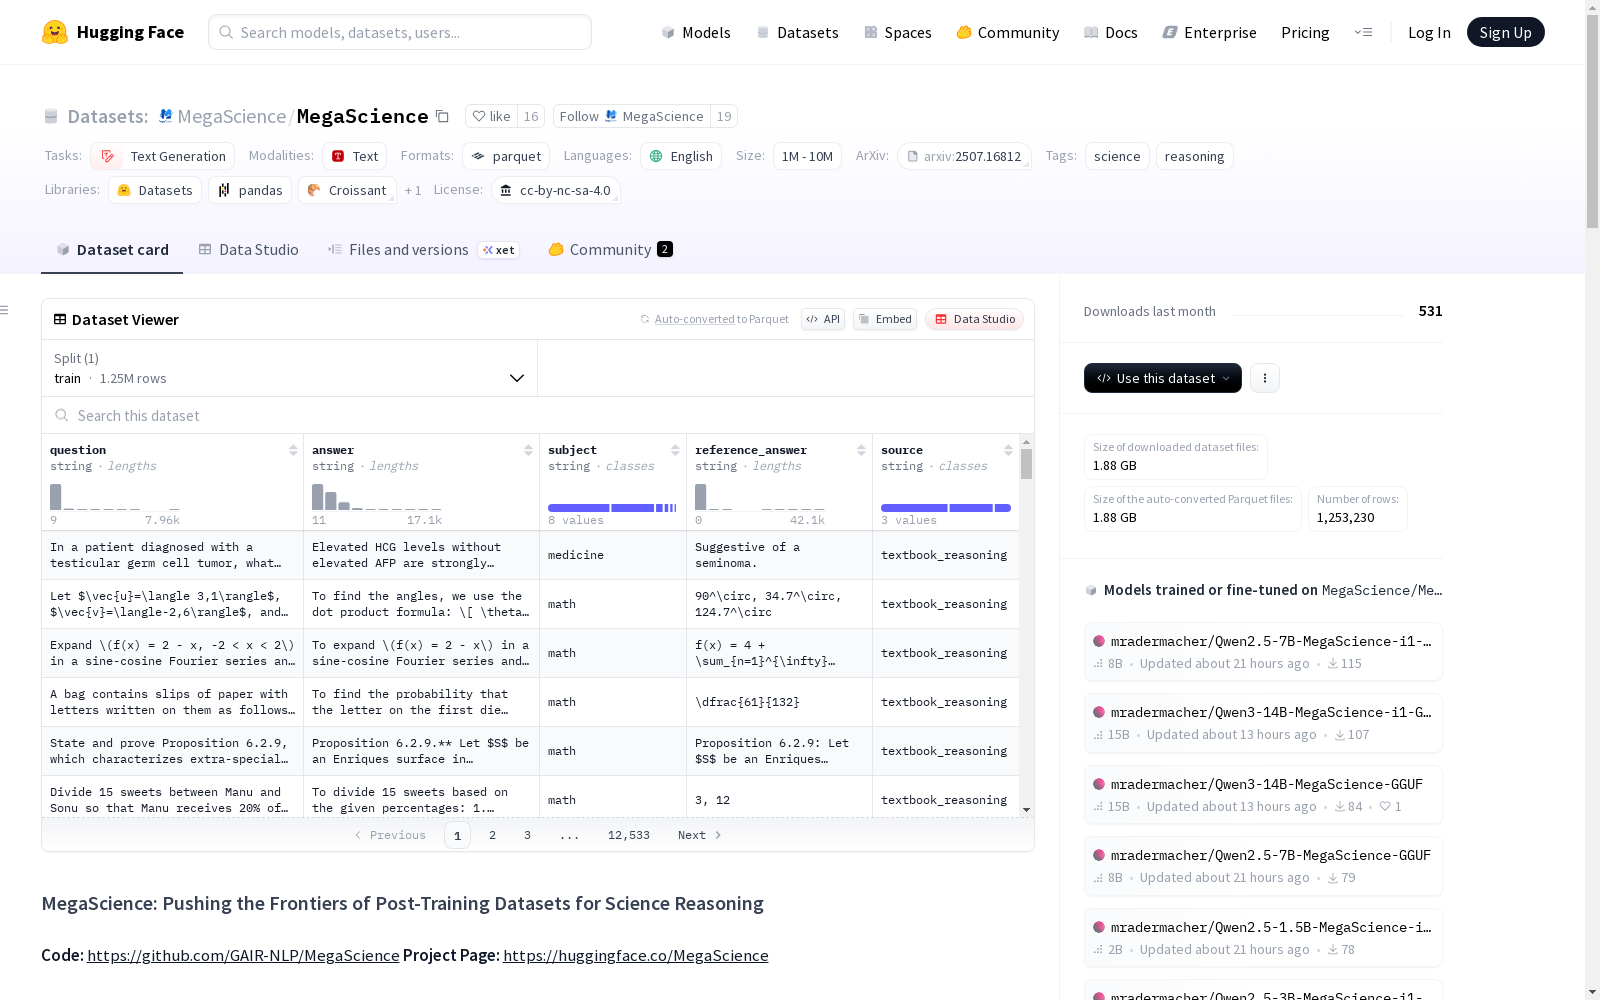
- 特征:
- question (string): 问题
- answer (string): 答案
- subject (string): 主题
- reference_answer (string): 参考答案
- source (string): 来源
- 拆分:
- train:
- 字节数: 3719840088
- 样本数: 1253230
- train:
- 下载大小: 1878947811
- 数据集大小: 3719840088
数据集描述
MegaScience是一个大规模的高质量开源数据集混合体,包含125万个实例。数据集通过以下步骤构建:
- 从NaturalReasoning、Nemotron-Science和TextbookReasoning收集源数据
- 进行问题去重和基于LLM的去污染处理
- 通过全面的消融研究确定每个数据集的最佳数据选择方法
- 使用DeepSeek-V3为NaturalReasoning和Nemotron-Science标注逐步解决方案
应用效果
- 在Llama3.1、Qwen2.5和Qwen3系列基础模型上训练后,其科学推理性能优于官方指导模型
- 对更大更强的模型表现出更好的效果,显示科学指导调优的规模效益
引用
bibtex @article{fan2025megascience, title={MegaScience: Pushing the Frontiers of Post-Training Datasets for Science Reasoning}, author={Fan, Run-Ze and Wang, Zengzhi and Liu, Pengfei}, year={2025}, journal={arXiv preprint arXiv:2507.16812}, url={https://arxiv.org/abs/2507.16812} }
论文链接
https://arxiv.org/abs/2507.16812