Indonesian GEC Evaluation Corpus
收藏资源简介:
本数据集由广东工业大学计算机科学与技术学院的研究团队创建,旨在为印度尼西亚语的语法错误纠正(GEC)任务提供高质量的评估语料。数据集包含了从2007年到2021年从Antara News Agency爬取的631,964篇文章,涵盖科技、政治、法律、经济、体育和人文六个主题,共计7,613,950条句子。创建过程中,研究团队首先使用合成数据训练印度尼西亚语GEC模型,然后应用该模型修正真实新闻语料中的错误,并通过人工标注建立黄金标准评估语料。该数据集主要用于低资源语言的GEC任务,旨在解决印度尼西亚语等低资源语言在NLP研究中缺乏高质量评估语料的问题。
This dataset was developed by a research team from the School of Computer Science and Technology, Guangdong University of Technology, to provide high-quality evaluation corpora for the Indonesian grammatical error correction (GEC) task. It contains 631,964 articles crawled from Antara News Agency spanning from 2007 to 2021, covering six domains: technology, politics, law, economics, sports, and humanities, with a total of 7,613,950 sentences. During the construction of this dataset, the team first trained an Indonesian GEC model using synthetic data, then utilized this model to correct errors in real news corpora, and finally established a gold-standard evaluation corpus through manual annotation. This dataset is primarily designed for GEC tasks in low-resource languages, aiming to resolve the lack of high-quality evaluation corpora for low-resource languages including Indonesian in NLP research.
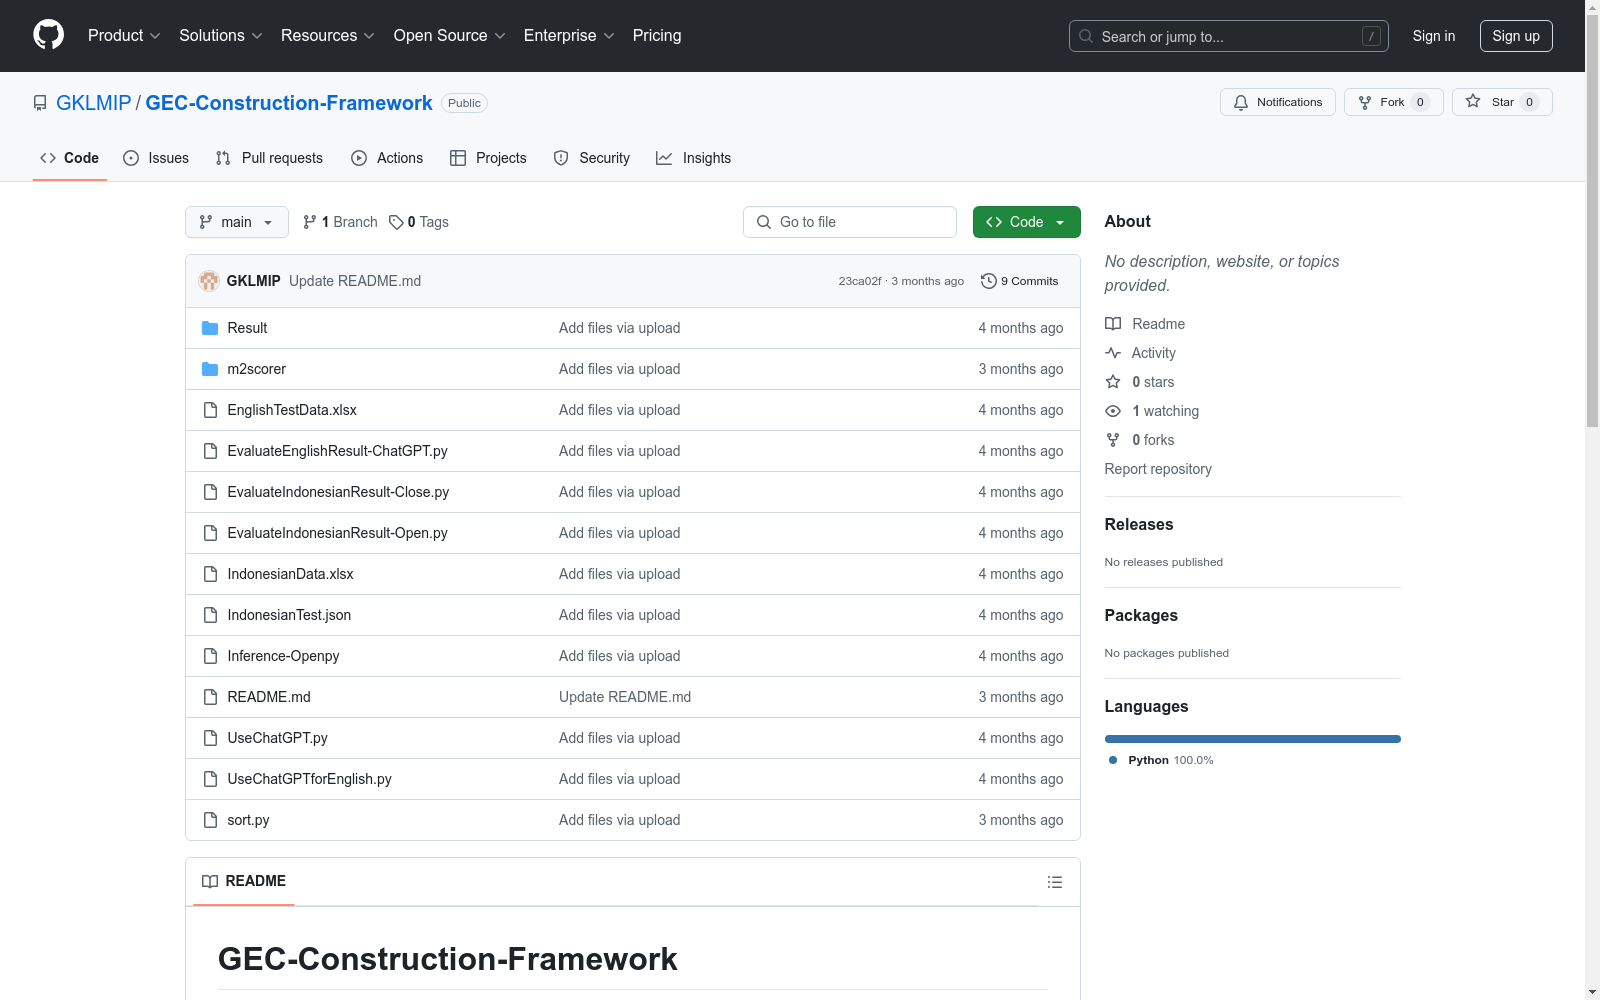
GEC-Construction-Framework 数据集概述
数据集
- 文件名:
IndonesianTest.json - 描述: 自建数据集
模型训练与测试
-
数据来源: 可通过 Google Driver 获取训练数据
-
工具: 使用 Fairseq 版本 0.10.2 进行模型训练和测试
-
训练脚本: bash CUDA_VISIBLE_DEVICES=0 python train.py ./IndoGECDataset --save-dir ./IndoTransformer --seed 4321 --max-epoch 50 --batch-size 64 --max-tokens 4096 --train-subset train --valid-subset valid --arch transformer --lr-scheduler triangular --max-lr 0.004 --lr-period-updates 73328 --clip-norm 2 --lr 0.001 --lr-shrink 0.95 --shrink-min --dropout 0.2 --relu-dropout 0.2 --attention-dropout 0.2 --encoder-embed-dim 512 --decoder-embed-dim 512 --max-target-positions 1024 --max-source-positions 1024 --encoder-ffn-embed-dim 4096 --decoder-ffn-embed-dim 4096 --encoder-attention-heads 8 --decoder-attention-heads 8 --share-all-embeddings --log-interval 1000 --fp16
-
测试脚本: bash python generate.py IndoGECDataset --path IndoTransformer/checkpoint_best.pt --batch-size 512 --beam 5 --remove-bpe > result/nbest.txt --fp16 cat result/nbest.txt | grep "^H" | python ./sort.py 1 result/output.txt python ./m2scorer/m2scorer -v result/output.txt ./IndoGECDataset/gold > result/result.txt
推理与评估
- 使用 GPT3.5 或 GPT4 进行推理:
- 英语:
python UseChatGPTforEnglish.py - 印尼语:
python UseChatGPT.py
- 英语:
- 使用开源 LLMs 进行推理:
python Inference-Open.py - 评估脚本:
- 英语:
python EvaluateEnglishResult-ChatGPT.py - 印尼语 (GPT3.5 或 GPT4):
python EvaluateIndonesianResult-Close.py - 印尼语 (开源 LLMs):
python EvaluateIndonesianResult-Open.py
- 英语: