zhifeixie/StreamAudio-2M
收藏资源简介:
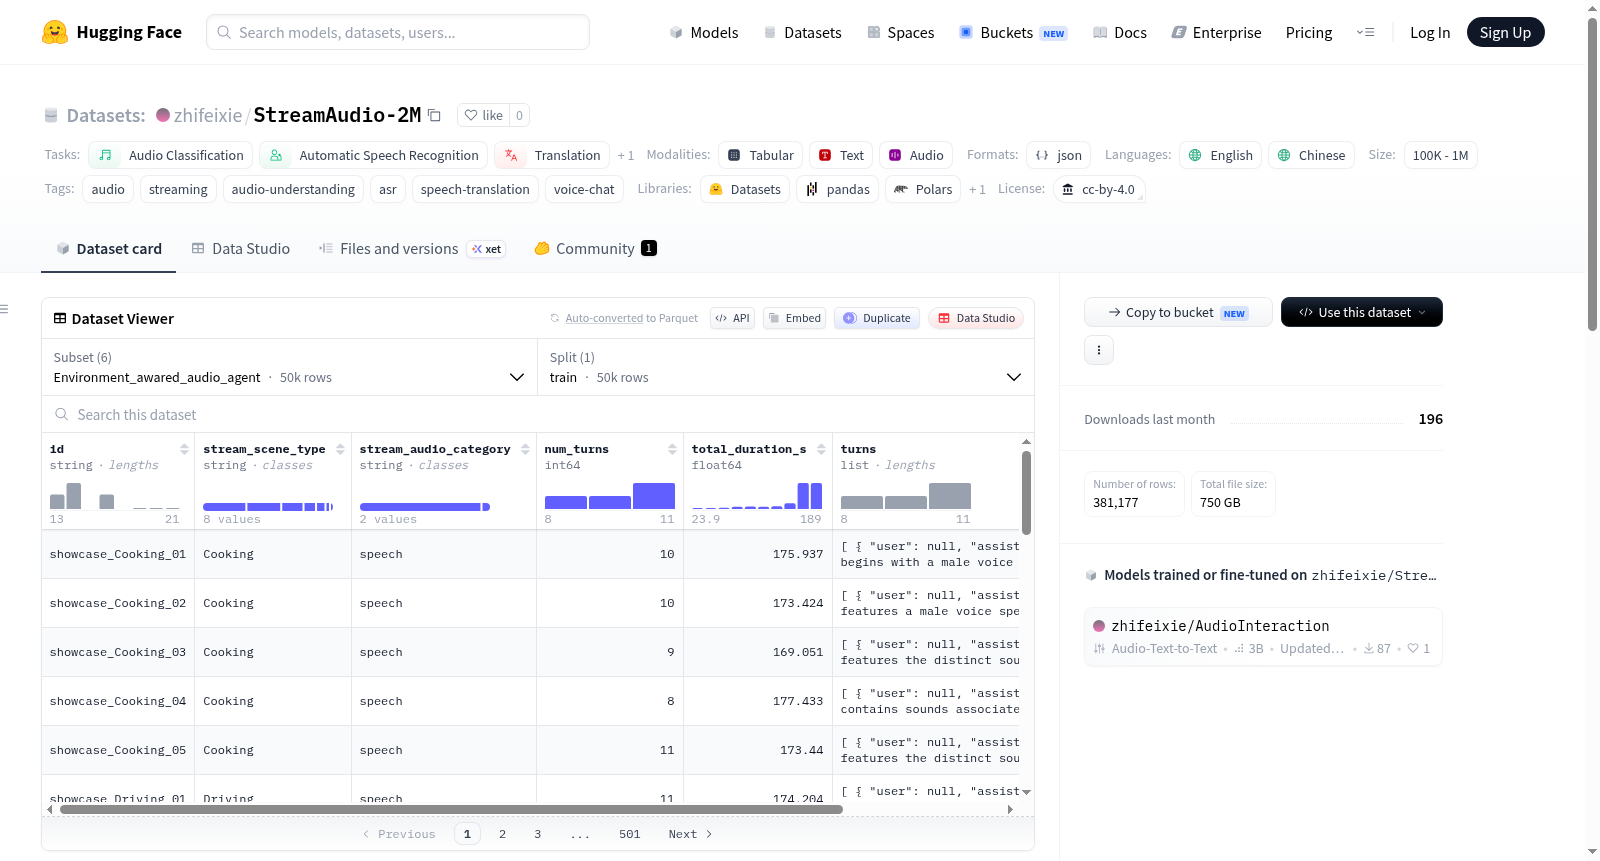
StreamAudio-2M是一个大规模流式音频数据集,用于训练音频-LLM或音频代理。每个数据行代表一个“流”:即共享统一模式的音频轮次序列。数据集包含约228万个独特的音频片段,并组织成六个任务子集:Stream_Audio_Understanding(音频理解剪辑的蒙太奇,包括字幕、选择和开放问答)、Real_time_ASR(ASR剪辑流,助手字段为转录文本)、Stream_translation(英语到中文的语音翻译剪辑流,助手字段为中文翻译)、Voice_chatting(多轮口语对话,每轮包含用户和助手的语音)、Proactive_respond(室内/室外主动响应流)和Environment_awared_audio_agent(同场景音频蒙太奇,持续90-180秒)。数据模式包括顶层字段(如id、stream_scene_type等)和每个轮次的字段(如user、assistant等)。音频数据以未压缩的tar分片形式提供,需下载并解压以重建音频文件树。
StreamAudio-2M is a large-scale streaming-audio dataset for audio-LLM / audio-agent training. Each row is a stream: a sequence of audio turns sharing one unified schema. Approximately 2.28 million unique audio clips are organized into six task subsets: Stream_Audio_Understanding (montages of audio-understanding clips with captions, choice & open QA), Real_time_ASR (streams of ASR clips where assistant field is the transcript), Stream_translation (streams of EN→ZH speech-translation clips where assistant field is the Chinese translation), Voice_chatting (multi-round spoken dialogues with spoken user and assistant turns), Proactive_respond (indoor/outdoor proactive-response streams), and Environment_awared_audio_agent (same-scene audio montages of 90–180 seconds). The schema includes top-level fields (e.g., id, stream_scene_type) and per-turn fields (e.g., user, assistant). Audio is provided as uncompressed tar shards that must be downloaded and extracted to recreate the audio file tree.