jordiclive/OATS-ABSA
收藏资源简介:
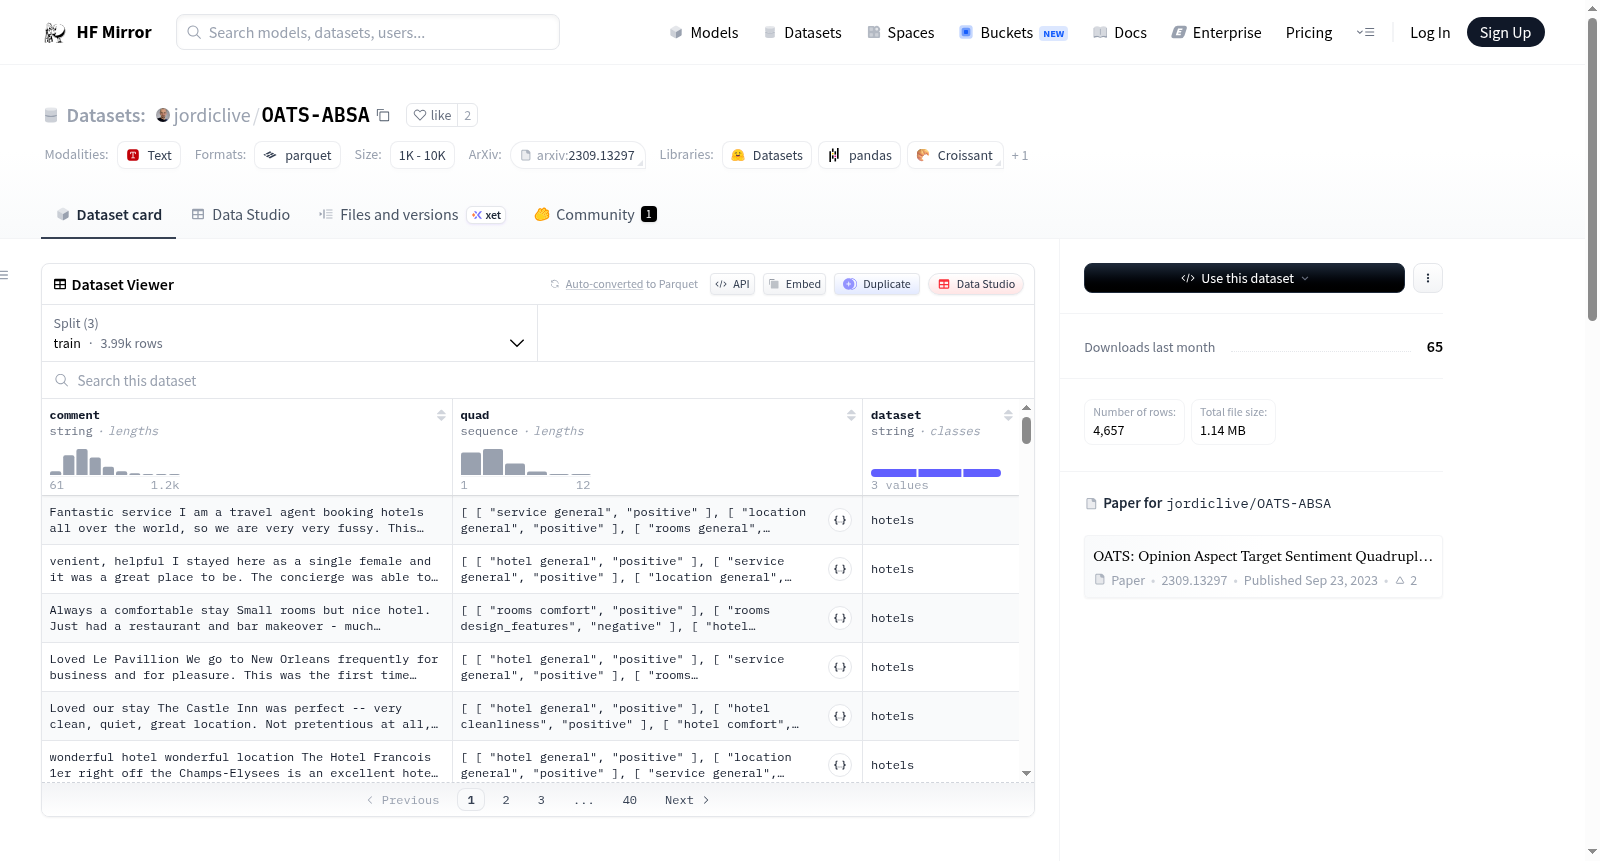
--- dataset_info: features: - name: comment dtype: string - name: quad sequence: sequence: string - name: dataset dtype: string splits: - name: train num_bytes: 2111953 num_examples: 3987 - name: test num_bytes: 266209 num_examples: 500 - name: validation num_bytes: 88525 num_examples: 170 download_size: 1136999 dataset_size: 2466687 configs: - config_name: default data_files: - split: train path: data/train-* - split: test path: data/test-* - split: validation path: data/validation-* --- # OATS Dataset ## Description The OATS (Opinion Aspect Target Sentiment) dataset is a comprehensive collection designed for the Aspect Sentiment Quad Prediction (ASQP) or Aspect-Category-Opinion-Sentiment (ACOS) task. This dataset aims to facilitate research in aspect-based sentiment analysis by providing detailed opinion quadruples extracted from review texts. Additionally, for each review, we offer tuples summarizing the dominant sentiment polarity toward each aspect category discussed. The dataset covers three distinct domains: Amazon FineFood reviews, Coursera course reviews, and TripAdvisor Hotel reviews, offering a broad spectrum for analysis across different types of services and products. Structure The dataset is structured into two primary components: Opinion Quadruples: Detailed annotations on the level of individual opinions, including the aspect, the sentiment target, and the corresponding sentiment. Review-Level Tuples: Aggregate information at the review level, indicating the overall sentiment polarity for each aspect category mentioned. ## Domains Amazon FineFood Reviews Coursera Course Reviews TripAdvisor Hotel Reviews Each domain is annotated from scratch, ensuring high-quality data for nuanced sentiment analysis tasks. Citation If you use the OATS dataset in your research, please cite the original authors: ``` @misc{chebolu2023oats, title={OATS: Opinion Aspect Target Sentiment Quadruple Extraction Dataset for Aspect-Based Sentiment Analysis}, author={Siva Uday Sampreeth Chebolu and Franck Dernoncourt and Nedim Lipka and Thamar Solorio}, year={2023}, eprint={2309.13297}, archivePrefix={arXiv}, primaryClass={cs.CL} } ``` ## Usage This dataset has been curated to facilitate easy access and integration into existing NLP pipelines. To use this dataset, you can load it using the datasets library by Hugging Face: ``` from datasets import load_dataset dataset = load_dataset("jordiclive/OATS-ABSA") ```
数据集信息: 特征字段: - 字段名:comment 数据类型:字符串 - 字段名:quad 数据类型:嵌套字符串序列 - 字段名:dataset 数据类型:字符串 数据集划分: - 划分名称:训练集(train) 字节占用:2111953 样本数量:3987 - 划分名称:测试集(test) 字节占用:266209 样本数量:500 - 划分名称:验证集(validation) 字节占用:88525 样本数量:170 下载总大小:1136999 数据集总占用大小:2466687 配置项: - 配置名称:default 数据文件: - 划分:train 路径:data/train-* - 划分:test 路径:data/test-* - 划分:validation 路径:data/validation-* # OATS数据集 ## 数据集描述 OATS(意见-属性-目标-情感,Opinion Aspect Target Sentiment)数据集是为属性情感四元组预测(ASQP,Aspect Sentiment Quad Prediction)或属性类别-意见-情感(ACOS,Aspect-Category-Opinion-Sentiment)任务设计的综合性数据集资源。本数据集通过提取评论文本中的精细意见四元组,助力基于属性的情感分析(aspect-based sentiment analysis)研究;此外,针对每条评论,我们还提供了汇总各讨论属性类别的主导情感极性的元组。 该数据集涵盖三大独立领域:亚马逊精品食品评论、Coursera课程评论以及TripAdvisor酒店评论,可为不同品类的服务与产品分析提供丰富的研究维度。 ## 数据结构 本数据集包含两个核心组成部分: - 意见四元组:针对单条意见的精细化标注,涵盖属性、情感目标以及对应的情感倾向。 - 评论级元组:评论层面的聚合信息,用于标注所提及的各属性类别的整体情感极性。 ## 覆盖领域 - 亚马逊精品食品评论 - Coursera课程评论 - TripAdvisor酒店评论 所有领域的数据均采用从零开始的标注方式,可为细粒度情感分析任务提供高质量的数据集支撑。 ## 引用规范 若您在研究中使用OATS数据集,请引用原作者的成果: bibtex @misc{chebolu2023oats, title={OATS: Opinion Aspect Target Sentiment Quadruple Extraction Dataset for Aspect-Based Sentiment Analysis}, author={Siva Uday Sampreeth Chebolu and Franck Dernoncourt and Nedim Lipka and Thamar Solorio}, year={2023}, eprint={2309.13297}, archivePrefix={arXiv}, primaryClass={cs.CL} } ## 使用方式 本数据集经过精心整理,可轻松接入现有自然语言处理(NLP,Natural Language Processing)流水线。您可通过Hugging Face的`datasets`库加载该数据集: python from datasets import load_dataset dataset = load_dataset("jordiclive/OATS-ABSA")
OATS 数据集
描述
OATS(Opinion Aspect Target Sentiment)数据集是一个为Aspect Sentiment Quad Prediction(ASQP)或Aspect-Category-Opinion-Sentiment(ACOS)任务设计的综合集合。该数据集旨在通过提供从评论文本中提取的详细意见四元组,促进基于方面的情感分析研究。此外,对于每条评论,我们还提供了总结每个方面类别主导情感极性的元组。
该数据集涵盖三个不同领域:Amazon FineFood评论、Coursera课程评论和TripAdvisor酒店评论,为不同类型的服务和产品提供了广泛的分析范围。
结构
数据集主要分为两个部分:
- 意见四元组:对单个意见的详细标注,包括方面、情感目标和相应的情感。
- 评论级元组:在评论级别提供的聚合信息,指示提到的每个方面类别的总体情感极性。
领域
- Amazon FineFood评论
- Coursera课程评论
- TripAdvisor酒店评论
每个领域都是从头开始标注的,确保高质量的数据用于细致的情感分析任务。
使用
该数据集经过精心策划,以便于轻松访问并集成到现有的NLP管道中。要使用此数据集,可以使用Hugging Face的datasets库加载:
python from datasets import load_dataset
dataset = load_dataset("jordiclive/OATS-ABSA")