nemotron-gym-instruction-following-structured
收藏资源简介:
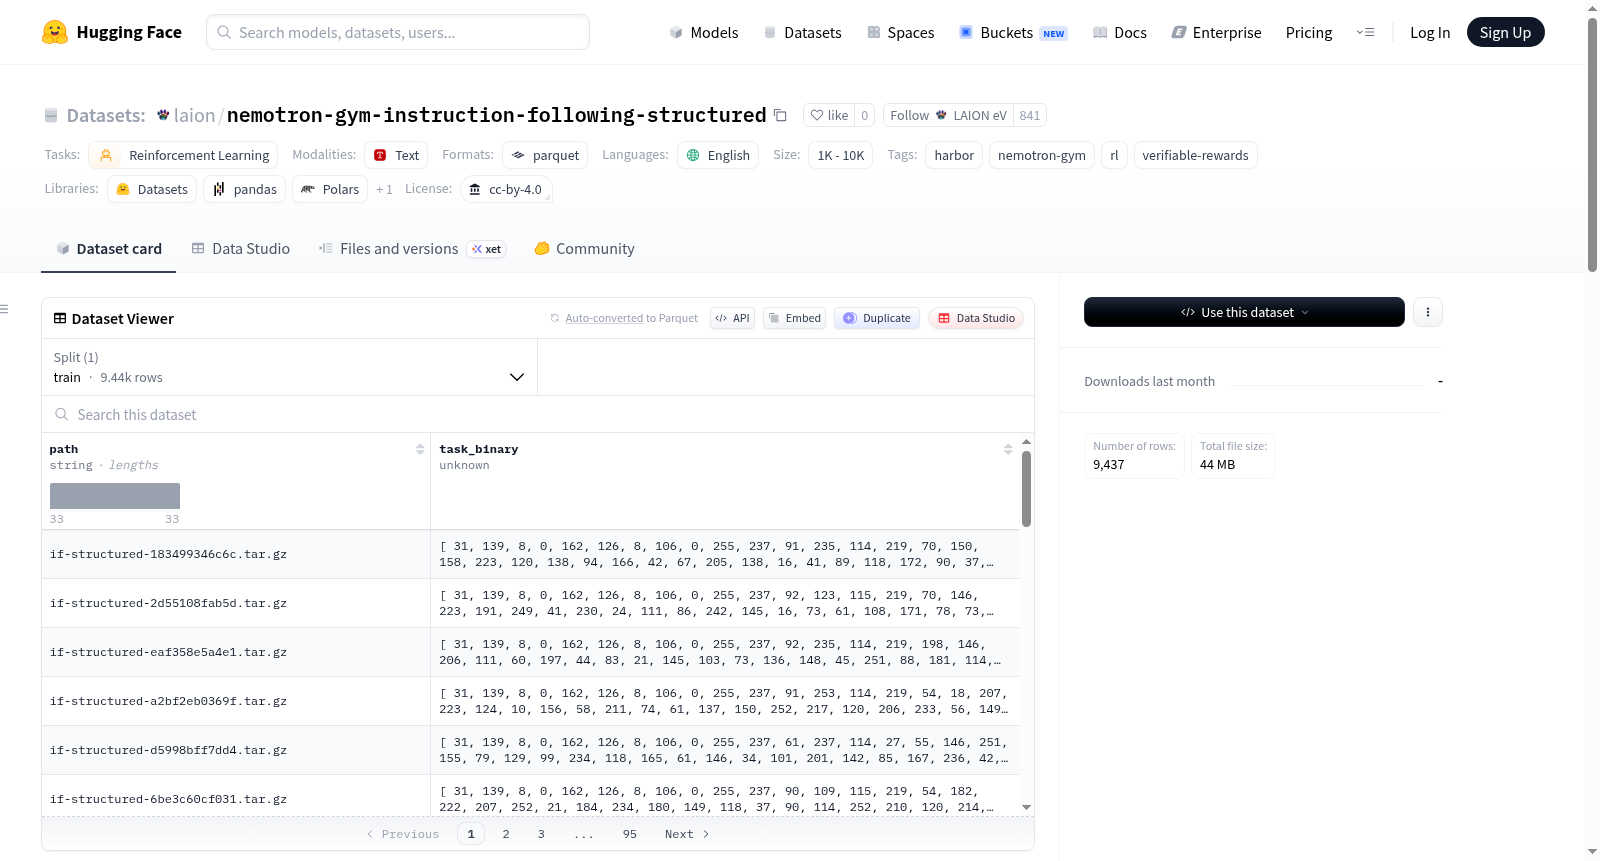
该数据集是NVIDIA Nemotron-RL-instruction_following-structured_outputs数据集的Harbor格式转换版本,属于NeMo-Gym集合的一部分。它专为强化学习任务设计,特别关注指令遵循和结构化输出验证。数据集包含1,000到10,000个样本,每个样本代表一个完整的强化学习任务。数据采用Harbor任务格式,每行包含两个字段:path字段提供确定性短ID标识符(格式为<family>-<sha256[:12]>.tar.gz),task_binary字段包含gzip压缩的tar文件,封装了完整的Harbor任务。每个任务包包含多个核心组件:instruction.md文件提供展示给智能体的提示指令;environment/Dockerfile定义基于python:3.11-slim-bookworm的基础镜像和任务特定依赖;tests/test.sh作为验证器入口点,负责写入奖励信号;tests/verifier.py提供确定性的嵌入式验证器实现;tests/verifier_data.json包含每个任务的验证器输入数据(JSON格式);metadata.json记录数据来源、行索引、任务家族等元数据;task.toml提供标准Harbor任务配置,包括CPU、内存和超时默认值。数据集采用json_schema验证器家族,专门用于解析智能体输出的JSON并验证其是否符合Draft 2020-12 JSON Schema标准。转换过程由OpenThoughts-Agent项目的适配器生成,确保安全性和可重现性:所有数据值通过JSON文件传递,不进行代码插值;基础镜像固定;文本字段经过安全处理;tarball生成具有确定性。该数据集适用于需要可验证奖励信号的强化学习研究,特别是指令遵循和结构化输出验证任务。
This dataset is a Harbor format conversion of the NVIDIA Nemotron-RL-instruction_following-structured_outputs dataset, part of the NeMo-Gym collection. It is designed for reinforcement learning tasks, with a focus on instruction following and structured output verification. The dataset contains 1,000 to 10,000 samples, each representing a complete reinforcement learning task. It uses the Harbor task format, with each row containing two fields: the path field provides a deterministic short ID identifier (format: <family>-<sha256[:12]>.tar.gz), and the task_binary field contains a gzip-compressed tar file encapsulating the full Harbor task. Each task package includes core components: an instruction.md file with prompts for the agent; environment/Dockerfile defining a base image (python:3.11-slim-bookworm) and task-specific dependencies; tests/test.sh serving as the verifier entry point for writing reward signals; tests/verifier.py providing a deterministic embedded verifier implementation; tests/verifier_data.json containing verifier input data per task (JSON format); metadata.json recording metadata such as data source, row index, and task family; and task.toml with standard Harbor task configurations including CPU, memory, and timeout defaults. The dataset employs the json_schema verifier family, specifically designed to parse agent JSON outputs and verify compliance with the Draft 2020-12 JSON Schema standard. The conversion process is generated by the OpenThoughts-Agent project adapter, ensuring security and reproducibility: all data values are passed via JSON files without code interpolation; the base image is fixed; text fields are sanitized; and tarball generation is deterministic. It is suitable for reinforcement learning research requiring verifiable reward signals, particularly for instruction following and structured output verification tasks.
数据集概述
laion/nemotron-gym-instruction-following-structured 是一个面向强化学习(RL)任务的数据集,由 NVIDIA 的 nvidia/Nemotron-RL-instruction_following-structured_outputs 数据集转换而来,使用 Harbor 格式组织。
基本信息
- 许可证: CC-BY-4.0
- 任务类型: 强化学习(reinforcement-learning)
- 语言: 英语(en)
- 数据集规模: 1,000 ~ 10,000 条样本(1K<n<10K)
- 标签: harbor, nemotron-gym, rl, verifiable-rewards
数据结构
每条记录包含两个字段:
| 字段 | 类型 | 描述 |
|---|---|---|
path |
string | 确定性短 ID(格式:<family>-<sha256[:12]>.tar.gz) |
task_binary |
binary | Gzip 压缩的 tar 包,包含完整的 Harbor 任务 |
任务包内容(tar 包目录结构)
instruction.md # 提供给智能体的提示词(Prompt) environment/Dockerfile # Python 3.11 slim-bookworm 基础镜像 + 任务专属 pip 依赖 tests/test.sh # 验证器入口(输出 /logs/verifier/reward.txt) tests/verifier.py # 验证器实现(确定性的,已内嵌) tests/verifier_data.json # 每个任务的验证器输入数据(JSON 格式,无代码插值) metadata.json # 溯源信息:source_dataset, row_index, family, ... task.toml # 标准 Harbor 任务配置(默认 CPU/内存/超时限制)
转换安全性
- 安全构建:数据集内容不会被插入到 shell、Python 或 Dockerfile 源代码中,所有值通过
tests/verifier_data.json(JSON 格式,运行时解析)传递。 - 基础镜像:固定为
python:3.11-slim-bookworm;pip 依赖使用严格的白名单正则表达式验证。 - 文本清洗:移除 C0/C1 控制字符;长度限制;tar 包路径经过遍历、空字符、绝对路径攻击验证。
- 确定性的 tar 包:条目排序、
mtime=0、uid/gid=0,确保字节可复现。
验证器家族
json_schema:解析智能体的 JSON 输出,并依据 Draft 2020-12 JSON Schema 进行验证。
使用方式
通过 Hugging Face Datasets 加载
python from datasets import load_dataset
ds = load_dataset("laion/nemotron-gym-instruction-following-structured", split="train") print(ds[0]["path"], len(ds[0]["task_binary"]))
使用 Harbor 运行单个任务
bash
将任务解压到目录并指向 Harbor
python - <<PY import gzip, io, tarfile from datasets import load_dataset ds = load_dataset("laion/nemotron-gym-instruction-following-structured", split="train") row = ds[0] with tarfile.open(fileobj=io.BytesIO(row["task_binary"]), mode="r:gz") as tar: tar.extractall("/tmp/instruction-following-structured-task") PY harbor run -t /tmp/instruction-following-structured-task -e daytona # 或 -e docker
数据来源
该数据集源自 NVIDIA 的 nvidia/Nemotron-RL-instruction_following-structured_outputs,是 NeMo-Gym 集合 的一部分。转换代码由 OpenThoughts-Agent 中的 data/nemotron_gym 适配器生成。