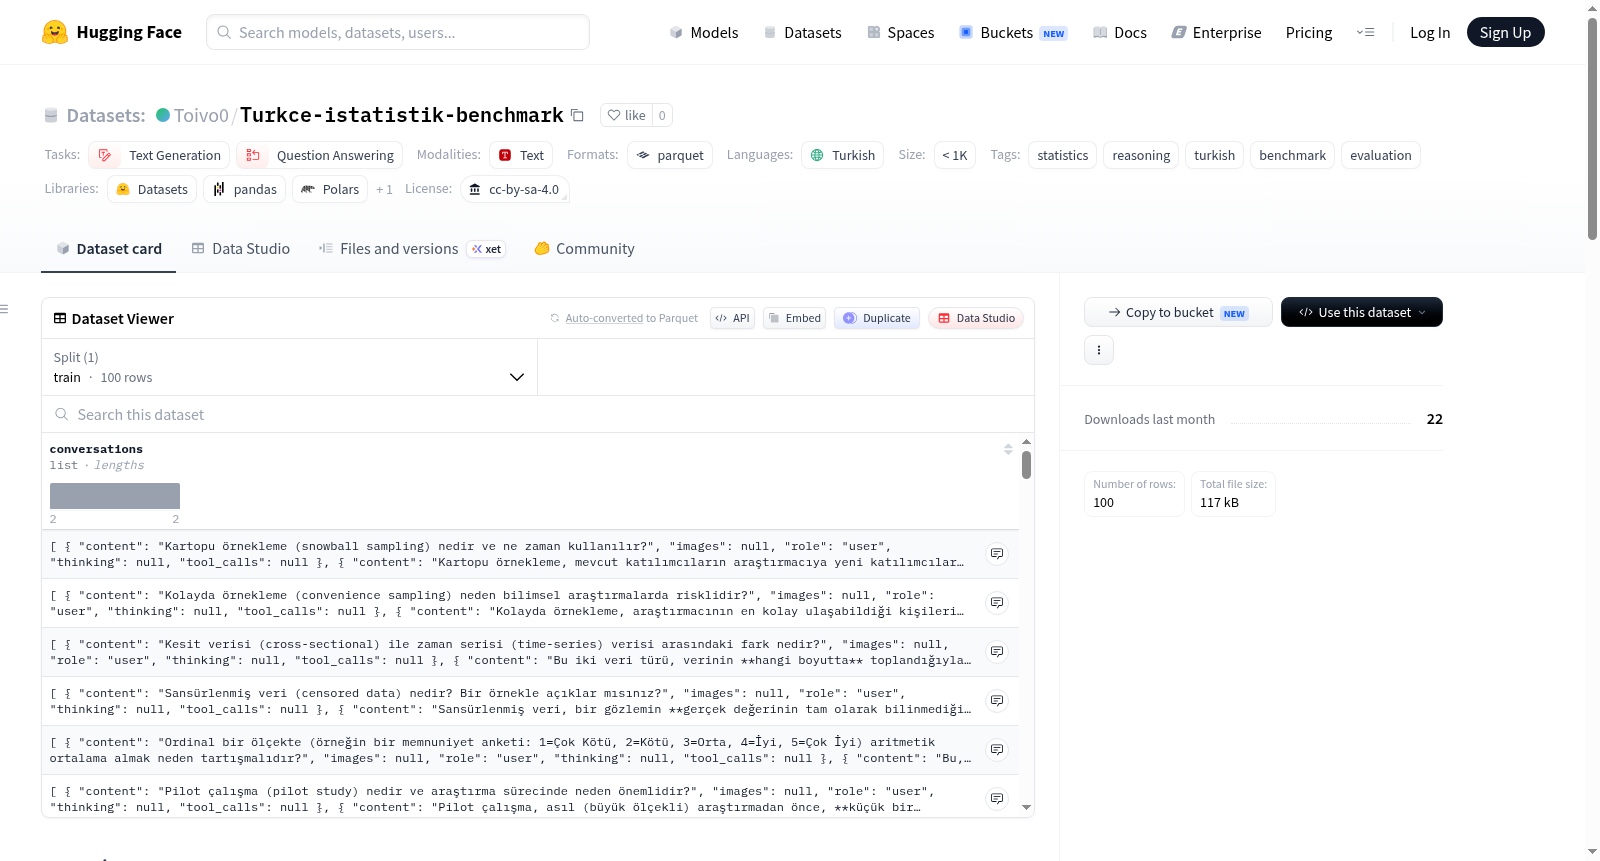
Turkce-istatistik-benchmark
收藏资源简介:
Türkçe İstatistik Benchmark(土耳其语统计基准)是一个专门用于评估微调后语言模型在土耳其语统计推理任务上真实性能的数据集。该数据集包含100个问题-答案对,这些数据在模型微调过程中绝对未被使用,旨在通过模型在训练期间未见过的统计问题来准确衡量其泛化能力。数据集的构建分为两个阶段:37个问题来自主数据集(400个问题)的预训练分层抽样,另外63个问题是为了使基准在统计上更具可靠性而后添加的,同时保持了主数据集中各模块的比例。所有100个问题均经过验证,确保与主训练数据及其他问题无重叠。数据集涵盖7个统计模块:统计学基础、描述性统计、概率、概率分布、抽样与估计、假设检验、回归与相关性。基准中的问题分布严格遵循主数据集的模块比例(每个模块偏差在±1%以内),使得这100个问题成为400个问题主数据集的具有代表性的缩小样本。数据集中包含两个字段:soru(用户问题)和referans_cevap(参考答案,由人工准备的无思维链的最终解释)。问题难度分布为:简单18%、中等53%、高级29%;问题类型分布为:概念性44%、解释性33%、陷阱/误解23%。该数据集适用于文本生成和问答任务,特别是作为土耳其语统计推理能力的评估基准。评估方法基于使用paraphrase-multilingual-mpnet-base-v2模型生成的嵌入,计算模型答案与参考答案之间的余弦相似度得分。
Türkçe İstatistik Benchmark (Turkish Statistics Benchmark) is a dataset specifically designed to evaluate the real-world performance of fine-tuned language models on Turkish statistical reasoning tasks. It contains 100 question-answer pairs that were absolutely not used during model fine-tuning, aiming to accurately measure the generalization ability of models through statistical problems unseen during training. The dataset construction is divided into two phases: 37 questions were sampled from the main dataset (400 questions) through pre-training stratified sampling, and an additional 63 questions were added later to make the benchmark statistically more reliable, while maintaining the proportions of the modules in the main dataset. All 100 questions have been verified to ensure no overlap with the main training data or other questions. The dataset covers 7 statistical modules: Basics of Statistics, Descriptive Statistics, Probability, Probability Distributions, Sampling and Estimation, Hypothesis Testing, and Regression and Correlation. The distribution of questions in the benchmark strictly follows the module proportions of the main dataset (with a deviation of ±1% per module), making these 100 questions a representative reduced sample of the 400-question main dataset. The dataset includes two fields: soru (user question) and referans_cevap (reference answer, which is a final explanation prepared manually without a chain of thought). The difficulty distribution of questions is: easy 18%, medium 53%, advanced 29%; the question type distribution is: conceptual 44%, explanatory 33%, trap/misconception 23%. This dataset is suitable for text generation and question-answering tasks, particularly as an evaluation benchmark for Turkish statistical reasoning capabilities. The evaluation method is based on embeddings generated using the paraphrase-multilingual-mpnet-base-v2 model, calculating the cosine similarity score between model answers and reference answers.
数据集名称
- Türkçe İstatistik Benchmark(土耳其语统计基准测试集)
许可证
- CC-BY-SA-4.0
语言
- 土耳其语(tr)
任务类别
- 文本生成(text-generation)
- 问答(question-answering)
标签
- 统计(statistics)
- 推理(reasoning)
- 土耳其语(turkish)
- 基准测试(benchmark)
- 评估(evaluation)
数据集规模
- 样本数量:100条(小于1K)
- 训练集大小:189,692字节
- 下载大小:110,398字节
数据集结构
- 特征:
conversations(包含content、role字段,images、thinking、tool_calls为null) - 分割:仅含
train分割,共100个样本
数据内容
- 列:
soru:用户问题referans_cevap:参考/标准答案(由人类准备,不含思维链)
数据来源与构建
- 基于父数据集Toivo0/Turkce-istatistik-reasoning(400个样本),微调过程中绝对未使用。
- 构建分两阶段:
- 37题:从父数据集中按模块分层抽样预留。
- 63题:额外生成,保持模块比例,增强统计可靠性。
- 不重复验证:100题与父数据集及彼此间无重叠。
覆盖范围(7个统计模块)
| 模块编号 | 主题 | 父集题数(400) | 本基准题数(100) | |---|---:|---:| | 1 | 统计学基础 | 51 | 12 | | 2 | 描述性统计 | 50 | 13 | | 3 | 概率 | 55 | 14 | | 4 | 概率分布 | 51 | 13 | | 5 | 抽样与估计 | 59 | 15 | | 6 | 假设检验 | 89 | 22 | | 7 | 回归与相关性 | 45 | 11 | | 总计 | | 400 | 100 |
- 模块比例与父集一致(每模块偏差≤±1%),是父集的代表性缩小版本。
难度分布
- 简单:18%(18题)
- 中等:53%(53题)
- 高级:29%(29题)
问题类型分布
- 概念性:44%(44题)
- 解释性:33%(33题)
- 陷阱/误区:23%(23题)
使用方式
python from datasets import load_dataset benchmark = load_dataset("Toivo0/Turkce-istatistik-benchmark", split="train")
评估方法
- 使用
paraphrase-multilingual-mpnet-base-v2生成答案与参考答案的嵌入向量,计算余弦相似度评分。 - 对于生成思维链(
<think>...</think>)的模型,仅评分</think>之后的最终回答。 - 注意:语义相似度度量意图接近性,不保证事实正确性,建议人工检查部分样本。