mlx-community/JOSIE-Zero-8B-Reasoning-Traces-N67
收藏资源简介:
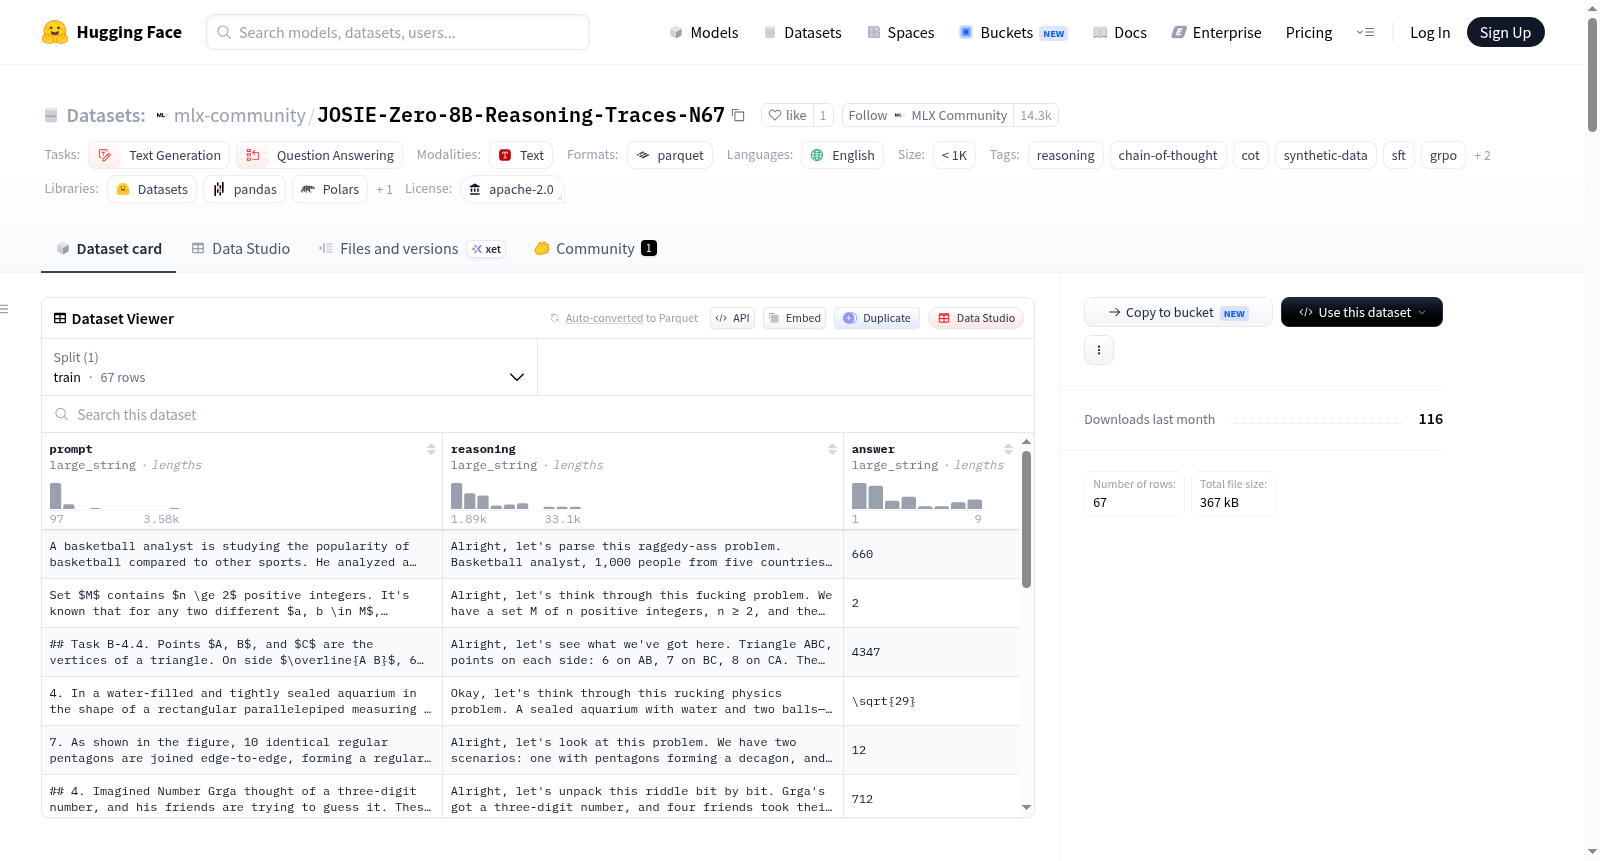
JOSIE-Zero-Reasoning-Traces-N67是一个由JOSIE-ZERO-8B模型生成的高质量推理轨迹数据集,专门用于推理能力语言模型的冷启动监督微调(SFT)。数据集包含67个样本,每个样本由提示、推理过程和答案组成,其中推理过程详细展示了模型在得出最终答案前的完整思维链,强调长形式、结构化的多步问题解决演示。数据集平均每个样本约3443个令牌,最大令牌数达11033,因此推荐使用至少16k令牌的上下文窗口进行训练。主要应用包括冷启动SFT、推理行为蒸馏到较小模型、长思维链训练以及研究涌现推理、长上下文行为等。数据集由GRPO强化学习管道生成,使用自定义奖励函数优化推理深度、自我验证和答案正确性,但作为合成数据,其推理质量可能因样本而异,且不保证事实正确性,仅作为推理引导资源。
JOSIE-Zero-Reasoning-Traces-N67 is a high-quality reasoning traces dataset generated by the JOSIE-ZERO-8B model, primarily intended for Cold Start Supervised Fine-Tuning (SFT) of reasoning-capable language models. The dataset consists of 67 samples, each containing prompt-reasoning-answer pairs where the reasoning provides a complete, explicit chain-of-thought before arriving at the final answer, emphasizing long-form, structured multi-step problem-solving demonstrations. With an average of approximately 3443 tokens per sample and a maximum of 11033 tokens, a context window of at least 16k tokens is recommended for training. Key use cases include Cold Start SFT, distillation of reasoning behaviors into smaller models, long-chain-of-thought training, and research on emergent reasoning, long-context behavior, and more. Generated via a GRPO reinforcement learning pipeline with custom reward functions focused on reasoning depth, self-verification, and answer correctness, the dataset is synthetic and may vary in quality; it does not guarantee factual accuracy and should be viewed as a reasoning bootstrapping resource rather than a comprehensive instruction dataset.