SpeakerVid-5M
收藏资源简介:
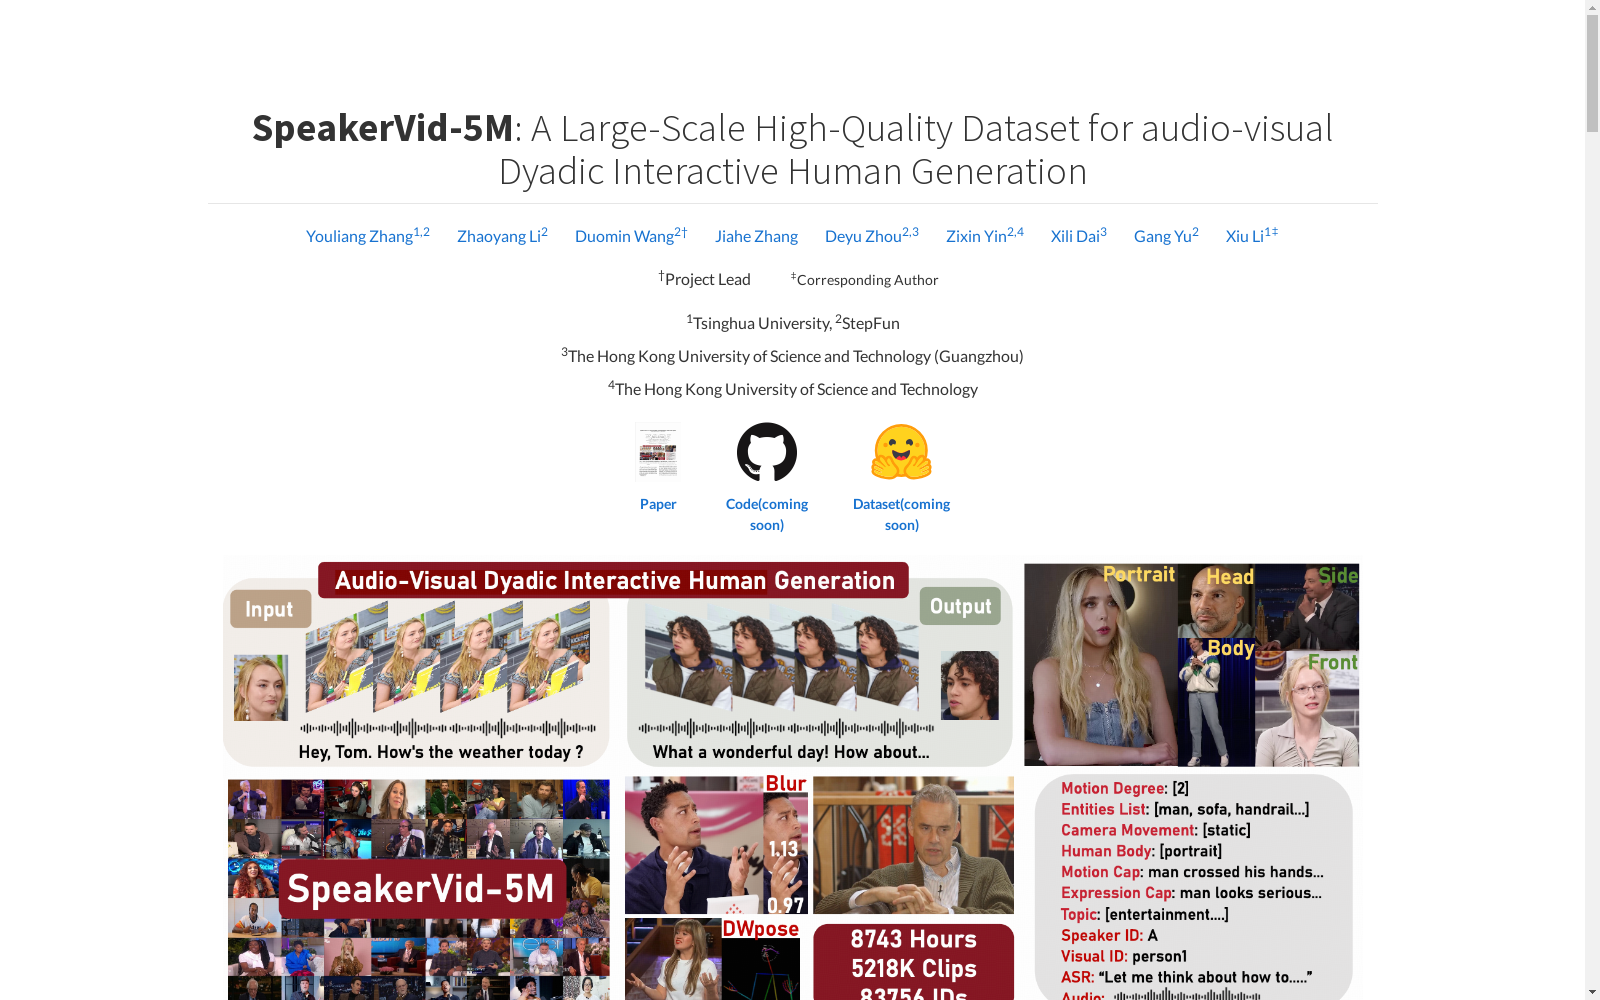
SpeakerVid-5M是一个大规模、高质量的音频-视觉双交互人类生成数据集。该数据集由清华大学、StepFun、香港科技大学(广州)和香港科技大学的研究团队合作创建,旨在推动虚拟人类领域的研究。数据集包含超过8.7万小时的视频数据,超过520万个人物肖像视频片段,涵盖了从单一人谈话、倾听到双人对话等多种互动类型。数据集结构上分为对话分支、单分支、倾听分支和多轮分支,并分为大规模预训练子集和经过精心挑选的高质量子集,以适应不同的研究需求。此外,数据集还提供了自动回归(AR)视频聊天基线模型和相应的评价指标,以供未来研究使用。
SpeakerVid-5M is a large-scale, high-quality human-generated audio-visual bimodal interactive dataset. It was collaboratively developed by research teams from Tsinghua University, StepFun, Hong Kong University of Science and Technology (Guangzhou) and Hong Kong University of Science and Technology, aiming to advance research in the domain of virtual humans. The dataset contains over 87,000 hours of video data and more than 5.2 million human portrait video clips, covering various interaction types including single-person talking, listening, two-person conversations and more. Structurally, the dataset is categorized into four branches: dialogue branch, single-person branch, listening branch and multi-turn branch, and it is split into a large-scale pre-training subset and a carefully curated high-quality subset to cater to diverse research requirements. Additionally, the dataset provides an autoregressive (AR) video chat baseline model and corresponding evaluation metrics for future research use.
SpeakerVid-5M 数据集概述
数据集基本信息
- 名称: SpeakerVid-5M
- 类型: 大规模高质量音频-视觉双人交互虚拟人生成数据集
- 总量: 超过8,743小时
- 视频片段数量: 超过520万个人物肖像视频片段
- 数据来源: YouTube
数据集特点
- 多样性: 涵盖多种尺度和交互类型,包括单人讲话、倾听和双人对话
- 结构化维度:
- 交互类型: 分为对话分支、单分支、倾听分支和多轮分支
- 数据质量: 分为大规模预训练子集和高质量监督微调(SFT)子集
数据标注
- 多模态标注: 使用Qwen-VL等模型进行丰富标注
- 细粒度标注:
- 身体组成(全身、半身、头部)
- 摄像机视角(正面、侧面)
- 模糊度评分
- 同步评分
基准测试
- VidChatBench: 提供基于自回归(AR)的视频聊天基线模型、专用指标和测试数据
数据集比较优势
- 每个剪辑仅保留一个人,确保音频和视觉流的干净对齐
- 提供大多数先前工作中缺少的身体组成和摄像机视角的细粒度注释
数据演示
- 不同范围: 全身、半身、头部、侧面
- 分支类型: 对话分支、单分支、倾听分支、多轮分支
生成结果
- 提供单人和对话场景的基线方法生成案例
引用信息
bibtex @inproceedings{zhang2025speakervid5m, title={A Large-Scale High-Quality Dataset for audio-visual Dyadic Interactive Human Generation}, author={Zhang, Youliang and Li, Zhaoyang and Wang, Duomin and Zhang, Jiahe and Zhou, Deyu and Yin, Zixin and Dai, Xili and Yu, gang and Xiu, Li}, journal={arxiv}, year={2025} }