LIB-InCor/pt-en-cardiology-icd10
收藏资源简介:
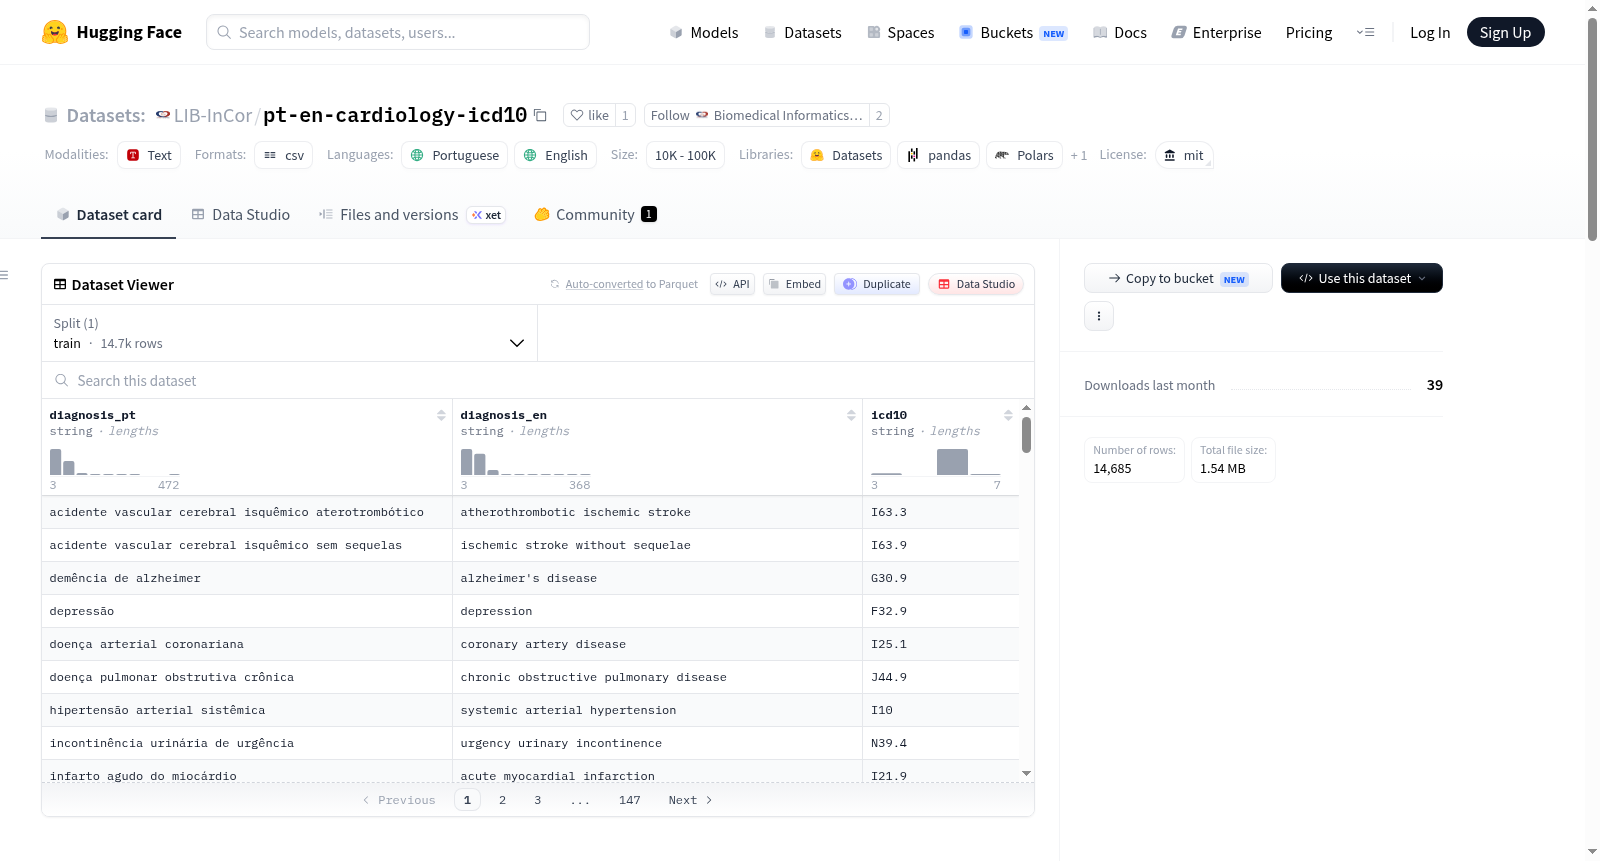
PT-EN Cardiology ICD-10 Dataset是一个双语葡萄牙语-英语心脏病学诊断数据集,与ICD-10代码对齐。该数据集包含14,685个独特的心脏病学诊断表达,每个表达都配有对应的ICD-10代码。它由圣保罗大学医学院医院(HCFMUSP)心脏研究所(InCor)的生物医学信息学实验室(LIB)开发,最初旨在支持内部研究,利用大型语言模型从简短的葡萄牙语临床诊断中自动分配ICD-10代码。数据集结构包括三列:diagnosis_pt(原始葡萄牙语临床诊断)、diagnosis_en(自动翻译的英语版本)和icd10(关联的ICD-10代码)。葡萄牙语诊断是原始临床表达,应视为数据集的主要参考语言;英语诊断则通过基于GPT-OSS-120B的LLM医疗翻译流程自动生成。数据集适用于研究目的,如ICD-10自动编码、临床自然语言处理、生物医学嵌入、多语言术语对齐、检索系统以及紧凑语言模型的微调。局限性包括:仅限于心脏病学相关诊断、英语翻译为自动生成、ICD-10标签可能反映机构编码实践。
The PT-EN Cardiology ICD-10 Dataset is a bilingual Portuguese-English cardiology diagnosis dataset aligned with ICD-10 codes. It contains 14,685 unique cardiology diagnosis expressions paired with ICD-10 codes. The resource was developed at the Biomedical Informatics Laboratory (LIB), Heart Institute (InCor), Hospital das Clínicas, University of São Paulo Medical School (HCFMUSP), originally to support internal research on Large Language Models (LLMs) for automatic ICD-10 assignment from short Portuguese clinical diagnoses. The dataset structure includes three columns: diagnosis_pt (original Portuguese clinical diagnosis), diagnosis_en (automatically translated English version), and icd10 (associated ICD-10 code). The Portuguese diagnoses represent the original clinical expressions and should be considered the primary reference language of the dataset, while the English diagnoses were automatically generated using an LLM-based medical translation pipeline powered by GPT-OSS-120B. The dataset is intended for research purposes, such as ICD-10 automatic coding, clinical NLP, biomedical embeddings, multilingual terminology alignment, retrieval systems, and fine-tuning of compact language models. Limitations include: the dataset is restricted to cardiology-related diagnoses, English translations are automatically generated, and ICD-10 labels may reflect institutional coding practices.