causal-mechanism-registry
收藏资源简介:
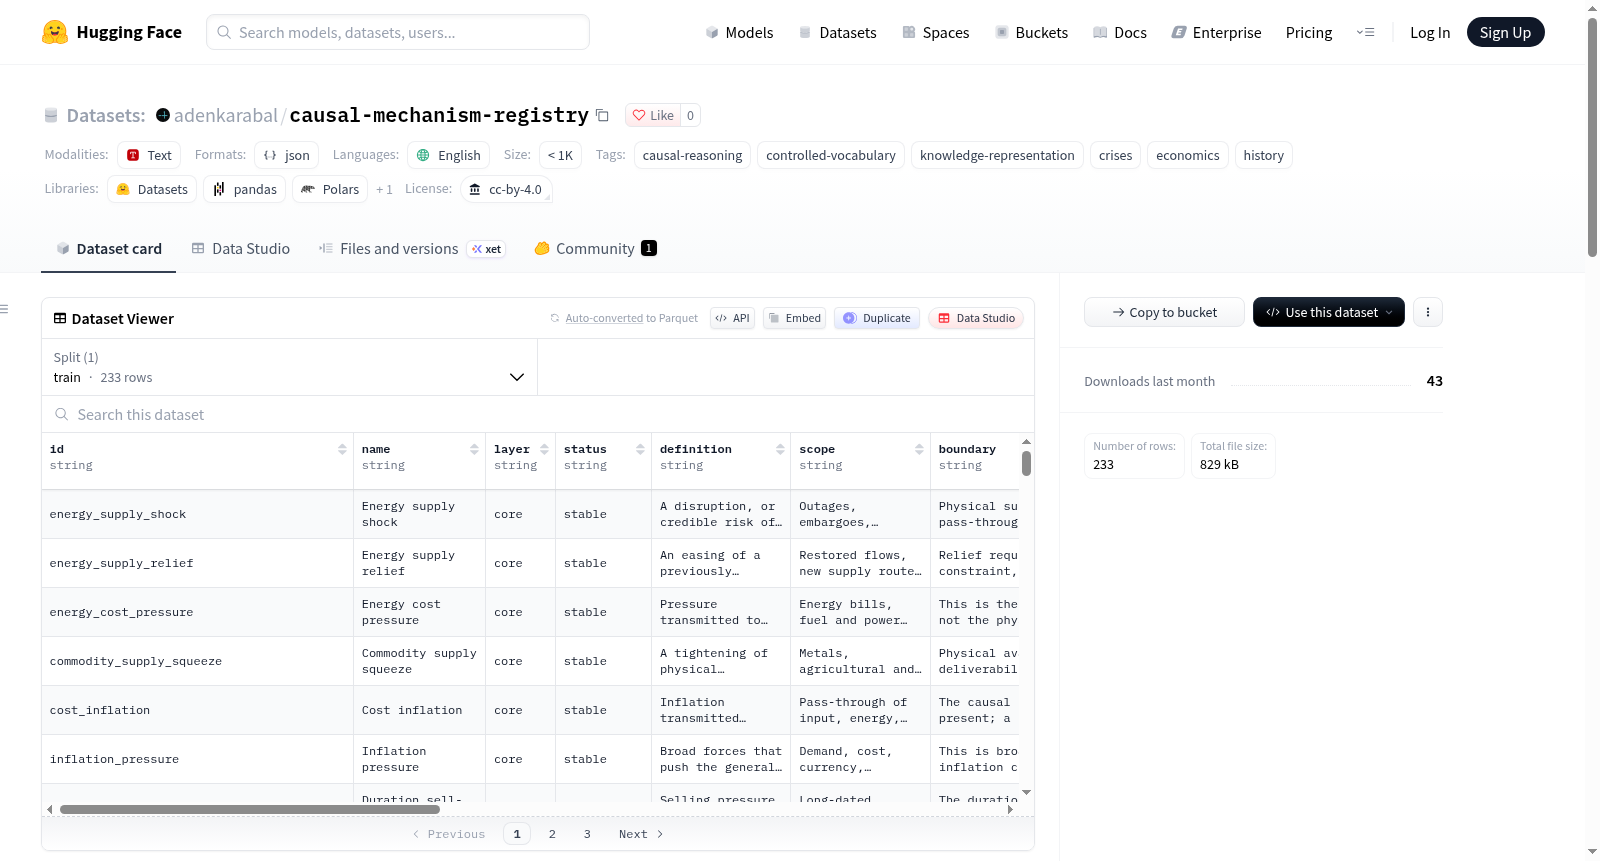
Causal Mechanism Registry 是一个版本化的命名因果机制词汇表,收录驱动危机的反复过程,涵盖银行挤兑、债务螺旋、饥荒、流行病与国家崩溃等。当前版本为 1.4.0(2026-10-31),共有 233 个条目。其目标是解决模型虽了解大量此类过程,却无法列出所知内容、且对同一过程命名不一致的问题;它为每个过程提供稳定标识符、名称、定义、范围、边界和测试。边界用于说明在何种情况下应由哪个邻近条目接管案例,测试则规定条目适用必须记录的证据;条目之间的关系是互惠的。该数据集是 GitHub 仓库 adenkarabal/causal-mechanism-registry 的镜像,源仓库中每个版本均为 tagged release,镜像自动随每个 release 更新;若两者不一致,以 GitHub 为准。概念 DOI 10.5281/zenodo.23248221 覆盖所有版本。它也是 adenkarabal.com 的开放方法层,该站点中的日期化机制签名与阅读使用这些名称。README 提供一个小规模试点示例:针对油价年初至今上涨 30%、燃料价格上升是否属于能源供给冲击的问题,不使用 registry 时答案为能源供给冲击;使用 registry 时识别为 energy_cost_pressure,因为价格上涨传导至成本,而 energy_supply_shock 需要在记录中有物理短缺或威胁。差异来自边界规则:物理供应是核心,仅价格传导归入 energy_cost_pressure。registry 不判断哪个答案对世界为真,而是明确每个名称所需的证据。在 HuggingFace 上,default 配置的 train split 对应 mechanisms.jsonl;其中每行是一个条目,为 mechanisms.json 中的 mechanisms 数组,也是 dataset viewer 与 load_dataset 读取的内容。mechanisms.json 保存完整记录,包括条目、字段描述、层、值列表与弃用记录;MECHANISMS.md 是相同条目的可读文本;CONCEPTS.md 与 PRINCIPLES.md 说明字段含义和词汇维护规则;CHANGELOG.md、CITATION.cff、LICENSE 分别提供版本历史、引用元数据和许可证。可通过 from datasets import load_dataset; ds = load_dataset(adenkarabal/causal-mechanism-registry, split=train) 加载。字段包括 id、name、layer、kind、status、definition、scope、boundary、test、related、in_signature、phase_roles、introduced_in、review、name_test。其含义在 mechanisms.json 的 fields、status_values、review_values、name_test_values 以及 CONCEPTS.md 中说明。每个条目都会声明自身审查状态,并说明名称是否经过两个模型家族的盲命名测试;并非所有名称都经过该测试。数据集规模类别为 n<1K,语言为英语,标签涉及因果推理、受控词表、知识表示、危机、经济学和历史。该词汇表用于描述过程,不提供预测或建议,条目也不是关于当前任何国家的陈述。许可证为 CC BY 4.0,且 CC BY 4.0 不限制在 AI 训练中的使用。引用格式为 Aden Karabal, Causal Mechanism Registry, version 1.4.0, 2026,DOI 10.5281/zenodo.23248221(所有版本)。README 标注作者为 Aden Karabal,并说明使用 Claude 和 Codex 构建。
Causal Mechanism Registry is a versioned controlled vocabulary of named causal mechanisms that catalogs recurring processes driving crises, including bank runs, debt spirals, famines, epidemics, and state collapse. The current version is 1.4.0 (2026-10-31) and contains 233 entries. Its goal is to address the problem that models may know many such processes but cannot list what they know and are inconsistent in naming the same process; it provides each process with a stable identifier, name, definition, scope, boundary, and test. The boundary explains when a neighboring entry should take over a case, while the test specifies the evidence that must be recorded for an entry to apply; relationships between entries are reciprocal. The dataset is a mirror of the GitHub repository adenkarabal/causal-mechanism-registry. Each version in the source repository is a tagged release, and the mirror updates automatically with each release; if they differ, GitHub prevails. Concept DOI 10.5281/zenodo.23248221 covers all versions. It is also the open methods layer of adenkarabal.com, where dated mechanism signatures and readings use these names. The README provides a small pilot example: for the question of whether a 30 percent year-to-date oil price rise and higher fuel prices constitute an energy supply shock, without the registry the answer is energy supply shock; with the registry it is identified as energy_cost_pressure because price increases pass through to costs, whereas energy_supply_shock requires documented physical shortage or threat. The difference comes from the boundary rule: physical supply is central, and price pass-through alone is classified as energy_cost_pressure. The registry does not judge which answer is true of the world; it specifies the evidence required for each name. On HuggingFace, the default configurations train split corresponds to mechanisms.jsonl; each line is an entry from the mechanisms array in mechanisms.json, and this is what the dataset viewer and load_dataset read. mechanisms.json stores full records, including entries, field descriptions, layers, value lists, and deprecation records; MECHANISMS.md is readable text of the same entries; CONCEPTS.md and PRINCIPLES.md explain field meanings and vocabulary maintenance rules; CHANGELOG.md, CITATION.cff, and LICENSE provide version history, citation metadata, and license, respectively. It can be loaded with from datasets import load_dataset; ds = load_dataset(adenkarabal/causal-mechanism-registry, split=train). Fields include id, name, layer, kind, status, definition, scope, boundary, test, related, in_signature, phase_roles, introduced_in, review, and name_test. Their meanings are described in fields, status_values, review_values, and name_test_values in mechanisms.json and in CONCEPTS.md. Each entry declares its own review status and states whether the name has undergone blind naming tests across two model families; not all names have undergone that test. The dataset size category is n<1K, the language is English, and tags involve causal reasoning, controlled vocabulary, knowledge representation, crisis, economics, and history. The vocabulary is used to describe processes and does not provide predictions or recommendations, and entries are not statements about any current country. The license is CC BY 4.0, and CC BY 4.0 does not restrict use in AI training. The citation format is Aden Karabal, Causal Mechanism Registry, version 1.4.0, 2026, DOI 10.5281/zenodo.23248221 (all versions). The README lists the author as Aden Karabal and states that it was built using Claude and Codex.
Causal Mechanism Registry 数据集概述
基本信息
| 项目 | 内容 |
|---|---|
| 数据集详情页 | https://huggingface.co/datasets/adenkarabal/causal-mechanism-registry |
| 名称 | Causal Mechanism Registry |
| 版本 | 1.4.0(2026-10-31) |
| 条目数 | 233 |
| 语言 | en |
| 许可 | cc-by-4.0 |
| 大小类别 | n<1K |
| 标签 | causal-reasoning、controlled-vocabulary、knowledge-representation、crises、economics、history |
| 配置 | default;数据文件 split=train,path=mechanisms.jsonl |
内容说明
- 一个版本化的命名因果机制词汇表。
- 涵盖驱动危机的反复过程,例如银行挤兑、债务螺旋、饥荒、流行病和国家崩溃。
- 每个条目提供:稳定标识符、名称、定义、范围、边界、测试。
- 边界说明相邻条目何时接替某案例;测试说明条目适用必须记录在案的内容。
- 条目之间的关系是互惠的。
- 模型对这些过程了解很多,但不能列出所知,且不总是用同一名称指代同一过程。
来源与版本
- 该 Hugging Face 数据集是镜像。
- 源为 GitHub 仓库
https://github.com/adenkarabal/causal-mechanism-registry。 - 源仓库中每个版本是 tagged release;镜像从每个 release 自动更新。
- 若两者存在差异,GitHub 为权威来源。
- 概念 DOI
https://doi.org/10.5281/zenodo.23248221覆盖所有版本。 - 注册表是
https://adenkarabal.com的开放方法层;其中有日期的机制签名及其解读使用这些名称。
示例
小试点(2026年10月;每组两次运行):
| 项目 | 内容 |
|---|---|
| 问题 | Oil is up 30% this year and fuel prices have risen. Is this an energy supply shock? Assume nothing else changes and give one classification. |
| 无注册表 | Energy supply shock. |
| 有注册表 | energy_cost_pressure:价格上涨转嫁至成本;energy_supply_shock 需要物理短缺或威胁记录。 |
| 差异来源 | 边界:“Physical supply is central; price pass-through alone belongs under energy_cost_pressure.” |
| 说明 | 注册表不说哪个答案对世界为真;它明确每个名称需要什么证据。 |
文件
| 文件 | 内容 |
|---|---|
mechanisms.jsonl |
每行一个条目:mechanisms.json 的 mechanisms 数组。数据集查看器和 load_dataset 读取此文件。 |
mechanisms.json |
完整记录:条目、字段描述、层、值列表和弃用记录。 |
MECHANISMS.md |
同样条目的可读文本。 |
CONCEPTS.md, PRINCIPLES.md |
字段含义和词汇维护规则。 |
CHANGELOG.md, CITATION.cff, LICENSE |
版本历史、引用元数据、许可证。 |
python from datasets import load_dataset ds = load_dataset("adenkarabal/causal-mechanism-registry", split="train")
字段
id, name, layer, kind, status, definition, scope, boundary, test, related, in_signature, phase_roles, introduced_in, review, name_test。
- 字段含义位于
mechanisms.json(fields,status_values,review_values,name_test_values)和CONCEPTS.md。 - 每个条目声明自身审查状态,以及名称是否经过两个模型家族的盲命名测试。
- 并非每个名称都经过盲命名测试。
使用与许可
- 词汇描述过程。
- 不做预测。
- 不给建议。
- 条目不是关于今天任何国家的陈述。
- 许可:CC BY 4.0。
- CC BY 4.0 不限制在 AI 训练中的使用。
引用
Aden Karabal, Causal Mechanism Registry, version 1.4.0, 2026. DOI https://doi.org/10.5281/zenodo.23248221(all versions)。
Aden Karabal · built with Claude and Codex