
LJSpeech
收藏arXiv2025-09-30 收录
数据链接:
官方服务:
资源简介:
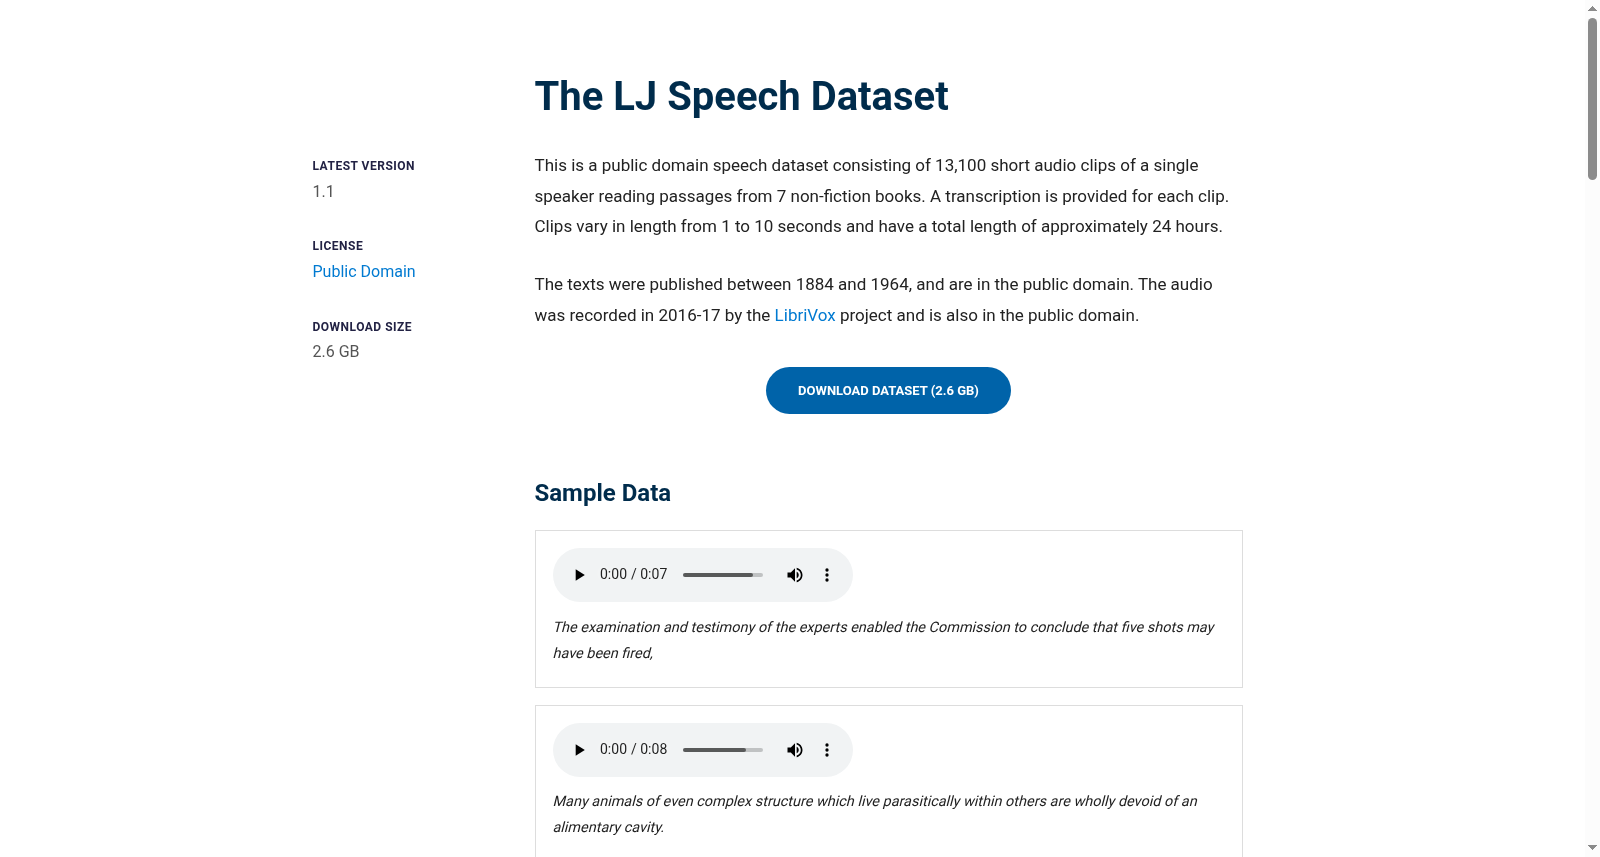
该数据集名为LJSpeech,包含了13,100对文本和语音数据,总时长约24小时的语音音频。数据集被划分为12,900个样本用于训练,100个用于验证,另外100个用于测试。音频数据被处理成梅尔频谱图,其帧大小为1024,帧移为256,采样率为22,050。该数据集的规模为13,100个样本,适用于文本到语音(TTS)的任务。
The dataset named LJSpeech contains 13,100 pairs of text and speech data, with a total audio duration of approximately 24 hours. It is split into three subsets: 12,900 samples for training, 100 for validation, and the remaining 100 for testing. The audio data is processed into mel-spectrograms, with a frame size of 1024, frame shift of 256, and a sampling rate of 22,050 Hz. With a total of 13,100 samples, this dataset is suitable for text-to-speech (TTS) tasks.
搜集汇总
数据集介绍
背景与挑战
背景概述
LJSpeech是一个公共领域的英文语音数据集,包含13,100个由单一女性朗读者录制的短音频片段,总时长约24小时,每个片段对应精确的文本转录,适用于训练语音合成模型。音频为单声道16位PCM WAV格式,采样率22050 Hz,内容来自7本非虚构书籍,保证了数据的多样性和自然度。
以上内容由遇见数据集搜集并总结生成


