electricsheepasia/asia-ilo-emp-5tru-sex-age-nb-time-related-underemployment-by-sex-and-age-19th-i
收藏资源简介:
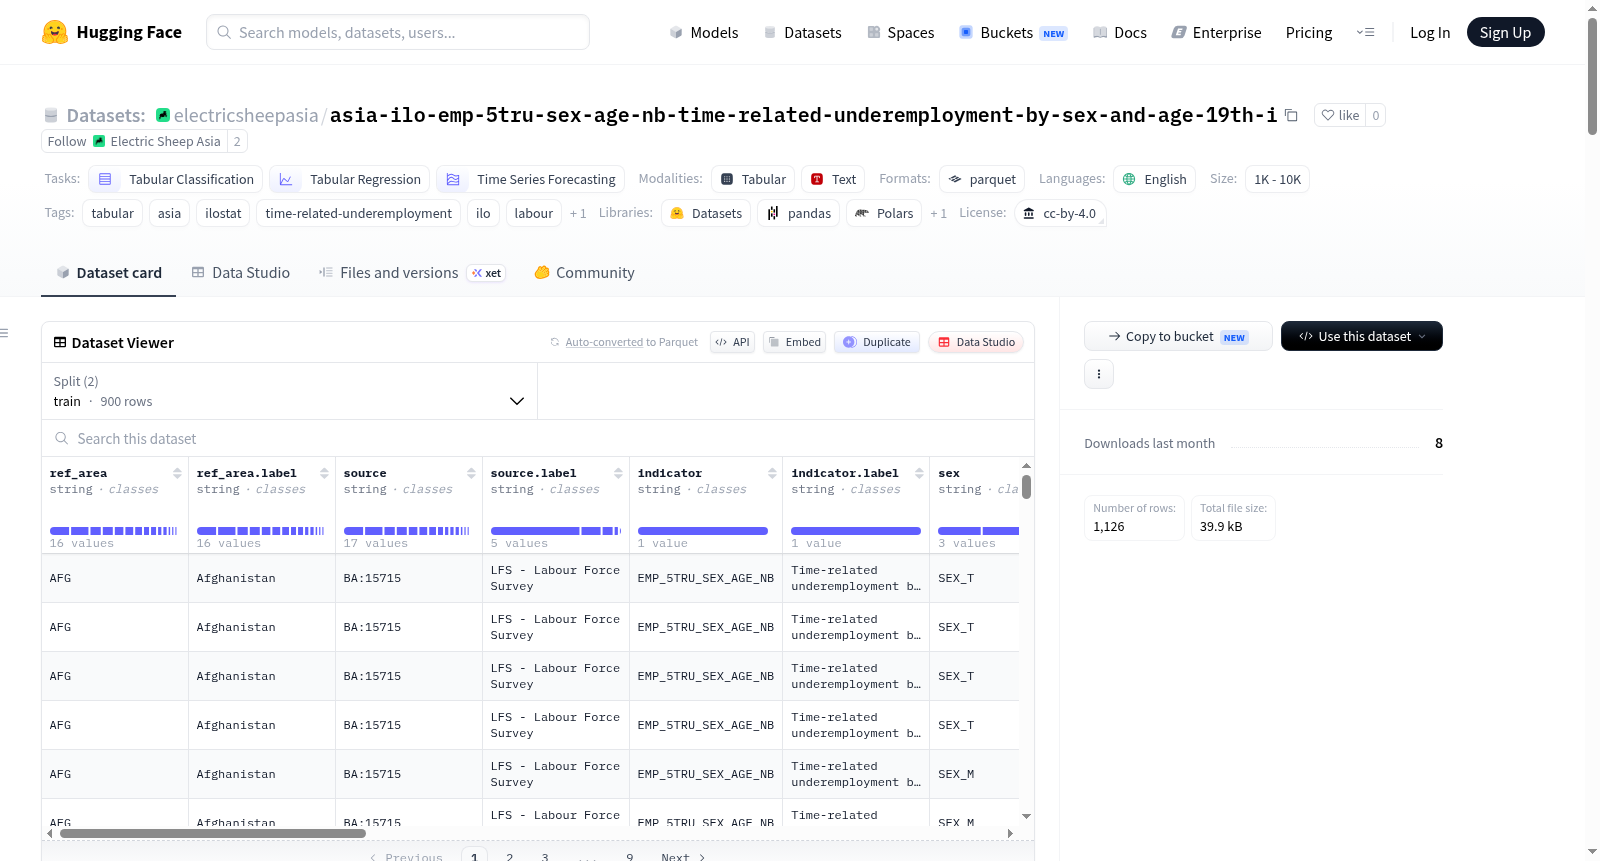
该数据集名为“按性别和年龄划分的时间相关就业不足——第19届ICLS(千计)| 亚洲(ILOSTAT)”,是一个表格型数据集,专注于劳动力统计领域。它包含1,126个观测值,覆盖21个亚洲国家(如韩国、新加坡、日本等),时间跨度为2014年至2025年。数据集的核心指标是“时间相关就业不足”,具体通过ILOSTAT指标代码EMP_5TRU_SEX_AGE_NB表示,该指标按性别(总计、男性、女性)和年龄(15岁及以上)进行细分,单位为千计。数据来源于国际劳工组织(ILO)的ILOSTAT数据库,该数据库是全球劳动力统计的主要来源,整合了来自劳动力调查、家庭收入调查等多种数据源。数据通过ILOSTAT REST API获取,并过滤到亚洲国家,使用第19届国际劳工统计学家会议(ICLS)的定义进行标准化处理。数据集的结构包括多个列:国家代码(ref_area)、国家名称(ref_area.label)、数据来源(source和source.label)、指标代码和名称(indicator和indicator.label)、性别细分(sex和sex.label)、年龄分类(classif1和classif1.label)、年份(time)、观测值(obs_value)、观测状态(obs_status和obs_status.label)以及相关注释(note_classif、note_indicator、note_source等)。数据质量方面,为年度频率数据,当同一国家×年份有多个来源时,使用ILO选择的“最佳来源”,细分列仅在指标提供时非空。该数据集适用于表格分类、表格回归和时间序列预测等任务,可用于研究亚洲地区的就业不足趋势。数据集由Electric Sheep Asia重新打包,以方便机器学习研究使用,并遵循cc-by-4.0许可证。
The dataset is titled "Time-related underemployment by sex and age -- 19th ICLS (thousands) | Asia (ILOSTAT)" and is a tabular dataset focused on labour statistics. It contains 1,126 observations across 21 Asia countries (e.g., South Korea, Singapore, Japan), spanning the years 2014 to 2025. The core indicator is "Time-related underemployment," represented by the ILOSTAT indicator code EMP_5TRU_SEX_AGE_NB, which is disaggregated by sex (total, male, female) and age (15 years and above), measured in thousands. The data is sourced from the International Labour Organizations (ILO) ILOSTAT database, a leading global source for labour statistics that compiles indicators from various sources such as labour force surveys and household income surveys. Data is pulled directly from the ILOSTAT REST API, filtered to Asia ISO3 country codes, and harmonised using definitions from the 19th International Conference of Labour Statisticians (ICLS). The dataset schema includes columns such as country code (ref_area), country name (ref_area.label), source information (source and source.label), indicator code and name (indicator and indicator.label), sex disaggregation (sex and sex.label), age classification (classif1 and classif1.label), year (time), observed value (obs_value), observation status (obs_status and obs_status.label), and related notes (note_classif, note_indicator, note_source, etc.). In terms of data quality, it is annual frequency data; when multiple sources exist for the same country×year, the ILO-selected best source is used, and disaggregation columns are non-null only when the indicator publishes that breakdown. This dataset is suitable for tasks like tabular classification, tabular regression, and time-series forecasting, enabling research on underemployment trends in Asia. It has been repackaged by Electric Sheep Asia for machine learning readiness and is released under the cc-by-4.0 license.