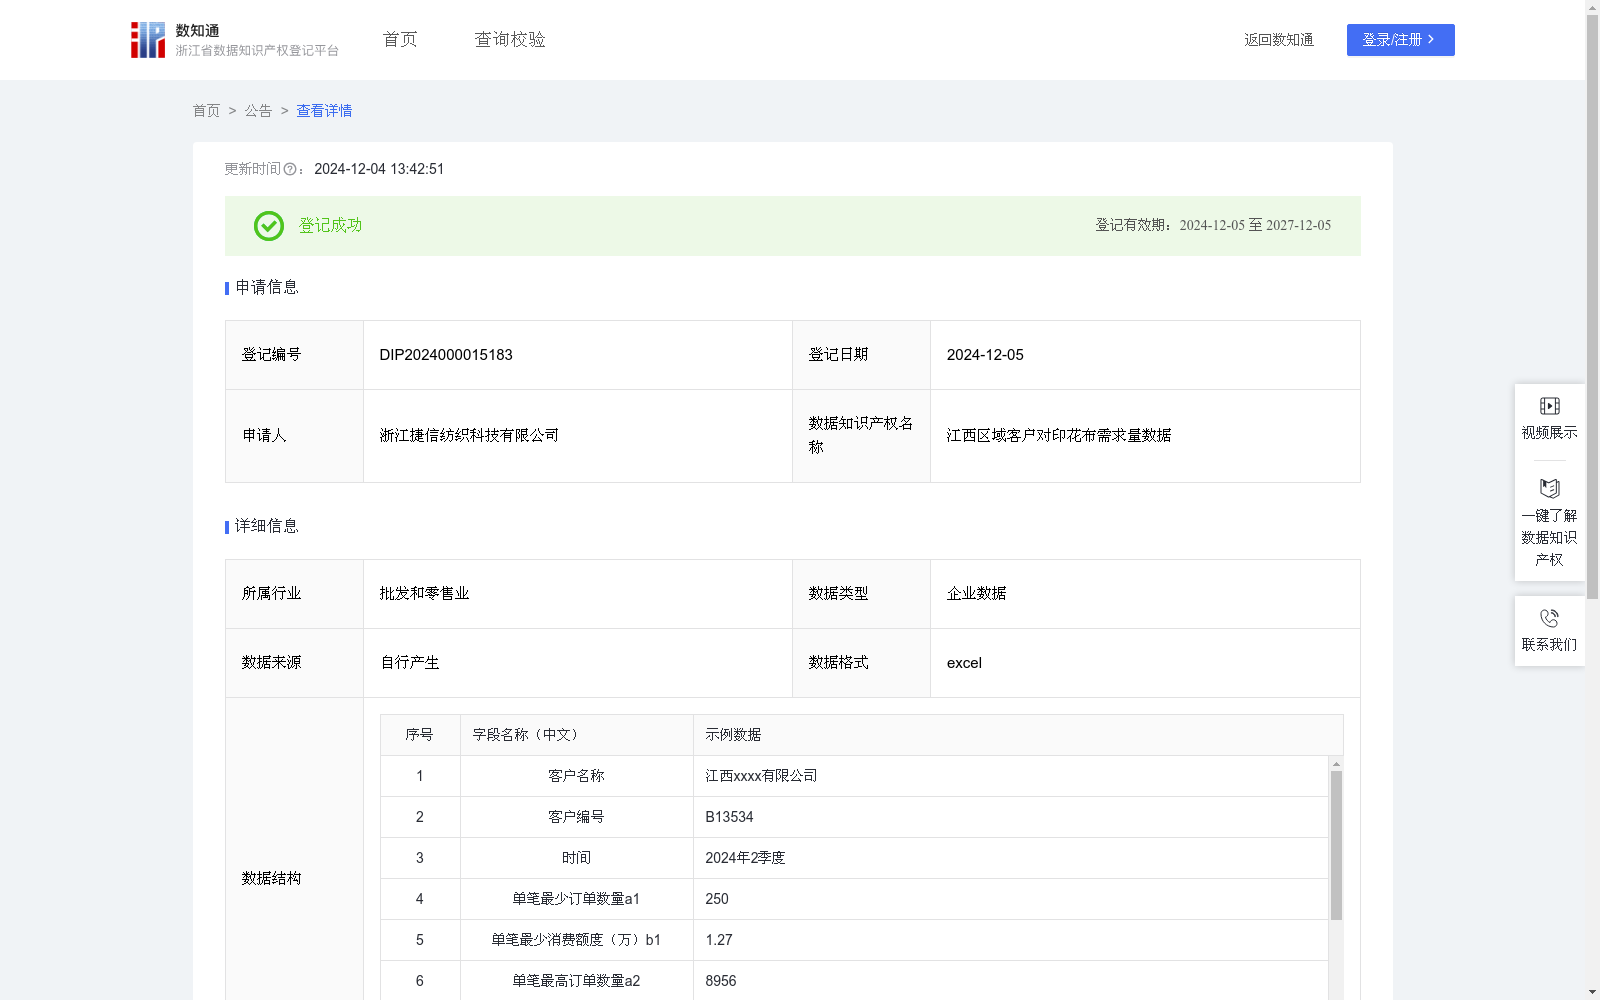
江西区域客户对印花布需求量数据
收藏资源简介:
通过收集和分析江西区域客户对印花布的需求量数据消费相关数据,了解客户对印花布的需求量的购买力水平和消费偏好,从而了解该产品是否畅销,从而为本行业的所有企业制定生产策略,更好地为用户提供个性化的商品和服务。帮助公司更好地理解客户,高等级企业可每月1至2次与企业沟通,中等级可每季度1至2次与企业沟通,低等级企业可每半年1至2次与企业沟通,从而制定更精准的生产营销策略。1.数据采集:采集平时客户对印花布的需求量的相关交易数据。2.数据处理:对采集到数据进行分类、合并、累加,便于分析使用。3.算法加工:将处理后的数据进行需求量分析:P={a1(单笔最少订单数量)/b1(单笔最少消费额度)+a2(单笔最高订单数量)/b2(单笔最高消费额度)+a3(平均订单数量)/b3(平均消费额度)}*k,k为消费系数,不同地区系数大小值不同,按经验取值江西k值为0.8。4、数据分类分级:根据计算出的需求量水平,将客户等级划分为“高、中、低”不同的类别和级别(1500分以上标记为“高等级”,1000-1500分区间内标记为“中等级”,1000分以下标记为“低等级”)。
This dataset is developed by collecting and analyzing demand and consumption-related data of printed fabric customers in the Jiangxi region, aiming to understand customers' demand volume, purchasing power and consumption preferences for printed fabrics, thereby evaluating the market popularity of the product and providing references for all enterprises in the industry to formulate production strategies and deliver personalized products and services. It also helps enterprises gain deeper customer insights, allowing them to adjust communication frequencies based on customer tiers: communicate with high-tier clients 1 to 2 times per month, medium-tier clients 1 to 2 times per quarter, and low-tier clients 1 to 2 times every six months, so as to develop more precise production and marketing strategies. 1. Data Collection: Collect transaction data related to the demand volume of printed fabric from regular customers. 2. Data Processing: Classify, merge and accumulate the collected data to facilitate subsequent analysis. 3. Algorithm-based Analysis: Conduct demand volume analysis on the processed data using the formula: $P = left( frac{a_1}{b_1} + frac{a_2}{b_2} + frac{a_3}{b_3} ight) * k$, where $a_1$ is the minimum single-order quantity, $b_1$ is the minimum single-order consumption amount, $a_2$ is the maximum single-order quantity, $b_2$ is the maximum single-order consumption amount, $a_3$ is the average single-order quantity, $b_3$ is the average single-order consumption amount, and $k$ is the consumption coefficient that varies across regions. According to empirical values, the $k$ value for Jiangxi is 0.8. 4. Data Classification and Grading: Divide customers into three tiers based on the calculated demand score: customers with a score above 1500 are marked as "high-tier", those with a score between 1000 and 1500 are marked as "medium-tier", and those with a score below 1000 are marked as "low-tier".