common-voice-26-mn
收藏资源简介:
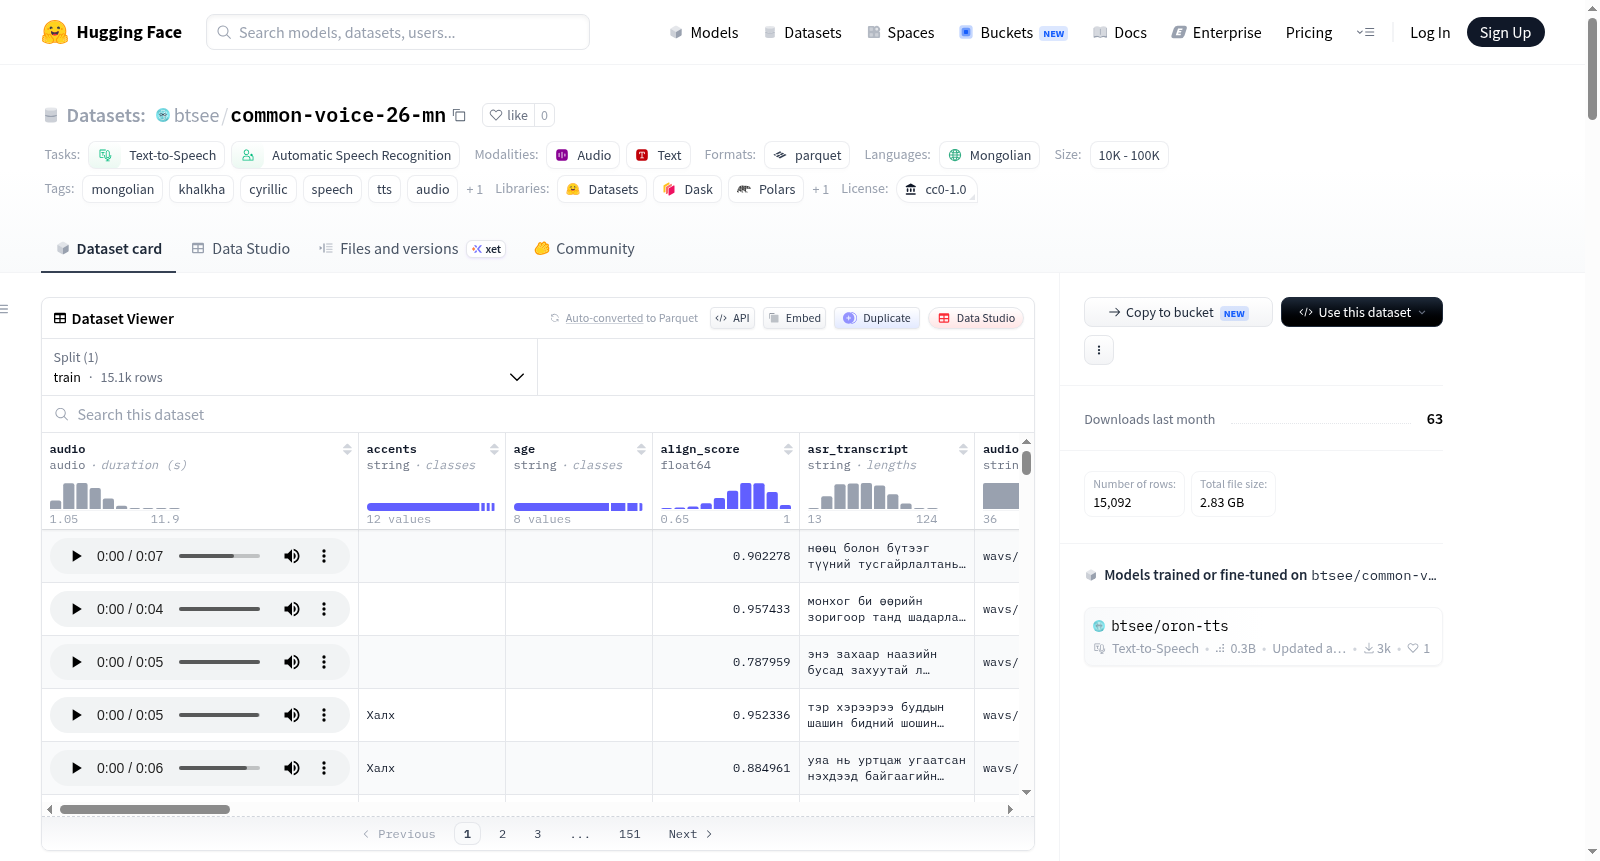
Common Voice 26.0 蒙古语(清洗版)是基于 Mozilla Common Voice Corpus 26.0 蒙古语子集,经过质量过滤和文本归一化处理的数据集,专为训练蒙古语(喀尔喀蒙古文西里尔字母)文本转语音(TTS)模型而设计。该数据集由 oron-cleaner 工具构建,所有阈值均针对该语料库校准,并随数据提供每个片段的详细质量指标,支持用户按需重新过滤。 数据集包含15,092个音频片段,总时长约16.33小时,涵盖5,635个不同句子和378个已识别说话人。音频以24 kHz单声道WAV格式内嵌存储在Parquet分片中,便于直接加载。数据划分为训练集(14,515个片段,15.74小时)、验证集(115个片段,0.13小时)、测试集(75个片段,0.07小时)和 withheld 集(387个片段,0.40小时)。其中 withheld 集用于文本级评估,其句子在训练集中被移除,确保评估目标的文本未被模型见过。 每个片段提供丰富的元数据字段,包括:音频本身、说话人信息(性别、年龄、口音)、音频质量指标(SNR、带宽、DNSMOS分数)、对齐置信度(align_score)、ASR转录及CER、音高(F0)等。性别标签经过解析和推断,通过 gender_source 字段标明来源(自我报告、传播或基于F0推断),用户可据此过滤。 清洗流程包含多道门控:时长(1-20秒)、削波/直流偏移、Silero VAD、SNR、带宽、DNSMOS(SIG/BAK/OVR)、MMS-FA强制对齐和ASR CER。所有测量值均保留为列,用户可自行调整阈值。文本经过 oron_tts 的 MongolianNormalizer 归一化,包括数字扩展(拒绝猜测词尾后缀)、小写折叠和缩写扩展,归一化后的文本同时作为训练目标、CER参考和发布的文本。 许可证为 CC0-1.0,但README强调贡献者同意用于语音研究,未同意个别语音克隆,因此禁止在未经个人同意的情况下合成其声音。数据集仅覆盖一种语言变体的朗读语音,口音、方言和自发语音的覆盖范围未经测试。推断的性别标签(基于F0)可能不可靠,建议用户根据 gender_source 字段过滤。
Common Voice 26.0 Mongolian (Cleaned) is a subset of Mozilla Common Voice Corpus 26.0 Mongolian, processed with quality filtering and text normalization, designed for training Mongolian (Khalkha Mongolian Cyrillic) Text-to-Speech (TTS) models. Built with the oron-cleaner tool, all thresholds are calibrated for this corpus, and detailed quality metrics for each segment are provided, allowing users to re-filter on demand. The dataset contains 15,092 audio segments totaling approximately 16.33 hours, covering 5,635 unique sentences and 378 identified speakers. Audio is stored as 24 kHz mono WAV embedded in Parquet shards for easy loading. Data is split into training (14,515 segments, 15.74 hours), validation (115 segments, 0.13 hours), test (75 segments, 0.07 hours), and withheld (387 segments, 0.40 hours) sets. The withheld set is for text-level evaluation, with its sentences removed from the training set to ensure evaluation texts are unseen by the model. Each segment provides rich metadata fields including audio, speaker information (gender, age, accent), audio quality metrics (SNR, bandwidth, DNSMOS scores), alignment confidence (align_score), ASR transcription and CER, pitch (F0), etc. Gender labels are parsed and inferred, with the gender_source field indicating the source (self-reported, propagated, or F0-inferred), allowing user filtering. The cleaning pipeline includes multiple gates: duration (1-20 seconds), clipping/DC offset, Silero VAD, SNR, bandwidth, DNSMOS (SIG/BAK/OVR), MMS-FA forced alignment, and ASR CER. All measurements are kept as columns for user-adjustable thresholds. Text is normalized using oron_ttss MongolianNormalizer, including number expansion (rejecting guessing word-final suffixes), lowercasing, and abbreviation expansion. Normalized text serves as the training target, CER reference, and published text. License is CC0-1.0, but contributors agreed to use for speech research, not individual voice cloning, so synthesizing someones voice without consent is prohibited. The dataset covers only one language variety of read speech; coverage of accents, dialects, and spontaneous speech is untested. Inferred gender labels (based on F0) may be unreliable; users are advised to filter by the gender_source field.
数据集概述
此数据集是 Mozilla Common Voice 26.0 蒙古语(已清洗) 的质量过滤与标准化子集,专为训练蒙古语(喀尔喀方言、西里尔字母)文本转语音(TTS)系统而构建。由 oron-cleaner 工具从 Common Voice 26.0 蒙古语原始语料库中清洗生成,用于训练 oron-tts 模型。
基本信息
- 许可证:CC0-1.0
- 语言:蒙古语(单一语言,喀尔喀方言,西里尔字母)
- 任务类型:文本转语音、自动语音识别
- 语料规模:10,000-100,000 条音频片段(实际 15,092 条)
- 数据格式:Parquet 分片,音频以 24 kHz 单声道 WAV 格式内嵌
- 音频总量:16.33 小时
- 独立句子:5,635 句
- 已识别说话人:378 人
- 音频时长中位数:3.77 秒
数据划分
| 划分 | 片段数 | 时长 | 说话人数 |
|---|---|---|---|
| train | 14,515 | 15.74 小时 | 252 |
| validation | 115 | 0.13 小时 | 63 |
| test | 75 | 0.07 小时 | 63 |
| withheld | 387 | 0.40 小时 | 95 |
所有数据均在一个文件集合中,通过 split 列区分划分。withheld 划分中的句子已从 train 中移除,作为文本级留出集。
数据列说明
数据集包含 31 个特征列,涵盖:
- 音频内容:
audio(24 kHz WAV)、audio_path(源路径)、path(原始 MP3 路径) - 文本信息:
text(标准化转写文本)、sentence(原始句子) - 说话人属性:
gender、gender_resolved(解析后性别)、gender_source(性别来源)、age、accents、client_id - 质量评分:
align_score(强制对齐置信度)、cer(ASR 字错误率)、snr_db(信噪比)、bandwidth_hz(实际带宽) - 感知质量:DNSMOS 系列指标(
dnsmos_sig、dnsmos_bak、dnsmos_ovr、dnsmos_p808) - 语音特征:
mean_f0_hz(基频均值)、pitch_confidence(基频置信度) - 时长信息:
duration_s(清洗后时长)、duration_tsv(原始时长) - 投票信息:
up_votes、down_votes - 其他标识:
clip_id、segment、variant、len_ratio、locale、split
其中 text 列为训练目标(标准化转写),gender_resolved 与 gender_source 记录性别推断逻辑(自我报告、跨片段传播或基于 F0 推断)。
基因性别分布
| 性别 | 片段数 | 时长 |
|---|---|---|
| 女性 | 6,731 | 7.33 小时 |
| 男性 | 8,194 | 8.82 小时 |
| 未知 | 167 | 0.18 小时 |
清洗流程
每条音频须通过以下全部筛选门槛(按序执行,未通过即丢弃):
- 时长:超出 1-20 秒范围的丢弃
- 削波与直流偏置:连续满幅样本或直流偏置
- Silero VAD:大部分为静音的片段视为录制失败
- 信噪比(SNR):对未修剪信号计算语音区 RMS 与非语音区 RMS 之比
- 带宽:检测真实低通滤波边界
- DNSMOS 感知质量(SIG / BAK / OVR)
- MMS-FA 强制对齐:主要转写文本质量门槛
- ASR 字错误率(CER):次级检查
所有测量值均保留为数据列,用户可根据自身阈值重新过滤。
文本标准化
使用 oron_tts.text.MongolianNormalizer 进行文本标准化:数字展开(对格后缀拒绝猜测)、小型大写字母折叠(如 ЭЗЭНий 转为 Эзэний)、缩写与单位展开。标准化后的字符串同时作为发布的文本、CER 参考和训练目标,三者保持一致。
注意事项
- 语音克隆伦理:贡献者同意将录音用于语音研究,并未同意个人声音的克隆。未经本人同意,不应合成具名或可辨识个人的语音。
- 语料覆盖:仅覆盖一种语言变体的朗读语音,口音、方言和自发语音覆盖未经验证。
- 推断性别标签:当
gender_source为f0时,标签是基于音高的推断而非自我报告。 - 质量门槛的主观性:阈值是针对此语料校准的,不同应用可能需要不同阈值。
- 文本覆盖缺口:文本覆盖 34/35 个西里尔字母,
щ字母从未出现。 - 当前验收状态:总时长未达 25 小时目标(仅 16.3 小时),但男声时长与说话人数已达标准。
引用
如使用此数据集,请引用:
bibtex @misc{orontts_cv_mn, title = {Common Voice 26.0 Mongolian (cleaned)}, author = {Badral, Battseren}, year = {2026}, url = {https://huggingface.co/datasets/btsee/common-voice-26-mn} }
同时请引用上游语料库 Mozilla Common Voice 26.0 Mongolian。此数据集被 btsee/oron-tts(蒙古语 TTS 模型)使用。