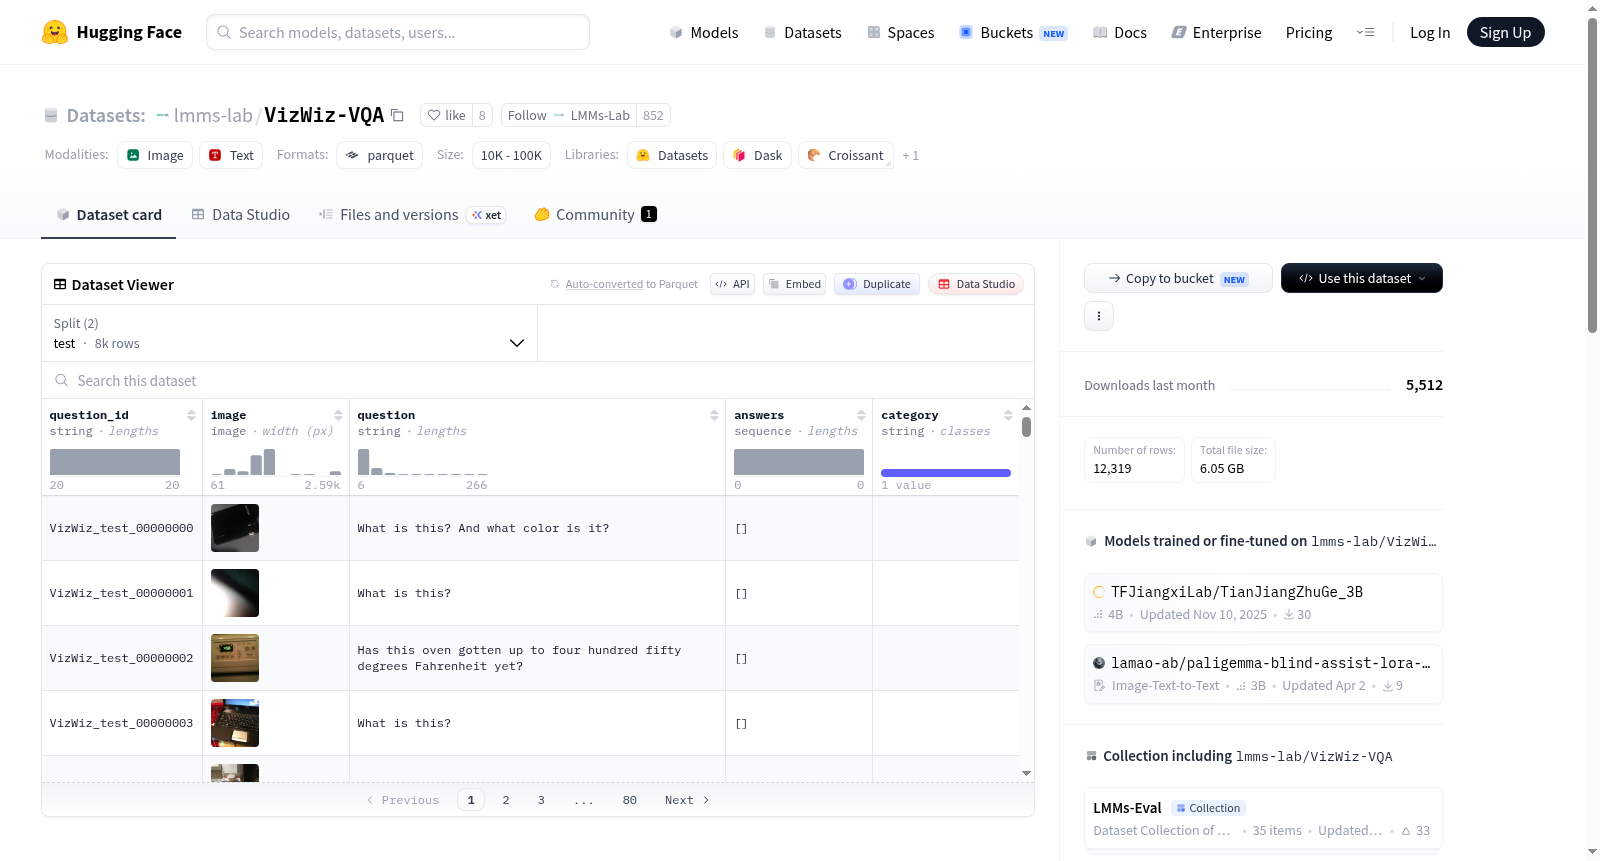
lmms-lab/VizWiz-VQA
收藏资源简介:
--- dataset_info: features: - name: question_id dtype: string - name: image dtype: image - name: question dtype: string - name: answers sequence: string - name: category dtype: string splits: - name: val num_bytes: 2097998373.0 num_examples: 4319 - name: test num_bytes: 3982325314.0 num_examples: 8000 download_size: 6050372614 dataset_size: 6080323687.0 --- # Dataset Card for "VizWiz-VQA" <p align="center" width="100%"> <img src="https://i.postimg.cc/g0QRgMVv/WX20240228-113337-2x.png" width="100%" height="80%"> </p> # Large-scale Multi-modality Models Evaluation Suite > Accelerating the development of large-scale multi-modality models (LMMs) with `lmms-eval` 🏠 [Homepage](https://lmms-lab.github.io/) | 📚 [Documentation](docs/README.md) | 🤗 [Huggingface Datasets](https://huggingface.co/lmms-lab) # This Dataset This is a formatted version of [VizWiz-VQA](https://vizwiz.org/tasks-and-datasets/vqa/). It is used in our `lmms-eval` pipeline to allow for one-click evaluations of large multi-modality models. ``` @inproceedings{gurari2018vizwiz, title={Vizwiz grand challenge: Answering visual questions from blind people}, author={Gurari, Danna and Li, Qing and Stangl, Abigale J and Guo, Anhong and Lin, Chi and Grauman, Kristen and Luo, Jiebo and Bigham, Jeffrey P}, booktitle={Proceedings of the IEEE conference on computer vision and pattern recognition}, pages={3608--3617}, year={2018} } ``` [More Information needed](https://github.com/huggingface/datasets/blob/main/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards)
数据集信息: 特征字段: - 字段名:question_id,数据类型:字符串 - 字段名:image,数据类型:图像 - 字段名:question,数据类型:字符串 - 字段名:answers,数据类型:字符串序列 - 字段名:category,数据类型:字符串 划分集: - 划分集名:val,字节数:2097998373.0,样本数:4319 - 划分集名:test,字节数:3982325314.0,样本数:8000 下载大小:6050372614 数据集总大小:6080323687.0 # 「VizWiz-VQA」数据集卡片 <p align="center" width="100%"> <img src="https://i.postimg.cc/g0QRgMVv/WX20240228-113337-2x.png" width="100%" height="80%"> </p> # 大规模多模态模型评测套件 > 借助`lmms-eval`工具链加速大规模多模态模型(Large-scale Multi-modality Models, LMMs)的研发 🏠 [主页](https://lmms-lab.github.io/) | 📚 [文档](docs/README.md) | 🤗 [Huggingface数据集](https://huggingface.co/lmms-lab) ## 本数据集 本数据集是[VizWiz-VQA](https://vizwiz.org/tasks-and-datasets/vqa/)的格式化版本,可在我们的`lmms-eval`评测流水线中使用,实现大规模多模态模型的一键评测。 @inproceedings{gurari2018vizwiz, title={VizWiz挑战赛:回答视障人士的视觉问题}, author={Gurari, Danna and Li, Qing and Stangl, Abigale J and Guo, Anhong and Lin, Chi and Grauman, Kristen and Luo, Jiebo and Bigham, Jeffrey P}, booktitle={IEEE计算机视觉与模式识别会议论文集}, pages={3608--3617}, year={2018} } [需补充更多信息](https://github.com/huggingface/datasets/blob/main/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards)
数据集概述
数据集信息
特征
- question_id: 字符串类型
- image: 图像类型
- question: 字符串类型
- answers: 字符串序列
- category: 字符串类型
分割
- val:
- 字节数: 2097998373.0
- 样本数: 4319
- test:
- 字节数: 3982325314.0
- 样本数: 8000
大小
- 下载大小: 6050372614
- 数据集大小: 6080323687.0