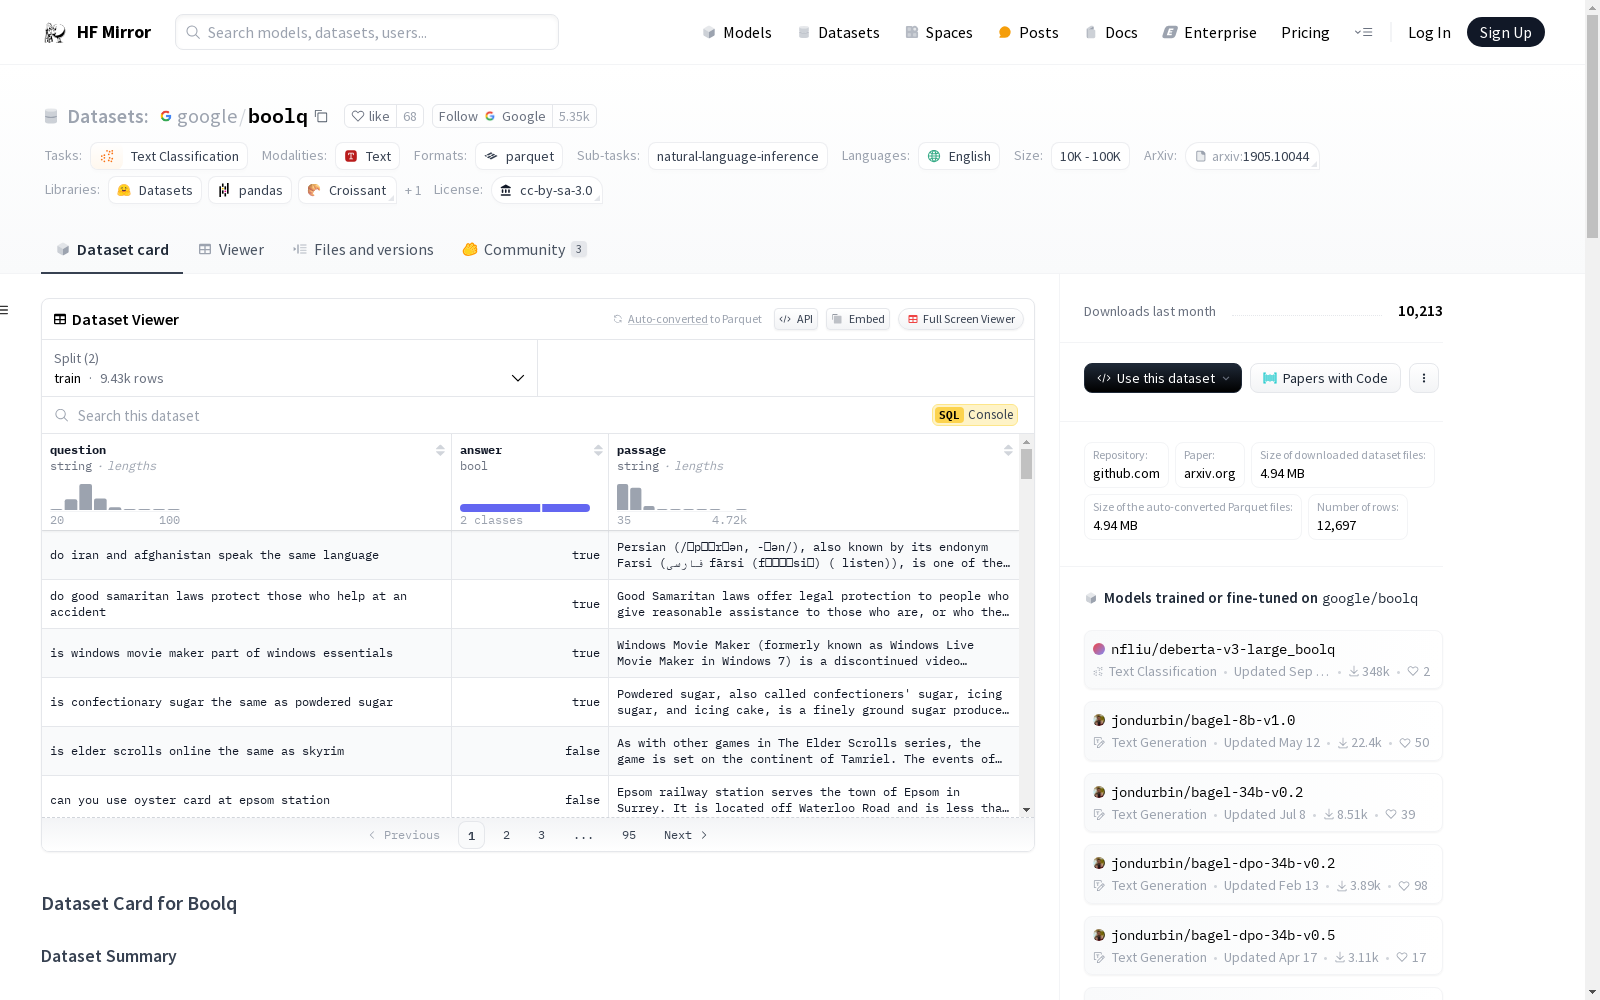
google/boolq
收藏资源简介:
--- annotations_creators: - crowdsourced language_creators: - found language: - en license: - cc-by-sa-3.0 multilinguality: - monolingual size_categories: - 10K<n<100K source_datasets: - original task_categories: - text-classification task_ids: - natural-language-inference paperswithcode_id: boolq pretty_name: BoolQ dataset_info: features: - name: question dtype: string - name: answer dtype: bool - name: passage dtype: string splits: - name: train num_bytes: 5829584 num_examples: 9427 - name: validation num_bytes: 1998182 num_examples: 3270 download_size: 4942776 dataset_size: 7827766 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* --- # Dataset Card for Boolq ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Repository:** https://github.com/google-research-datasets/boolean-questions - **Paper:** https://arxiv.org/abs/1905.10044 - **Point of Contact:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Size of downloaded dataset files:** 8.77 MB - **Size of the generated dataset:** 7.83 MB - **Total amount of disk used:** 16.59 MB ### Dataset Summary BoolQ is a question answering dataset for yes/no questions containing 15942 examples. These questions are naturally occurring ---they are generated in unprompted and unconstrained settings. Each example is a triplet of (question, passage, answer), with the title of the page as optional additional context. The text-pair classification setup is similar to existing natural language inference tasks. ### Supported Tasks and Leaderboards [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Languages [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Dataset Structure ### Data Instances #### default - **Size of downloaded dataset files:** 8.77 MB - **Size of the generated dataset:** 7.83 MB - **Total amount of disk used:** 16.59 MB An example of 'validation' looks as follows. ``` This example was too long and was cropped: { "answer": false, "passage": "\"All biomass goes through at least some of these steps: it needs to be grown, collected, dried, fermented, distilled, and burned...", "question": "does ethanol take more energy make that produces" } ``` ### Data Fields The data fields are the same among all splits. #### default - `question`: a `string` feature. - `answer`: a `bool` feature. - `passage`: a `string` feature. ### Data Splits | name |train|validation| |-------|----:|---------:| |default| 9427| 3270| ## Dataset Creation ### Curation Rationale [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Source Data #### Initial Data Collection and Normalization [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the source language producers? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Annotations #### Annotation process [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the annotators? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Personal and Sensitive Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Discussion of Biases [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Other Known Limitations [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Additional Information ### Dataset Curators [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Licensing Information BoolQ is released under the [Creative Commons Share-Alike 3.0](https://creativecommons.org/licenses/by-sa/3.0/) license. ### Citation Information ``` @inproceedings{clark2019boolq, title = {BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions}, author = {Clark, Christopher and Lee, Kenton and Chang, Ming-Wei, and Kwiatkowski, Tom and Collins, Michael, and Toutanova, Kristina}, booktitle = {NAACL}, year = {2019}, } ``` ### Contributions Thanks to [@lewtun](https://github.com/lewtun), [@lhoestq](https://github.com/lhoestq), [@thomwolf](https://github.com/thomwolf), [@patrickvonplaten](https://github.com/patrickvonplaten), [@albertvillanova](https://github.com/albertvillanova) for adding this dataset.
annotations_creators: - 众包(crowdsourced) language_creators: - 现有公开文本复用 language: - 英语(en) license: - 知识共享署名-相同方式共享3.0协议(cc-by-sa-3.0) multilinguality: - 单语言 size_categories: - 10000 < n < 100000 source_datasets: - 原创数据集 task_categories: - 文本分类 task_ids: - 自然语言推理(Natural Language Inference) paperswithcode_id: boolq pretty_name: BoolQ dataset_info: features: - name: 问题(question) dtype: 字符串 - name: 答案(answer) dtype: 布尔值 - name: 段落(passage) dtype: 字符串 splits: - name: 训练集(train) num_bytes: 5829584 num_examples: 9427 - name: 验证集(validation) num_bytes: 1998182 num_examples: 3270 download_size: 4942776 dataset_size: 7827766 configs: - config_name: 默认配置(default) data_files: - split: 训练集(train) path: data/train-* - split: 验证集(validation) path: data/validation-* # BoolQ数据集卡片 ## 目录 - [数据集描述](#dataset-description) - [数据集摘要](#dataset-summary) - [支持任务与基准榜单](#supported-tasks-and-leaderboards) - [语言](#languages) - [数据集结构](#dataset-structure) - [数据实例](#data-instances) - [数据字段](#data-fields) - [数据划分](#data-splits) - [数据集构建](#dataset-creation) - [构建初衷](#curation-rationale) - [源数据](#source-data) - [标注信息](#annotations) - [个人与敏感信息](#personal-and-sensitive-information) - [数据集使用注意事项](#considerations-for-using-the-data) - [数据集的社会影响](#social-impact-of-dataset) - [偏见讨论](#discussion-of-biases) - [其他已知局限性](#other-known-limitations) - [附加信息](#additional-information) - [数据集维护者](#dataset-curators) - [许可证信息](#licensing-information) - [引用信息](#citation-information) - [贡献致谢](#contributions) ## 数据集描述 - **主页:** [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **代码仓库:** https://github.com/google-research-datasets/boolean-questions - **论文:** https://arxiv.org/abs/1905.10044 - **联系方式:** [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **下载数据集文件大小:** 8.77 MB - **生成后数据集大小:** 7.83 MB - **总磁盘占用空间:** 16.59 MB ### 数据集摘要 BoolQ是一款面向是非类问题的问答数据集,共计包含15942条样本。此类问题均为自然生成,即在无提示、无约束的场景下自发产生。 每条样本均为(问题、段落、答案)三元组,可附加页面标题作为可选上下文。该数据集采用文本对分类的任务设定,与现有自然语言推理任务范式高度相似。 ### 支持任务与基准榜单 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 语言 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 数据集结构 ### 数据实例 #### 默认配置 - **下载数据集文件大小:** 8.77 MB - **生成后数据集大小:** 7.83 MB - **总磁盘占用空间:** 16.59 MB 一条验证集样本示例如下: 该示例过长已被截断: { "answer": false, "passage": ""All biomass goes through at least some of these steps: it needs to be grown, collected, dried, fermented, distilled, and burned...", "question": "does ethanol take more energy make that produces" } ### 数据字段 所有数据划分的字段定义保持一致。 #### 默认配置 - `question`:字符串类型特征字段,存储问题文本 - `answer`:布尔类型特征字段,存储是非类答案 - `passage`:字符串类型特征字段,存储参考段落文本 ### 数据划分 | 划分名称 | 训练集样本数 | 验证集样本数 | |-------|----:|---------:| | 默认配置 | 9427 | 3270 | ## 数据集构建 ### 构建初衷 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 源数据 #### 初始数据收集与标准化处理 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### 源语言文本创作者 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 标注信息 #### 标注流程 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### 标注人员构成 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 个人与敏感信息说明 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 数据集使用注意事项 ### 数据集的社会影响 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 偏见讨论 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 其他已知局限性 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 附加信息 ### 数据集维护者 [更多信息待补充](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 许可证信息 BoolQ采用知识共享署名-相同方式共享3.0(Creative Commons Share-Alike 3.0)协议发布。 ### 引用信息 @inproceedings{clark2019boolq, title = {BoolQ: 探索自然是非类问题的出人意料难度}, author = {Clark, Christopher and Lee, Kenton and Chang, Ming-Wei, and Kwiatkowski, Tom and Collins, Michael, and Toutanova, Kristina}, booktitle = {北美计算语言学协会会议(NAACL)}, year = {2019}, } ### 贡献致谢 感谢[@lewtun](https://github.com/lewtun)、[@lhoestq](https://github.com/lhoestq)、[@thomwolf](https://github.com/thomwolf)、[@patrickvonplaten](https://github.com/patrickvonplaten)、[@albertvillanova](https://github.com/albertvillanova) 为本数据集的收录提供支持。
数据集概述
数据集名称: BoolQ
数据集描述: BoolQ是一个包含15,942个例子的问答数据集,专门用于处理yes/no类型的问题。这些问题是在无提示和不受限制的环境中自然产生的。每个例子包含三个部分:问题(question)、段落(passage)和答案(answer)。
语言: 英语(en)
许可证: 知识共享署名-相同方式共享3.0(cc-by-sa-3.0)
多语言性: 单语种
大小分类: 10K<n<100K
源数据集: 原始数据
任务类别: 文本分类
任务ID: 自然语言推理
数据集特征:
- 问题(question): 数据类型为字符串(string)
- 答案(answer): 数据类型为布尔值(bool)
- 段落(passage): 数据类型为字符串(string)
数据分割:
- 训练集(train): 9,427个例子,数据大小为5,829,584字节
- 验证集(validation): 3,270个例子,数据大小为1,998,182字节
下载大小: 4,942,776字节
数据集大小: 7,827,766字节
配置信息:
- 默认配置(default): 数据文件路径包括训练集和验证集,分别位于
data/train-*和data/validation-*。
许可证信息: BoolQ数据集根据Creative Commons Share-Alike 3.0许可证发布。
引用信息:
@inproceedings{clark2019boolq, title = {BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions}, author = {Clark, Christopher and Lee, Kenton and Chang, Ming-Wei, and Kwiatkowski, Tom and Collins, Michael, and Toutanova, Kristina}, booktitle = {NAACL}, year = {2019}, }
贡献者: 感谢@lewtun, @lhoestq, @thomwolf, @patrickvonplaten, @albertvillanova添加此数据集。