viorra-admissions-essays
收藏资源简介:
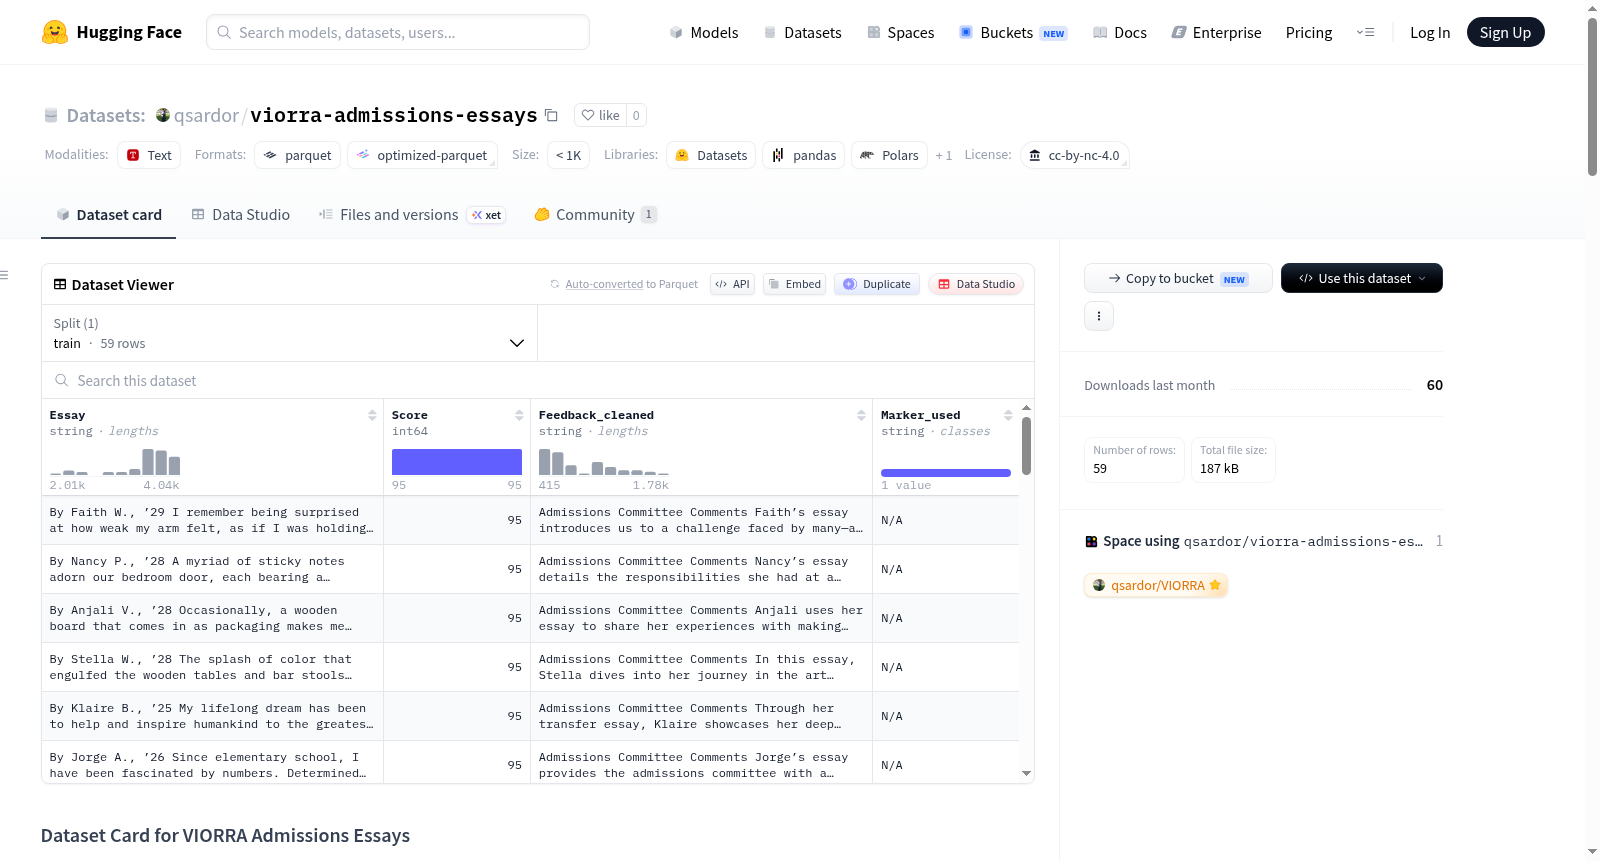
VIORRA Admissions Essays 数据集是一个经过精心整理和验证的数据集,包含59篇成功帮助申请者获得精英大学录取的个人陈述(650词Common App风格文书),并附有来自大学招生委员会的真实、直接的结构性批评反馈。本数据集专为教育技术(EdTech)人工智能模型的检索增强生成(RAG)流程而设计,旨在为大型语言模型(LLM)提供基于现实世界精英录取标准的深度反馈逻辑基础,使其超越通用的“语法检查”建议,提供符合常春藤联盟招生标准的深层、结构性反馈。数据内容为纯英文,每个样本包含Essay(个人陈述全文)、Score(基线分数,默认为95)、Feedback_cleaned(招生委员会官方评论)和Marker_used(元数据标记)四个字段。数据来源于约翰霍普金斯大学官方公开发布的“Essays That Worked”文集(2025至2029届),原始论文由被录取的真实高中生撰写,反馈由本科招生委员会提供,通过自动化Python抓取和解析处理以保持真实性。数据集适用于构建RAG系统改进AI反馈生成、训练自动作文评分模型,以及作为教育研究工具,但根据CC BY-NC 4.0许可协议,禁止用于训练AI模型代写论文(剽窃生成)和未经许可的商业用途,并存在机构偏见(偏向约翰霍普金斯大学特质)和幸存者偏差(仅含成功论文)。
The VIORRA Admissions Essays dataset is a meticulously curated and validated collection containing 59 personal statements (650-word Common App style essays) that successfully helped applicants gain admission to elite universities, accompanied by real, direct structural critique feedback from university admissions committees. This dataset is specifically designed for the Retrieval-Augmented Generation (RAG) process of educational technology (EdTech) AI models, aiming to provide a deep feedback logic foundation for large language models (LLMs) based on real-world elite admission standards, enabling them to go beyond generic grammar check suggestions and offer deep, structural feedback aligned with Ivy League admissions criteria. The data content is entirely in English, with each sample including four fields: Essay (full text of the personal statement), Score (baseline score for accepted essays, defaulting to 95), Feedback_cleaned (official comments from the admissions committee explaining the essays success), and Marker_used (metadata marker used by automated scraping tools to separate essays and feedback). The data is sourced from Johns Hopkins Universitys publicly released Essays That Worked collections (for the classes of 2025 to 2029), with original essays written by real high school students admitted to Johns Hopkins and feedback provided by the universitys undergraduate admissions committee, processed through automated Python scraping and parsing to preserve authenticity. The dataset is suitable for building RAG systems to improve AI feedback generation, training or fine-tuning automated essay scoring models based on elite university grading standards, and serving as an educational tool for students to research successful essay examples. Under its CC BY-NC 4.0 license, it is strictly prohibited for training AI models to write essays for students (plagiarism generation) or for commercial use without separate written permission from the authors, and it notes institutional bias (feedback favoring traits valued by Johns Hopkins) and survivor bias (including only successful essays).
数据集概述:VIORRA Admissions Essays
该数据集包含59篇经过严格筛选的大学入学个人陈述(Common App风格,650词),每篇均配有招生委员会的官方反馈和评论,旨在提升AI在入学文书评审方面的反馈质量。
核心信息
- 许可证: CC BY-NC 4.0(非商业用途)。
- 语言: 英语。
- 创建者: Sardor & The Antigravity AI Agent Team。
- 数据来源: 约翰霍普金斯大学官方“Essays That Worked”资料库(2025至2029届)。
- 数据大小: 下载大小178,333字节,数据集总大小259,224字节。
- 数据拆分: 仅包含训练集(train),共59个样本。
数据集结构
每个数据点包含以下字段:
- Essay (string): 被录取学生的个人陈述全文。
- Score (int64): 基准分数,默认值为95。
- Feedback_cleaned (string): 招生委员会对文章成功原因的官方评语。
- Marker_used (string): 用于从原文中分离文章与反馈的标记字符串。
数据用途
- 直接用途:
- RAG系统: 将真实作文与评语注入大语言模型上下文,改进AI反馈生成。
- 自动作文评分: 基于藤校评分标准训练或微调模型。
- 教育工具: 为学生提供成功申请文书的数据库。
- 超出范围的使用:
- 禁止用于训练AI代写作文。
- 未经许可禁止商业使用。
数据创建与处理
- 收集方法: 使用
trafilatura库从HTML页面自动抓取原始文本。 - 处理方法: 通过解析算法识别内部标记(如“Admissions Committee Comments”),将学生作文与大学反馈分离。
- 注释: 未进行二次注释,保留原始文本和官方反馈的完整性。注释者为约翰霍普金斯大学本科招生委员会。
- 隐私信息: 大学在公开发布前已对高度敏感的个人身份信息(如姓氏、完整地址)进行脱敏处理。
偏见、风险与局限性
- 机构偏见: 数据主要来自约翰霍普金斯大学,反馈偏好该校看重的特质(如求知欲、研究能力、协作精神),与其他名校可能存在差异。
- 幸存者偏差: 仅包含成功录取的文书,缺少失败案例作为对比。
- 建议: 若用于构建通用入学指导系统,应结合其他院校的多样化样本以平衡偏差。
引用
若在研究中引用本数据集,请使用以下格式:
bibtex @dataset{viorra_admissions_essays_2026, author = {Sardor}, title = {VIORRA Admissions Essays Dataset}, year = {2026}, publisher = {Hugging Face}, url = {https://huggingface.co/datasets/qsardor/viorra-admissions-essays}, license = {CC BY-NC 4.0} }
联系方式
- 数据集卡作者: Sardor & The Antigravity AI Agent Team。
- 联系: https://huggingface.co/qsardor