6k-diverse-reference-voices
收藏资源简介:
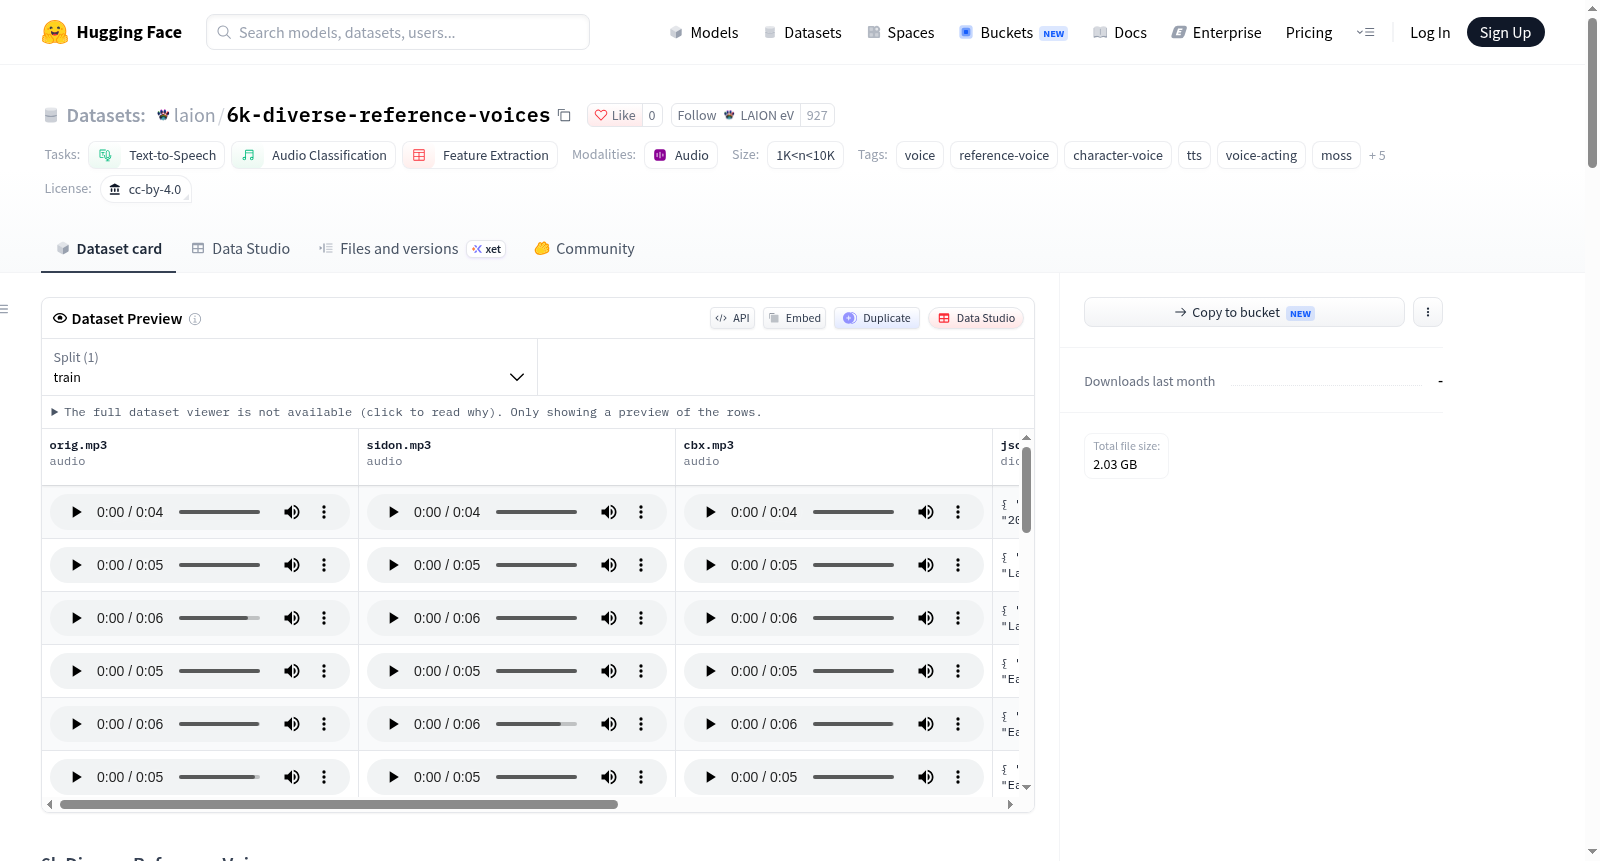
6k Diverse Reference Voices 是一个包含6064个许可宽松的参考语音数据集,旨在为表达性语音生成(如配音)提供选角参考。所有语音均基于CC-BY-4.0许可,来源包括合成生成或从Emilia数据集的CC-BY部分提取。每个语音均由Gemini自动标注了名称、标签行、语言、口音、年龄/性别、音域、音色、独特特征、情感范围、四种流派的选角建议、自由文本标签和搜索文本,并在99个测量维度上评分:57个VoiceNet语音质量轴、40个Empathic-Insight情感轴以及真实感和爆发混合度。每个语音提供三种音频变体:原始剪辑(orig)、经SIDON降噪并响度归一化的版本(sidon)、以及经Chatterbox自转换的修复版本(cbx),并附有每种变体的DNSMOS分数。数据集以WebDataset分片(12个tar文件,约2GB)和扁平parquet索引(每行一个语音,30列)的形式分发。元数据包含语音身份、质量分数、最佳版本、关键99维分数等。适用于文本转语音、音频分类、特征提取等任务,尤其适合需要多样化和高质量参考语音的语音合成与配音选角场景。
6k Diverse Reference Voices is a dataset containing 6064 permissively licensed reference voices, designed to provide casting references for expressive speech generation (e.g., dubbing). All voices are under CC-BY-4.0 license, sourced from synthetic generation or extracted from the CC-BY portion of the Emilia dataset. Each voice is automatically annotated by Gemini with name, tagline, language, accent, age/gender, vocal range, timbre, unique characteristics, emotional range, casting suggestions for four genres, free-text tags, and search text, and scored on 99 measurement dimensions: 57 VoiceNet voice quality axes, 40 Empathic-Insight emotional axes, as well as realism and outburst blend. Each voice includes three audio variants: original clip (orig), noise-reduced and loudness-normalized version using SIDON (sidon), and repaired version via Chatterbox self-conversion (cbx), with DNSMOS scores for each variant. The dataset is distributed as WebDataset shards (12 tar files, ~2GB) and a flat parquet index (one voice per row, 30 columns). Metadata includes voice identity, quality scores, best variant, key 99-dimensional scores, etc. It is suitable for text-to-speech, audio classification, feature extraction tasks, especially for speech synthesis and dubbing casting scenarios requiring diverse and high-quality reference voices.
6k Diverse Reference Voices 数据集总结
基本信息
- 数据集名称:6k Diverse Reference Voices
- 数据集地址:https://huggingface.co/datasets/laion/6k-diverse-reference-voices
- 许可协议:CC-BY-4.0
- 数据规模:6,064 个参考声音(1K < n < 10K)
- 任务类别:text-to-speech、audio-classification、feature-extraction
- 标签:voice、reference-voice、character-voice、tts、voice-acting、moss、voice-search、speech、audio、casting、synthetic
数据集概述
包含 6,064 个许可宽松的参考声音,用于选角富有表现力的配音生成。所有声音均可宽松使用,来源为合成创建或从 Emilia 的 CC-BY 部分提取,采用 CC-BY-4.0 许可。
来源与署名:衍生自 TTS-AGI/moss-reference-voices-consolidated(CC-BY-4.0),由 LAION 重新发布并附带澄清的元数据文档。使用需同时署名 LAION 与原始 TTS-AGI 来源。
注释信息
每个声音由 Gemini 自动注释:名称、标语、语言、口音、年龄/性别判读、语域、音色、显著特征、情感范围、4 种类型的选角建议、自由文本标签、搜索文本。并在 99 个测量维度上评分:57 个 VoiceNet 音质轴、40 个 Empathic-Insight 情感轴,外加 genuineness 和 burst-blend。每个声音附带三个音频变体及每变体 DNSMOS。
实时搜索 UI:https://projects.laion.ai/moss-reference-voice-search/
组成结构
按 source 字段计数(经 metadata.parquet 验证):
source |
数量 | 说明 |
|---|---|---|
emolia |
3,000 | 源自 Emilia 的声音,保留可追溯 id(emolia_c*)。 |
char |
1,336 | 合成角色声音(k<n>_age<n>_bg<n>)。 |
refvoice |
956 | 合成重释参考声音,不透明 id。 |
mediathek |
472 | 合成德语重释声音,不透明 id。 |
anime |
300 | 合成动漫衍生重释声音,英语表达,不透明 id。 |
| 合计 | 6,064 |
语言(Gemini 识别,4,727/6,064 非空):英语 4,250 · 德语 473 · 空 1,337 · 其余 4。 性别判读:男性 4,262 · 女性 1,675 · 中性 109 · 非人类 8 · 边缘情况 10。
三个音频变体
每个声音对同一演示片段有三个并行渲染:
| 变体 | tar 后缀 | 说明 |
|---|---|---|
| orig | <cid>.orig.mp3 |
原始演示片段。 |
| sidon | <cid>.sidon.mp3 |
SIDON 去噪 + 响度归一化的 orig。可能在部分片段引入金属鸣响/过度平滑。 |
| cbx | <cid>.cbx.mp3 |
sidon 片段的 Chatterbox 自转换(伪影清理,偶尔弱化质感)。 |
数据集级平均 DNSMOS-OVRL 持平(orig 3.343、sidon 3.346、cbx 3.344),但每个声音约 62% 在某一处理变体上更优(orig 胜出 2,317 = 38.2%,sidon 1,940 = 32.0%,cbx 1,807 = 29.8%)。建议使用预计算的 best_version 字段(每个声音的 DNSMOS 最大值),而非全数据集默认使用某一变体。
文件布局
data/voices-0000.tar … voices-0011.tar # WebDataset 分片,每片约 505-506 个声音,总计约 2 GB metadata.parquet # 扁平索引,每个声音一行(6064 x 30) annotations/ dims.npy # (6064, 99) float32 — 基于 ORIG 音频的 99 维评分 dims_enh.npy # (6064, 99) float32 — 基于 SIDON 音频的 99 维评分 dim_catalog.json # 99 维模式:[{i, code, name, group, desc}] dnsmos.json # {cid: {orig, sidon, cbx}} 每变体 DNSMOS-OVRL dnsmos_stats.json # 均值 + 每变体胜出计数 / win_pct search_tool/ # FastAPI 搜索服务器 + pipeline + 演示页面 README.md / LICENSE # 本文件 / CC-BY-4.0
WebDataset 分片(data/*.tar)
一个声音的成员是连续的:
<cid>.orig.mp3 # 原始演示片段 <cid>.sidon.mp3 # SIDON 去噪 + 响度归一化 <cid>.cbx.mp3 # sidon 的 Chatterbox 自转换 <cid>.json # 完整的每声音记录
<cid>.json 记录 = 完整声音条目(name、tagline、gender、age、language、accent、register、timbre_profile、distinctive_features、emotional_range、casting {classic_fantasy, sci_fi, mystery_horror, contemporary}、tags、search_text、legacy scores、source)外加:
json { "dnsmos": {"orig": 3.44, "sidon": 3.40, "cbx": 3.29}, "best_version": "orig", "dims_raw": [99 floats, order = annotations/dim_catalog.json, scored on orig], "dims_enh": [99 floats, same order, scored on sidon] }
加载示例: python import webdataset as wds ds = wds.WebDataset("hf://datasets/LAION/6k-diverse-reference-voices/data/voices-{0000..0011}.tar").decode() for sample in ds: cid = sample["key"] rec = sample["json"] # dict with dnsmos, best_version, dims_raw, dims_enh print(cid, rec["name"], rec["best_version"])
metadata.parquet — 扁平索引(每声音一行)
共 30 列:
- 身份 / 选角:
cid, name, gender, age, language, accent, tagline, tags (list<string>), source, shard - 每变体质量:
dnsmos_orig, dnsmos_sidon, dnsmos_cbx(float,DNSMOS-OVRL 0–5,越高越好)、best_version(orig|sidon|cbx= DNSMOS 最大值) - 关键 99 维值(两种评分)(
dim_*= 基于 orig,dim_*_enh= 基于 sidon):dim_GEND (+_enh)感知性别(越高越男性化)dim_AGEV (+_enh)感知年龄dim_GENU (+_enh)真实度(听起来像真实人类录音)dim_BLEND (+_enh)声音爆发混合质量dim_BKGN (+_enh)背景噪声水平dim_VALN (+_enh)/dim_AROU (+_enh)情感效价 / 唤醒度dim_WARM (+_enh)声音温暖度
使用示例: python import pandas as pd df = pd.read_parquet("metadata.parquet") loud_masculine = df[(df.dim_GEND > 4) & (df.dnsmos_orig > 3.4)]
metadata.parquet 的行顺序 == annotations/dims.npy / dims_enh.npy 的行顺序。
99 维评分(annotations/)
dim_catalog.json:99 个{i, code, name, group, desc}的列表,i=.npy文件的列索引。- 分组:
emonet40 个(索引 0–39,越高情感越强)、voicenet57 个(索引 40–96,音色/韵律/语域/风格)、quality2 个(索引 97GENU真实度、98BLEND声音爆发混合)。
- 分组:
dims.npy:float32(6064, 99),基于 orig 音频评分。dims_enh.npy:同形状,基于 sidon 音频评分。无 NaN。观测范围约 −3.9 … 12.2(原始回归器输出,未裁剪至 0–6)。- 每分片的
dims_raw== 对应dims.npy行;dims_enh== 对应dims_enh.npy行。 dnsmos.json:{cid: {"orig": float, "sidon": float, "cbx": float}},覆盖全部 6,064 个声音。
许可
CC-BY-4.0。可共享和改编,需署名 LAION 及原始 TTS-AGI/moss-reference-voices-consolidated 来源。
搜索工具
search_tool/ 包含 FastAPI 服务器(BM25 / 句子嵌入 / VoiceCLAP 文本→音频相似度,可对任意 99 维进行可选 AND 过滤)、pipeline 脚本(SIDON、Chatterbox 自转换、DNSMOS、99 维评分、VoiceCLAP、组装)以及实时演示复现器。