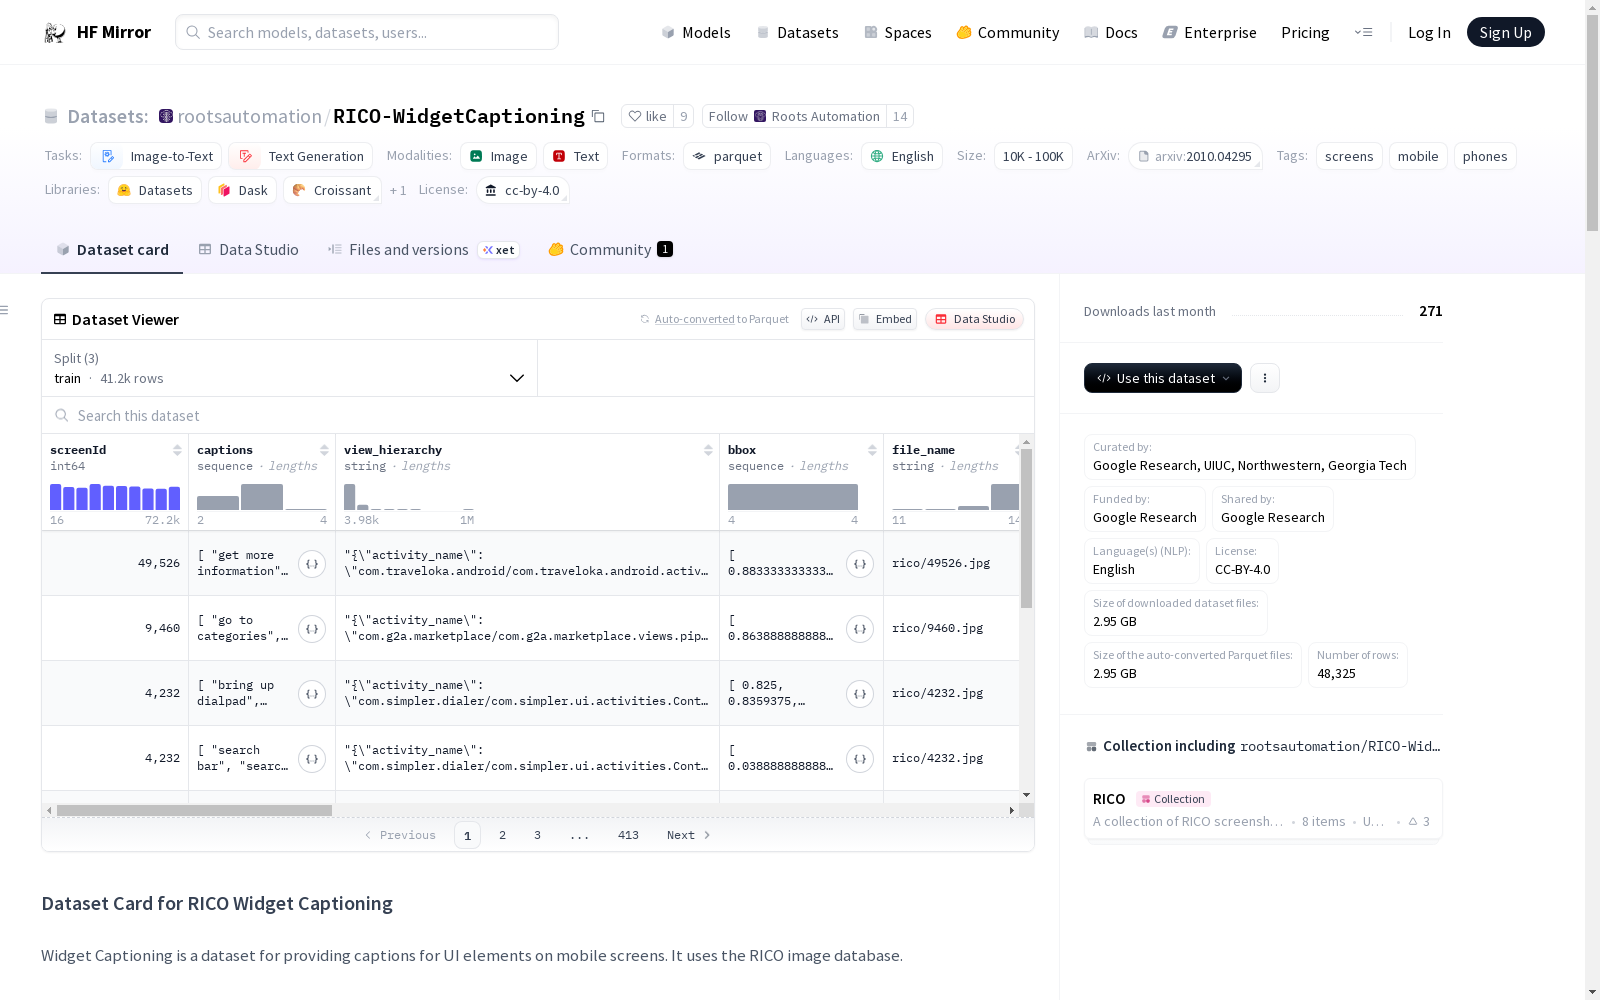
rootsautomation/RICO-WidgetCaptioning
收藏资源简介:
--- language: - en license: cc-by-4.0 size_categories: - 10K<n<100K task_categories: - image-to-text - text-generation pretty_name: Widget Captioning tags: - screens - mobile - phones dataset_info: features: - name: screenId dtype: int64 - name: captions sequence: string - name: view_hierarchy dtype: string - name: bbox sequence: float64 - name: file_name dtype: string - name: file_name_semantic dtype: string - name: semantic_annotations dtype: string - name: app_package_name dtype: string - name: play_store_name dtype: string - name: category dtype: string - name: average_rating dtype: float64 - name: number_of_ratings dtype: string - name: number_of_downloads dtype: string - name: file_name_icon dtype: string - name: image dtype: image - name: image_icon dtype: image - name: image_semantic dtype: image splits: - name: train num_bytes: 10278117710.220001 num_examples: 41221 - name: val num_bytes: 880438420.595 num_examples: 3483 - name: test num_bytes: 987366583.47 num_examples: 3621 download_size: 2945501992 dataset_size: 12145922714.285 configs: - config_name: default data_files: - split: train path: data/train-* - split: val path: data/val-* - split: test path: data/test-* --- # Dataset Card for RICO Widget Captioning Widget Captioning is a dataset for providing captions for UI elements on mobile screens. It uses the RICO image database. ## Dataset Details ### Dataset Description - **Curated by:** Google Research, UIUC, Northwestern, Georgia Tech - **Funded by:** Google Research - **Shared by:** Google Research - **Language(s) (NLP):** English - **License:** CC-BY-4.0 ### Dataset Sources - **Repository:** - [google-research-datasets/widget-caption](https://github.com/google-research-datasets/widget-caption) - [RICO raw downloads](http://www.interactionmining.org/rico.html) - **Paper:** - [Widget Captioning: Generating Natural Language Description for Mobile User Interface Elements](https://arxiv.org/abs/2010.04295) - [Rico: A Mobile App Dataset for Building Data-Driven Design Applications](https://dl.acm.org/doi/10.1145/3126594.3126651) ## Uses This dataset is for developing multimodal automations for mobile screens. ### Direct Use - Enhancing screen readers - Screen indexing - Conversational mobile applications - Q&A on screens ## Dataset Structure - `screenId`: Unique RICO screen ID - `image`: RICO screenshot - `image_icon`: Google Play Store icon for the app - `image_semantic`: Semantic RICO screenshot; details are abstracted away to main visual UI elements - `file_name`: Image local filename - `file_name_icon`: Icon image local filename - `file_name_semantic`: Screenshot Image as a semantic annotated image local filename - `captions`: A list of string captions - `bbox`: The bounding box for the widget being captioned, relatively scaled with the image size so that coordinates are in [0, 1] - `app_package_name`: Android package name - `play_store_name`: Google Play Store name - `category`: Type of category of the app - `number_of_downloads`: Number of downloads of the app (as a coarse range string) - `number_of_ratings`: Number of ratings of the app on the Google Play store (as of collection) - `average_rating`: Average rating of the app on the Google Play Store (as of collection) - `semantic_annotations`: Reduced view hierarchy, to the semantically-relevant portions of the full view hierarchy. It corresponds to what is visualized in `image_semantic` and has a lot of details about what's on screen. It is stored as a JSON object string. ## Dataset Creation ### Curation Rationale - RICO rationale: Create a broad dataset that can be used for UI automation. An explicit goal was to develop automation software that can validate an app's design and assess whether it achieves its stated goal. - Widget Captioning rationale: Create a dataset that helps machines reason about UI elements on screens ### Source Data - RICO: Mobile app screenshots, collected on Android devices. - Widget Captioning: Human annotated concise captions for widgets on screen #### Data Collection and Processing - RICO: Human and automated collection of Android screens. ~9.8k free apps from the Google Play Store. - Widget Captioning: Takes the subset of screens used in RICO, eliminates screens with missing or inaccurate view hierarchies. #### Who are the source data producers? - RICO: 13 human workers (10 from the US, 3 from the Philippines) through UpWork. - Widget Captioning: 5.4k annotators through Amazon Mechanical Turk ## Citation ### RICO **BibTeX:** ```misc @inproceedings{deka2017rico, title={Rico: A mobile app dataset for building data-driven design applications}, author={Deka, Biplab and Huang, Zifeng and Franzen, Chad and Hibschman, Joshua and Afergan, Daniel and Li, Yang and Nichols, Jeffrey and Kumar, Ranjitha}, booktitle={Proceedings of the 30th annual ACM symposium on user interface software and technology}, pages={845--854}, year={2017} } ``` **APA:** Deka, B., Huang, Z., Franzen, C., Hibschman, J., Afergan, D., Li, Y., ... & Kumar, R. (2017, October). Rico: A mobile app dataset for building data-driven design applications. In Proceedings of the 30th annual ACM symposium on user interface software and technology (pp. 845-854). ### Widget Captioning **BibTeX:** ```misc @inproceedings{li2020widget, title={Widget Captioning: Generating Natural Language Description for Mobile User Interface Elements}, author={Li, Yang and Li, Gang and He, Luheng and Zheng, Jingjie and Li, Hong and Guan, Zhiwei}, booktitle={Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)}, pages={5495--5510}, year={2020} } ``` **APA:** Li, Y., Li, G., He, L., Zheng, J., Li, H., & Guan, Z. (2020, November). Widget Captioning: Generating Natural Language Description for Mobile User Interface Elements. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) (pp. 5495-5510). ## Dataset Card Authors Hunter Heidenreich, Roots Automation ## Dataset Card Contact hunter "DOT" heidenreich "AT" rootsautomation "DOT" com
--- language: - 英语 license: cc-by-4.0 size_categories: - 10000 < 样本数量 < 100000 task_categories: - 图像到文本 - 文本生成 pretty_name: 组件字幕(Widget Captioning) tags: - 屏幕 - 移动端 - 手机 dataset_info: features: - name: screenId dtype: int64 - name: captions sequence: 字符串 - name: view_hierarchy dtype: 字符串 - name: bbox sequence: float64 - name: file_name dtype: 字符串 - name: file_name_semantic dtype: 字符串 - name: semantic_annotations dtype: 字符串 - name: app_package_name dtype: 字符串 - name: play_store_name dtype: 字符串 - name: category dtype: 字符串 - name: average_rating dtype: float64 - name: number_of_ratings dtype: 字符串 - name: number_of_downloads dtype: 字符串 - name: file_name_icon dtype: 字符串 - name: image dtype: 图像 - name: image_icon dtype: 图像 - name: image_semantic dtype: 图像 splits: - name: 训练集(train) num_bytes: 10278117710.220001 num_examples: 41221 - name: 验证集(val) num_bytes: 880438420.595 num_examples: 3483 - name: 测试集(test) num_bytes: 987366583.47 num_examples: 3621 download_size: 2945501992 字节 dataset_size: 12145922714.285 字节 configs: - config_name: 默认(default) data_files: - split: train path: data/train-* - split: val path: data/val-* - split: test path: data/test-* --- # RICO 组件字幕数据集卡片(RICO Widget Captioning) 组件字幕(Widget Captioning)是一款用于为移动屏幕上的用户界面(UI)元素生成字幕的数据集,其基于RICO图像数据库构建。 ## 数据集详情 ### 数据集描述 - "整理方":谷歌研究院、伊利诺伊大学厄巴纳-香槟分校(UIUC)、西北大学、佐治亚理工学院 - "资助方":谷歌研究院 - "共享方":谷歌研究院 - "自然语言处理所用语言":英语 - "许可协议":CC-BY-4.0 ### 数据集来源 - "代码仓库": - [google-research-datasets/widget-caption](https://github.com/google-research-datasets/widget-caption) - [RICO 原始数据集下载页](http://www.interactionmining.org/rico.html) - "相关论文": - [《组件字幕:为移动用户界面元素生成自然语言描述》(Widget Captioning: Generating Natural Language Description for Mobile User Interface Elements)](https://arxiv.org/abs/2010.04295) - [《RICO:一款用于构建数据驱动设计应用的移动应用数据集》(Rico: A Mobile App Dataset for Building Data-Driven Design Applications)](https://dl.acm.org/doi/10.1145/3126594.3126651) ## 使用场景 本数据集用于开发移动屏幕的多模态自动化工具。 ### 直接应用场景 - 增强屏幕阅读器功能 - 屏幕索引构建 - 对话式移动应用开发 - 屏幕相关问答系统 ## 数据集结构 - `screenId`:唯一的RICO屏幕标识符 - `image`:RICO屏幕截图 - `image_icon`:对应应用的谷歌应用商店图标 - `image_semantic`:语义化RICO屏幕截图,已将细节抽象为主要视觉用户界面(UI)元素 - `file_name`:图像本地文件名 - `file_name_icon`:图标图像本地文件名 - `file_name_semantic`:语义标注截图的本地文件名 - `captions`:字符串字幕列表 - `bbox`:待标注组件的边界框,相对于图像尺寸进行缩放,坐标范围为[0, 1] - `app_package_name`:Android应用包名 - `play_store_name`:谷歌应用商店应用名称 - `category`:应用所属类别 - `number_of_downloads`:应用下载量(以粗略范围字符串形式存储) - `number_of_ratings`:谷歌应用商店中该应用的评分数量(数据收集时的统计值) - `average_rating`:谷歌应用商店中该应用的平均评分(数据收集时的统计值) - `semantic_annotations`:简化后的视图层级,仅保留完整视图层级中与语义相关的部分,对应`image_semantic`中的可视化内容,包含屏幕上所有元素的详细信息,以JSON对象字符串形式存储。 ## 数据集构建 ### 构建初衷 - RICO数据集构建初衷:构建可用于用户界面自动化的大规模数据集,核心目标是开发能够验证应用设计并评估其是否达成既定目标的自动化软件。 - 组件字幕(Widget Captioning)数据集构建初衷:创建一款可帮助机器理解屏幕上用户界面(UI)元素的数据集。 ### 源数据 - RICO:在Android设备上收集的移动应用屏幕截图 - 组件字幕(Widget Captioning):针对屏幕上的UI组件的人工标注简洁字幕 #### 数据收集与处理 - RICO:通过人工与自动化手段收集Android设备屏幕,涵盖谷歌应用商店中约9800款免费应用 - 组件字幕(Widget Captioning):从RICO数据集的屏幕样本中筛选,移除缺失或视图层级不准确的样本 #### 数据源生产者 - RICO:通过UpWork平台招募的13名标注人员(10名来自美国,3名来自菲律宾) - 组件字幕(Widget Captioning):通过亚马逊众包平台(Amazon Mechanical Turk)招募的5400名标注人员 ## 引用信息 ### RICO 数据集 **BibTeX格式**: misc @inproceedings{deka2017rico, title={Rico: A mobile app dataset for building data-driven design applications}, author={Deka, Biplab and Huang, Zifeng and Franzen, Chad and Hibschman, Joshua and Afergan, Daniel and Li, Yang and Nichols, Jeffrey and Kumar, Ranjitha}, booktitle={Proceedings of the 30th annual ACM symposium on user interface software and technology}, pages={845--854}, year={2017} } **APA格式**: Deka, B., Huang, Z., Franzen, C., Hibschman, J., Afergan, D., Li, Y., ... & Kumar, R. (2017, 10月). RICO: 一款用于构建数据驱动设计应用的移动应用数据集. 见第30届ACM用户界面软件与技术年会论文集 (pp. 845-854). ### 组件字幕(Widget Captioning)数据集 **BibTeX格式**: misc @inproceedings{li2020widget, title={Widget Captioning: Generating Natural Language Description for Mobile User Interface Elements}, author={Li, Yang and Li, Gang and He, Luheng and Zheng, Jingjie and Li, Hong and Guan, Zhiwei}, booktitle={Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)}, pages={5495--5510}, year={2020} } **APA格式**: Li, Y., Li, G., He, L., Zheng, J., Li, H., & Guan, Z. (2020, 11月). 组件字幕:为移动用户界面元素生成自然语言描述. 见2020年经验方法自然语言处理会议(EMNLP)论文集 (pp. 5495-5510). ## 数据集卡片作者 亨特·海登赖希(Hunter Heidenreich),Roots自动化公司 ## 数据集卡片联系人 hunter "DOT" heidenreich "AT" rootsautomation "DOT" com
数据集概述
基本信息
- 名称: Widget Captioning
- 语言: 英语
- 许可证: CC-BY-4.0
- 大小: 10K<n<100K
- 任务类别: image-to-text, text-generation
- 标签: screens, mobile, phones
数据集内容
- 特征:
screenId: 整数,唯一屏幕IDcaptions: 字符串序列,屏幕描述view_hierarchy: 字符串,视图层次结构bbox: 浮点数序列,边界框坐标file_name: 字符串,图像本地文件名file_name_semantic: 字符串,语义注释图像本地文件名semantic_annotations: 字符串,语义注释app_package_name: 字符串,Android包名play_store_name: 字符串,Google Play商店名称category: 字符串,应用类别average_rating: 浮点数,应用平均评分number_of_ratings: 字符串,应用评分数量number_of_downloads: 字符串,应用下载数量file_name_icon: 字符串,图标图像本地文件名image: 图像数据类型image_icon: 图像数据类型,应用图标image_semantic: 图像数据类型,语义截图
数据集结构
- 分割:
train: 41221个样本,大小10278117710.220001字节val: 3483个样本,大小880438420.595字节test: 3621个样本,大小987366583.47字节
- 下载大小: 2945501992字节
- 数据集大小: 12145922714.285字节
数据集创建
- 来源数据:
- RICO: 移动应用截图,Android设备收集
- Widget Captioning: 人工注释的屏幕小部件简短描述
- 数据收集和处理:
- RICO: 人工和自动收集,约9.8k免费应用
- Widget Captioning: 从RICO中筛选,移除缺失或不准确的视图层次结构的屏幕
- 数据生产者:
- RICO: 13名人工工作者
- Widget Captioning: 5.4k名注释者通过Amazon Mechanical Turk