Mouwiya/Video-10M
收藏资源简介:
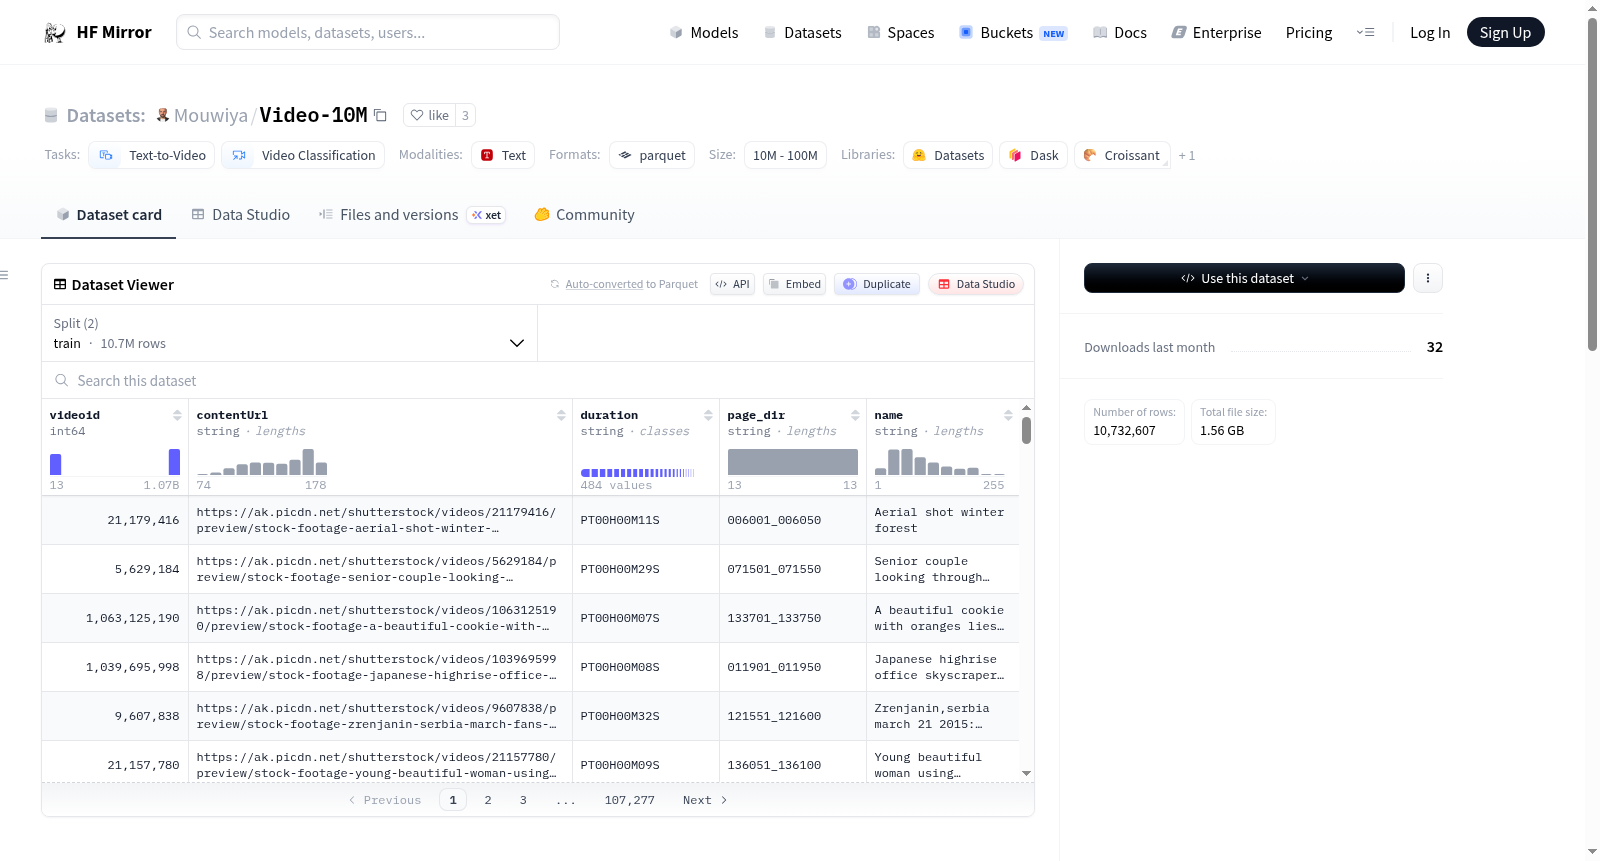
--- dataset_info: features: - name: videoid dtype: int64 - name: contentUrl dtype: string - name: duration dtype: string - name: page_dir dtype: string - name: name dtype: string splits: - name: train num_bytes: 2993227031 num_examples: 10727607 - name: validation num_bytes: 1394310 num_examples: 5000 download_size: 1564635003 dataset_size: 2994621341 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* task_categories: - text-to-video - video-classification size_categories: - 10M<n<100M --- # Dataset Name: Video-10M ## Description: Video-10M is a dataset consisting of 10 million videos, each accompanied by metadata including video ID, content URL, duration, page directory, and name. The dataset covers a wide range of video content, from nature scenes and outdoor activities to culinary arts and urban landscapes. It provides a diverse collection of videos suitable for various video classification tasks. ## Split Information: - Train Split: Contains 10,727,607 samples. - Validation Split: Contains 5,000 samples. ## Features: - videoid: Unique identifier for the video. - contentUrl: URL or path to access the video content. - duration: Duration of the video in hours, minutes, and seconds. - page_dir: Directory or category associated with the video. - name: Descriptive name or title for the video. ## Usage: The dataset can be used for a wide range of video classification tasks, including but not limited to content categorization, scene recognition, activity recognition, and object detection. Researchers, developers, and practitioners can leverage this dataset to train and evaluate video classification models across different domains and applications. ## Download ```python from datasets import load_dataset, Dataset #Load the dataset dataset = load_dataset("Mouwiya/Video-10M") ``` ## Contact **Mouwiya S. A. Al-Qaisieh** mo3awiya@gmail.com
dataset_info: features: - name: videoid(视频ID) dtype: int64 - name: contentUrl(内容URL) dtype: string - name: duration(时长) dtype: string - name: page_dir(页面目录) dtype: string - name: name(名称) dtype: string splits: - name: train(训练集) num_bytes: 2993227031 num_examples: 10727607 - name: validation(验证集) num_bytes: 1394310 num_examples: 5000 download_size: 1564635003 dataset_size: 2994621341 configs: - config_name: default(默认配置) data_files: - split: train(训练集) path: data/train-* - split: validation(验证集) path: data/validation-* task_categories: - text-to-video(文本到视频) - video-classification(视频分类) size_categories: - 10M<n<100M --- # 数据集名称:Video-10M ## 数据集描述: Video-10M是一个包含1000万条视频的数据集,每条视频均附带元数据,涵盖视频ID(videoid)、内容访问URL(contentUrl)、时长(duration)、页面目录(page_dir)以及视频名称(name)。该数据集覆盖了广泛的视频内容范畴,从自然景观、户外活动到烹饪艺术与城市风貌均有涉及,提供了多样化的视频集合,适用于各类视频分类任务。 ## 划分信息: - 训练集:包含10,727,607条样本。 - 验证集:包含5,000条样本。 ## 特征说明: - videoid:视频的唯一标识符。 - contentUrl:用于访问视频内容的URL或路径。 - duration:以时、分、秒格式标注的视频时长。 - page_dir:与视频关联的目录或分类信息。 - name:视频的描述性名称或标题。 ## 使用场景: 该数据集可应用于各类视频分类任务,包括但不限于内容分类、场景识别、活动识别以及目标检测。研究人员、开发者与从业者可借助该数据集,在不同领域与应用场景中训练并评估视频分类模型。 ## 下载方式 python from datasets import load_dataset, Dataset #加载数据集 dataset = load_dataset("Mouwiya/Video-10M") ## 联系方式 **Mouwiya S. A. Al-Qaisieh** mo3awiya@gmail.com
数据集概述:Video-10M
数据集描述
Video-10M 是一个包含1000万个视频的数据集,每个视频附带元数据,包括视频ID、内容URL、时长、页面目录和名称。该数据集涵盖了从自然景观、户外活动到烹饪艺术和城市景观等多种视频内容,适合用于各种视频分类任务。
数据集特征
- videoid: 视频的唯一标识符,数据类型为
int64。 - contentUrl: 访问视频内容的URL或路径,数据类型为
string。 - duration: 视频时长,以小时、分钟和秒表示,数据类型为
string。 - page_dir: 与视频关联的目录或类别,数据类型为
string。 - name: 视频的描述性名称或标题,数据类型为
string。
数据集分割信息
- 训练集: 包含10,727,607个样本,总大小为2993227031字节。
- 验证集: 包含5,000个样本,总大小为1394310字节。
数据集大小
- 下载大小: 1564635003字节
- 数据集总大小: 2994621341字节
任务类别
- 文本到视频
- 视频分类
大小类别
- 10M<n<100M