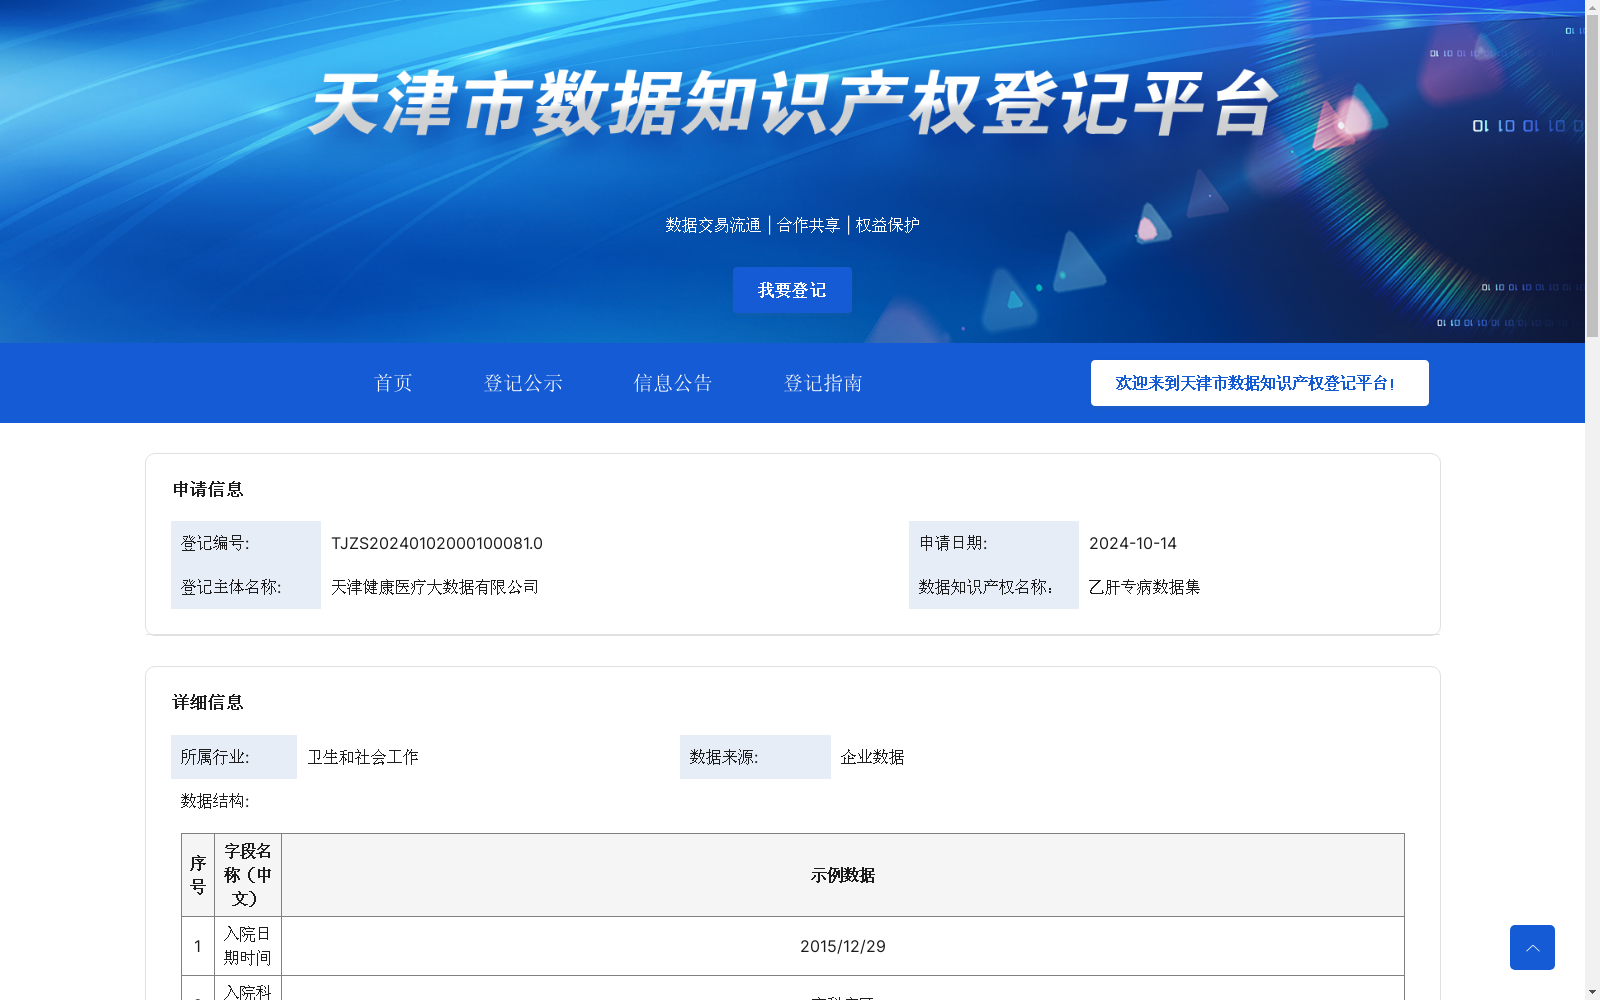
乙肝专病数据集
收藏资源简介:
多维诊疗数据构建患者主索引:将患者数据特征向量定义为患者性别、住址、家族遗传病、过敏原等信息,使用DBSCAN算法,基于特征向量的密度,将密度相近的数据点划为同一个簇,将患者数据点进行聚类,每个聚类可以视为一个患者群体,作为主索引的标识。 专病诊断名称分类模型:通过分析医学文献、临床数据和专家知识,建立一个诊断数据库。经过分词和打乱顺序的预处理后,使用 train_supervised 函数进行训练(迭代200次,学习率0.1,词N-grams长度为1,损失函数为"hs")。模型性能通过 classification_report 方法评估,表现良好。参数更新通过命令同步模型、标签和标签名,从而快速、准确地诊断专病类型。
Multi-dimensional clinical data for building Patient Master Index (PMI): Define the patient data feature vector as patient gender, residence, family genetic diseases, allergens and other relevant information. Use the DBSCAN algorithm to cluster patient data points based on the density of their feature vectors, grouping data points with similar densities into the same cluster. Each cluster can be regarded as a patient group, serving as the identifier for the Patient Master Index. Specialized disease diagnosis name classification model: Establish a diagnosis database by analyzing medical literature, clinical data and expert knowledge. After preprocessing including word segmentation and shuffling, use the "train_supervised" function for training (200 training iterations, learning rate of 0.1, word N-grams with length 1, loss function as "hs"). The model performance is evaluated using the "classification_report" method, showing good results. Parameters are updated by synchronizing the model, labels and label names via commands, enabling fast and accurate diagnosis of specialized disease types.