llm-jp/Jagle
收藏资源简介:
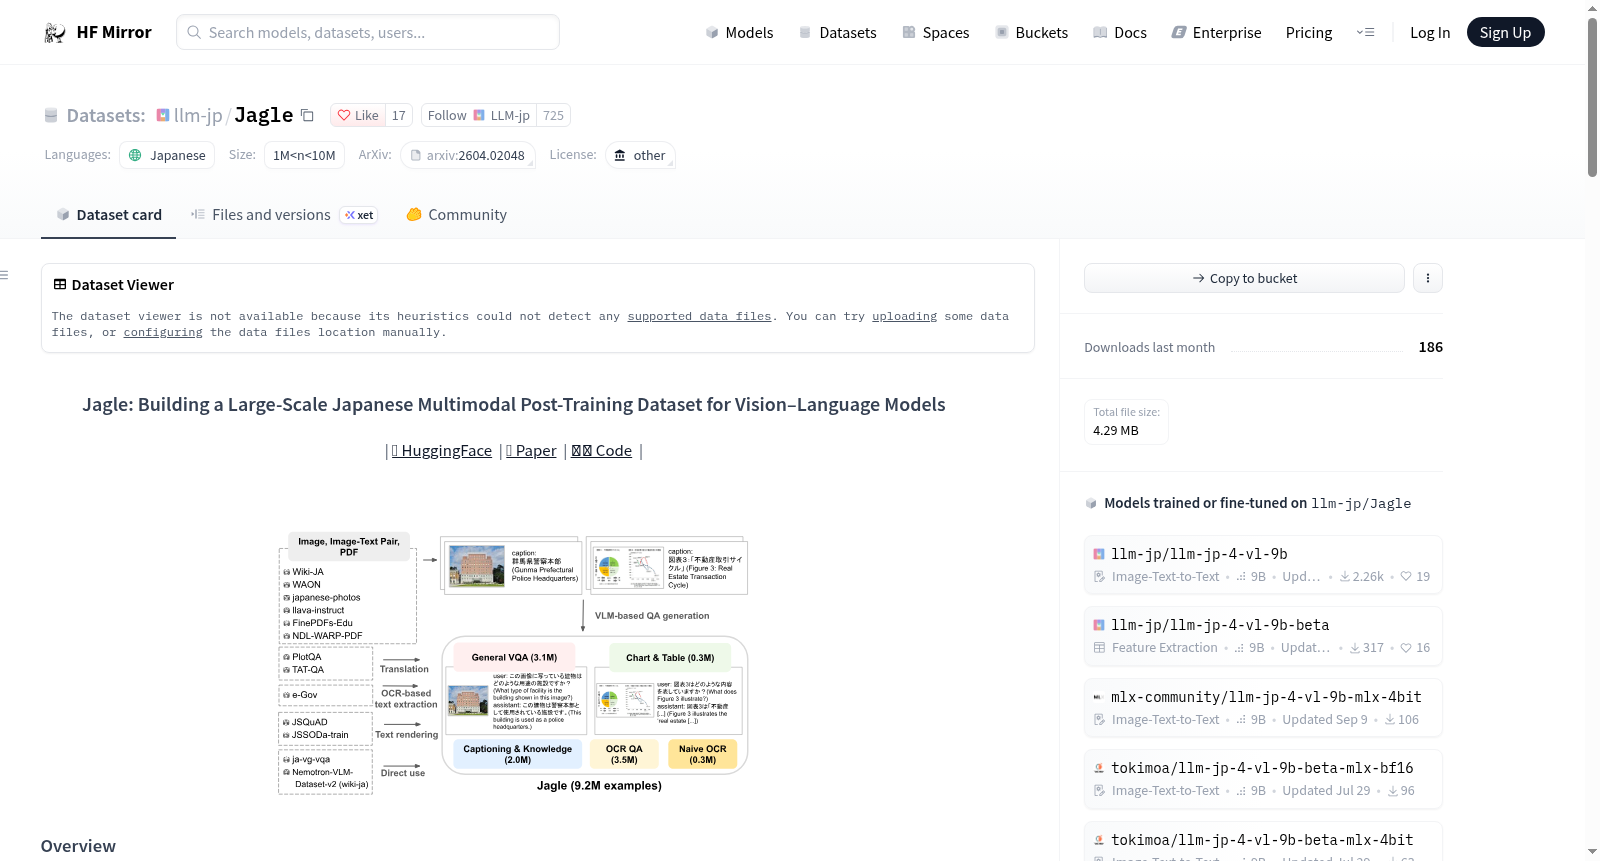
--- language: - ja size_categories: - 1M<n<10M license: other --- <div align="center" style="line-height: 1;"> <h1>Jagle: Building a Large-Scale Japanese Multimodal Post-Training Dataset for Vision–Language Models</h1> | <a href="https://huggingface.co/collections/llm-jp/jagle" target="_blank">🤗 HuggingFace</a> | <a href="https://arxiv.org/abs/2604.02048" target="_blank">📄 Paper</a> | <a href="https://github.com/llm-jp/llm-jp-4-vl" target="_blank">🧑💻 Code</a> | <br/> <img src="./jagle-construction-pipeline.svg" width="50%"/> </div> ## Overview Jagle is a large-scale Japanese multimodal post-training dataset, comprising approximately 9.2 million instances across diverse tasks. Jagle was used to train [LLM-jp-4-VL 9B beta](https://huggingface.co/llm-jp/llm-jp-4-vl-9b-beta). We construct Jagle by collecting a wide range of source data, including image–text pair datasets such as [WAON](https://huggingface.co/datasets/llm-jp/WAON) and PDF corpora like [FinePDFs-Edu](https://huggingface.co/datasets/HuggingFaceFW/finepdfs-edu), and then generating VQA data through various methods such as VLM-based QA generation and translation. Below are representative VQA samples from Jagle. <figure> <img src="./samples.svg" alt="" style="width: 80%"> <figcaption>Samples in Jagle.</figcaption> </figure> Below, we present the performance trajectory of the average score over Japanese and English tasks for a 2.2B model composed of Qwen3-1.7B and the SigLIP2-so400m-patch16-512 vision encoder, trained with Jagle. <figure> <img src="./training_curve_avg.svg" alt="" style="width: 80%"> <figcaption>Training curve on Avg, JA Avg, and EN Avg.</figcaption> </figure> The results show that using Jagle significantly improves performance on Japanese tasks. ## Category distribution Below, we present the category-wise distribution of Jagle. <figure> <img src="./piechart_4metrics.svg" alt="" style="width: 80%"> <figcaption>Category distribution of Jagle.</figcaption> </figure> ## Usage Due to copyright restrictions, the Jagle dataset is hosted only on a domestic server and is not included in this mirror. To use Jagle, first download the dataset from: 👉 https://gitlab.llm-jp.nii.ac.jp/datasets/jagle ```bash git clone https://gitlab.llm-jp.nii.ac.jp/datasets/jagle.git mv jagle/data . ``` After placing the dataset directory locally (e.g., in a folder named data/Jagle), you can load each dataset using the 🤗 datasets library: ```python from datasets import load_dataset ds = load_dataset("data/Jagle/japanese-photos-VQA", split="train") print(ds) ``` ## License Jagle is provided for use within the scope permitted under Article 30-4 of the Japanese Copyright Act. The copyrights and related rights to the original source datasets remain with their respective rights holders. | Source Dataset | License | |---|---| | [WAON](https://huggingface.co/datasets/llm-jp/waon) | Apache 2.0 (use limited to information analysis under Article 30-4 of the Japanese Copyright Act) | | [japanese-photos](https://huggingface.co/datasets/ThePioneer/japanese-photos) | CC0 1.0 | | [Wikipedia-ja](https://ja.wikipedia.org/) | CC BY-SA 4.0 | | [FinePDFs-Edu](https://huggingface.co/datasets/HuggingFaceFW/finepdfs-edu) | ODC-BY | | [PlotQA](https://github.com/NiteshMethani/PlotQA) | CC BY 4.0 | | [TAT-QA](https://nextplusplus.github.io/TAT-QA/) | CC BY 4.0 | | [NDL WARP PDF](https://gitlab.llm-jp.nii.ac.jp/datasets/ndl-warp-pdf) | (use limited to information analysis under Article 30-4 of the Japanese Copyright Act) | | [e-Gov](https://www.e-gov.go.jp/) | Government Standard Terms of Use 2.0 | | [JSSODa](https://huggingface.co/datasets/llm-jp/jssoda) | CC BY 4.0 | | [Nemotron-VLM-Dataset-v2](https://huggingface.co/datasets/nvidia/Nemotron-VLM-Dataset-v2) | CC BY 4.0 | ### Models Used for QA Generation and Preprocessing | Model | License | |---|---| | [Qwen3-VL-235B-A22B-Instruct](https://huggingface.co/Qwen/Qwen3-VL-235B-A22B-Instruct) | Apache 2.0 | | [llm-jp-3-13b-instruct](https://huggingface.co/llm-jp/llm-jp-3-13b-instruct) | Apache 2.0 | | [PaddleOCR-VL](https://github.com/PaddlePaddle/PaddleOCR) | Apache 2.0 | ## Citation ```bibtex @misc{sugiura2026jaglebuildinglargescalejapanese, title={Jagle: Building a Large-Scale Japanese Multimodal Post-Training Dataset for Vision-Language Models}, author={Issa Sugiura and Keito Sasagawa and Keisuke Nakao and Koki Maeda and Ziqi Yin and Zhishen Yang and Shuhei Kurita and Yusuke Oda and Ryoko Tokuhisa and Daisuke Kawahara and Naoaki Okazaki}, year={2026}, eprint={2604.02048}, archivePrefix={arXiv}, primaryClass={cs.CV}, url={https://arxiv.org/abs/2604.02048}, } ```
Jagle is a large-scale Japanese multimodal post-training dataset, comprising approximately 9.2 million instances across diverse tasks. Jagle was used to train LLM-jp-4-VL 9B beta. It is constructed by collecting a wide range of source data, including image–text pair datasets such as WAON and PDF corpora like FinePDFs-Edu, and then generating VQA data through various methods such as VLM-based QA generation and translation.