algerian-darja-corpus
收藏资源简介:
Algerian Darja Corpus 是一个高质量的数据集,包含阿尔及利亚达里贾语(阿尔及利亚阿拉伯语方言)的对话转录文本。该语料库收录了自然、真实的讨论、播客和对话,代表了当今达里贾语的口语使用方式。其突出特点是阿尔及利亚阿拉伯语、法语和英语之间存在广泛的语码转换现象,并且文本同时使用阿拉伯字母和拉丁字母(Arabizi/法式阿尔及利亚语)书写。数据集共包含1789个转录文档(对话片段),总计6,524,233个单词和36,367,373个字符,以JSON Lines格式存储。每个数据实例包含三个字段:text(对话片段的完整转录文本)、char_count(转录文本的字符总数)和word_count(转录文本的单词总数)。阿尔及利亚达里贾语是一种口语方言,没有单一的标准化书写系统。本数据集反映了真实世界的正字法选择:包括使用阿拉伯字母按发音书写达里贾词语,以及使用拉丁字母(常融合法语拼写约定或英语借词)书写的Arabizi/法式阿尔及利亚语文本。语码转换频繁,常在同一个句子或话轮中交替使用阿尔及利亚达里贾语、法语和英语。数据来源于多个YouTube播客和谈话节目频道,以及Hugging Face上的相关音频收集数据集。该数据集适用于文本生成等自然语言处理任务,特别是针对方言处理、语码转换研究和多语言模型训练。数据集采用知识共享署名4.0国际许可证(CC BY 4.0)发布。
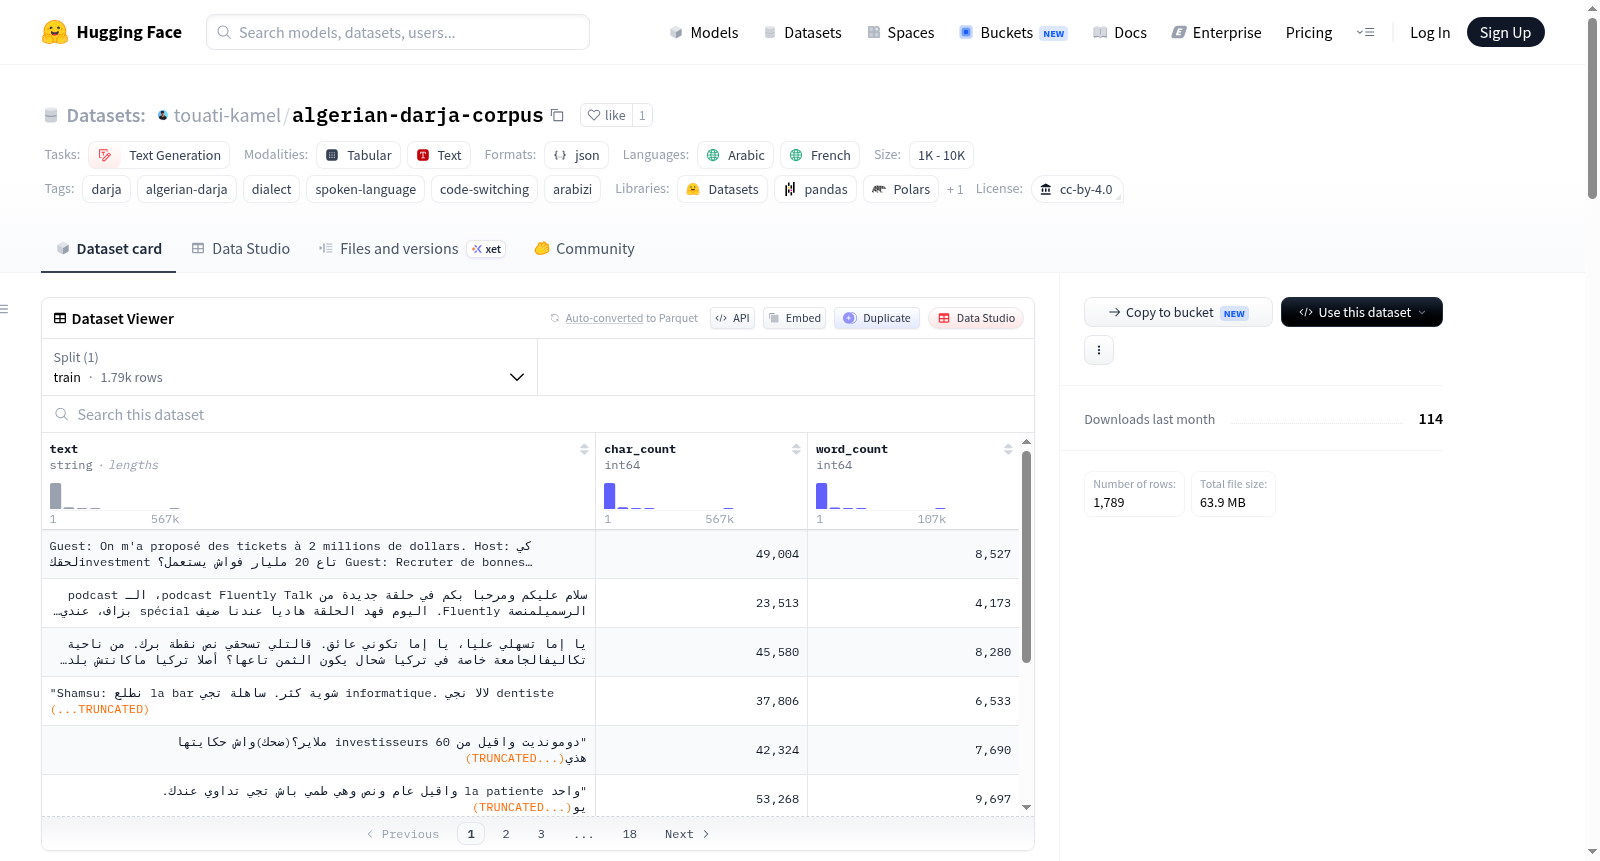
The Algerian Darja Corpus is a high-quality dataset containing transcribed dialogues in Algerian Darja (an Algerian Arabic dialect). The corpus includes natural and authentic discussions, podcasts, and conversations, representing the contemporary spoken usage of Darja. Its notable features include extensive code-switching between Algerian Arabic, French, and English, with texts written in both Arabic script and Latin script (Arabizi/Franco-Algerian). The dataset comprises 1,789 transcribed documents (dialogue segments), totaling 6,524,233 words and 36,367,373 characters, stored in JSON Lines format. Each data instance includes three fields: text (the full transcribed text of the dialogue segment), char_count (total number of characters in the transcribed text), and word_count (total number of words in the transcribed text). Algerian Darja is a spoken dialect without a single standardized writing system. This dataset reflects real-world orthographic choices: including writing Darja words phonetically using Arabic script, and Arabizi/Franco-Algerian texts written in Latin script (often incorporating French spelling conventions or English loanwords). Code-switching is frequent, often alternating between Algerian Darja, French, and English within the same sentence or turn. The data is sourced from multiple YouTube podcasts and talk show channels, as well as related audio collection datasets on Hugging Face. This dataset is suitable for natural language processing tasks such as text generation, particularly for dialect processing, code-switching research, and multilingual model training. The dataset is released under the Creative Commons Attribution 4.0 International License (CC BY 4.0).
数据集概述
Algerian Darja Corpus 是一个高质量的对话转录数据集,专注于阿尔及利亚达里贾语(阿尔及利亚阿拉伯方言)。该语料库包含真实世界的自然对话、播客和讨论,反映了达里贾语当下的实际使用方式,并突出显示了阿尔及利亚阿拉伯语、法语和英语之间的大量语码转换,文本同时使用阿拉伯字母和拉丁字母(Arabizi/Franco-Algerian)书写。
数据集规模
- 文档数(转录文本): 1789
- 总词数: 6,524,233
- 总字符数: 36,367,373
- 数据格式: JSON Lines(
.jsonl)
数据结构
数据字段
每条JSON对象包含以下字段:
text(字符串):对话片段的完整转录文本。char_count(整数):转录文本的总字符数。word_count(整数):转录文本的总词数。
数据实例示例
json { "text": "Host: سلام عليكم ومرحباً بكم في حلقة جديدة من podcast FluentlyTalk... Guest: لاباس، والله غير الحمد لله...", "char_count": 23513, "word_count": 4173 }
语言与书写系统
- 阿拉伯字母: 使用传统阿拉伯字母以音标方式书写达里贾语。
- 拉丁字母(Arabizi / Franco-Algerian): 使用拉丁字母书写,常融合法语拼写惯例或英语借词。
- 语码转换: 在同一句子或话轮中频繁交替使用阿尔及利亚达里贾语、法语和英语。
数据来源
转录文本收集自以下YouTube频道:
- بودكاست المفيد El Moufid Podcast
- Keepodcast
- BelkadiManel
- takicharni
- ilyesderradji
- MohamedDjamelTaleb
- ramziZRT
- Khoubai
- Intaj
- Omar Rahmoun
- Mouslem khirouni
- Fluently
- Zaki Agha CasTea
- Anis Hamidi
- BrainerX
- Raouf Talks
- Alias Djamel
- Entrepreneur podcast - بودكاست المقاول
- NOEST Express
- Dar El Mic – دار الميك
- Flown marketing
- Kings Podcast
以及来自Hugging Face数据集:
- oddadmix/arabic-audio-collection-algerian-kahwa-postcast
- oddadmix/arabic-audio-collection-algerian-loubna-stories
- oddadmix/arabic-audio-collection-algerian-rawi
许可协议
该数据集采用 Creative Commons Attribution 4.0 International (CC BY 4.0) 许可协议分发。
任务类别
- 文本生成
语言
- 阿拉伯语
- 法语
标签
- darja
- algerian-darja
- dialect
- spoken-language
- code-switching
- arabizi
使用方式
可通过Hugging Face datasets 库直接加载:
python from datasets import load_dataset
dataset = load_dataset("touati-kamel/algerian-darja-corpus") print(dataset[train][0])