lolaby-traces
收藏资源简介:
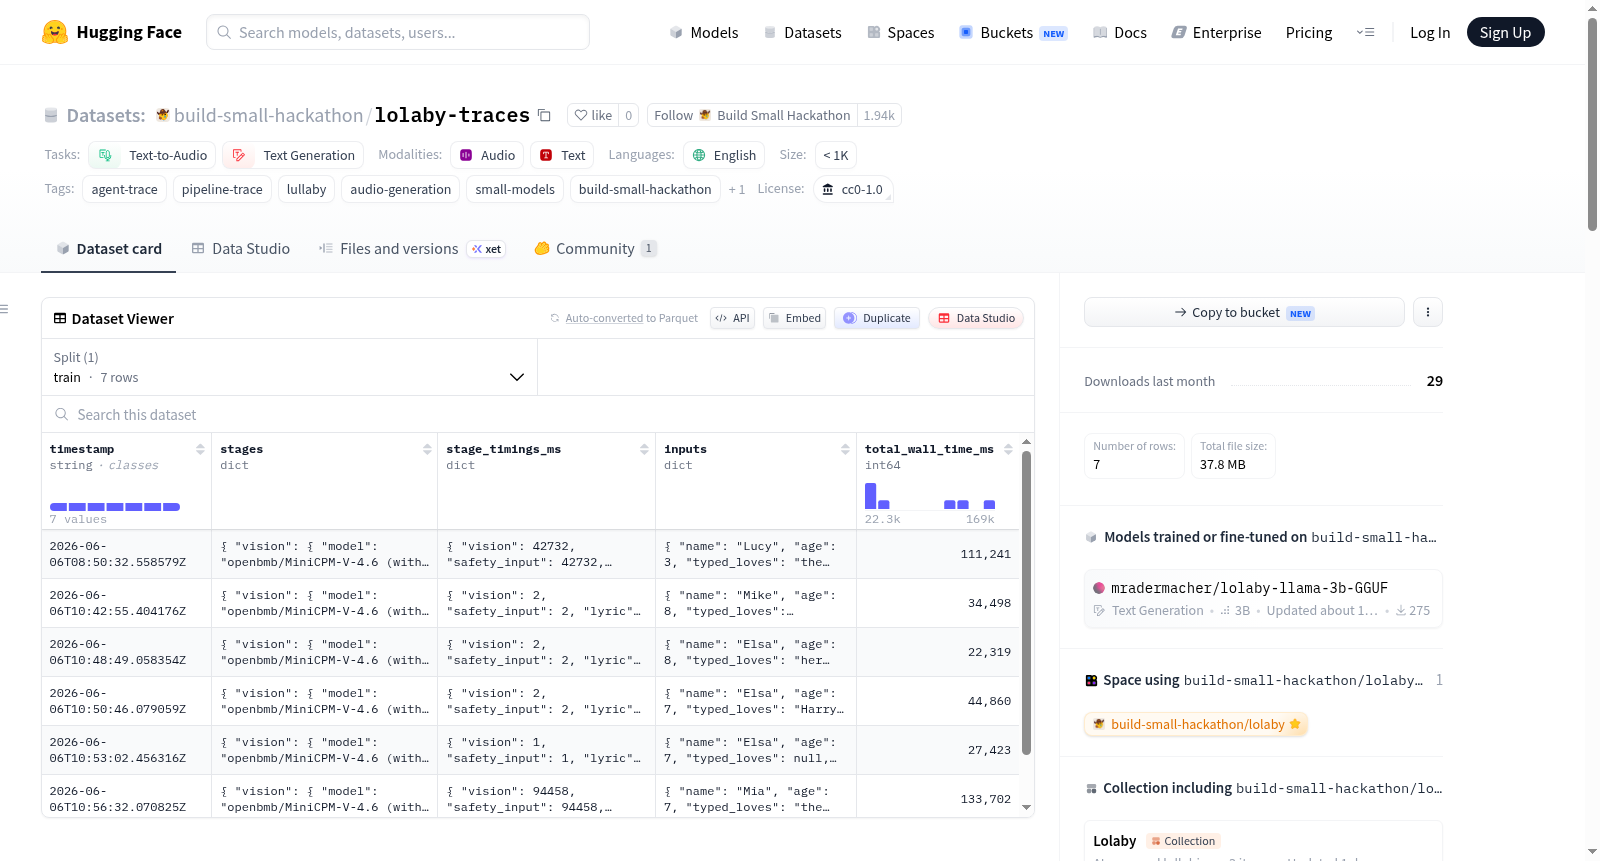
Lolaby生成追踪数据集是一个从Lolaby应用中收集的端到端AI生成过程的完整记录集合,Lolaby是一个为Build Small Hackathon 2026(Backyard AI赛道)开发的AI驱动摇篮曲生成器。每个记录代表一次完整的生成过程,包含用户提供的所有输入(如姓名、恐惧、情绪、乐器等)、运行的每个模型(包括MiniCPM-V 4.6模型用于视觉解释、微调的Llama 3.2 3B模型用于生成歌词、和弦和节奏、Kokoro TTS和自定义DSP合成器用于音频合成)、每个阶段的提示和原始输出、所有时间测量以及最终生成的音频文件。数据集以子文件夹形式组织,每个文件夹包含trace.json(完整管道日志)、input_drawing.png(用户绘图,如果适用)和output_lullaby.wav(生成的音频文件,WAV格式,44.1 kHz,单声道)。数据集覆盖两种运行时路径:视觉路径(用户提供绘图,由模型解释后结合文本输入)和纯文本路径(仅基于文本输入)。记录是真实运行的见证,混合了确定性和随机性阶段,包含种子和参数以支持重放。数据以CC0许可证发布,允许研究、重放或重新混合生成管道,适用于文本到音频生成、文本生成、代理追踪分析和管道优化研究等任务。所有数据在本地生成,使用合成测试名称和开发者绘图,不包含真实儿童数据。
The Lolaby generation trace dataset contains complete end-to-end generation traces collected from the Lolaby app, an AI-powered lullaby generator built for the Build Small Hackathon 2026 (Backyard AI track). Each trace is a witness to a full generation, containing all user-provided inputs, every model run, every prompt and raw output, all timing measurements, and the final generated audio. The dataset is released under the CC0 license, allowing anyone to study, replay, or remix the entire generation pipeline. Each subfolder in the dataset represents a complete generation process and includes the following files: trace.json (full pipeline log recording user inputs, prompts and outputs for each stage, stage timings, parsed lyric structure, and audio rendering parameters), input_drawing.png (the drawing provided by the user to Lola, omitted if the user generated with text-only input), output_lullaby.wav (the audio file generated by Lola, in WAV format, 44.1 kHz, mono). The dataset covers two runtime paths of the Lolaby app: the vision path (where the user draws on a canvas or uploads a photo, interpreted by the MiniCPM-V model, with results fed into the lyric model alongside any text input) and the text-only path (no drawing provided, lyric model generates from text input only). Each path has representative trace folders, with the vision.source field in trace.json recording the type of path run. The generation pipeline includes stages such as user drawing interpretation via MiniCPM-V 4.6 model, combined with user-provided name, fear, mood, instrument, etc., input into a fine-tuned Llama 3.2 3B model to generate lyrics, chords, and rhythm, and finally synthesized into the final lullaby audio via Kokoro TTS and a custom DSP synthesizer. The traces in the dataset are witnesses to real runs, not recipes. The pipeline mixes deterministic and stochastic stages: deterministic stages (visual reasoning, DSP synthesizer rendering) are fully reproducible with the same inputs; stochastic stages (lyric model running at temperature=0.85, sampling in Kokoro TTS) produce similar but not identical outputs on reruns. Traces include seeds and parameters used, allowing exact replay of deterministic stages and spiritual comparison of stochastic ones. All traces were generated on the developers local laptop, with no cloud API calls used. The dataset uses synthetic test names and the developers own test drawings, containing no real child data. It is suitable for tasks such as text-to-audio generation, text generation, agent trace analysis, and pipeline optimization research.
数据集概述:Lolaby — Generation Traces
数据集名称:Lolaby — Generation Traces
许可证:CC0 1.0 Universal(无版权保留)
数据集大小:少于1K条记录
任务类别:文本转音频、文本生成
语言:英语
主要标签:agent-trace, pipeline-trace, lullaby, audio-generation, small-models, build-small-hackathon, backyard-ai
数据集内容
数据集包含来自 Lolaby(AI驱动的摇篮曲生成器)的管道追踪记录。每条追踪记录是一次完整端到端生成过程的全程记录,包括:
- 用户输入
- 运行的所有模型
- 每个阶段的提示词和原始输出
- 每个阶段的计时数据
- 最终生成的音频文件
每个子文件夹代表一次生成,包含以下文件:
trace.json:完整的管道日志,包含用户输入、每个阶段的提示词和输出、阶段计时、解析的歌词结构(和弦、节拍、换行)以及音频渲染参数。input_drawing.png:用户提供的绘图(仅当用户通过绘图输入时存在;若仅通过文字输入则无此文件)。output_lullaby.wav:Lola生成的音频文件(WAV格式,44.1 kHz,单声道)。
覆盖场景
数据集涵盖Lolaby的两种运行路径,每种路径均有代表性追踪记录:
- 视觉路径(Vision path):用户在画布上绘图或上传照片,MiniCPM-V模型解读图像,结果与用户输入的“所爱之物”文本共同输入歌词模型。
- 纯文本路径(Typed-only path):无绘图输入,歌词模型仅根据用户输入的“所爱之物”文本生成歌词。
在trace.json中,通过vision.source字段记录运行路径(值为vision或typed_only)。
管道流程概览
绘图 ─▶ MiniCPM-V 4.6 ─▶ "Lola看到的内容" │ + 姓名、恐惧、情绪、乐器 ▼ Fine-tuned Llama 3.2 3B (GGUF, llama.cpp) │ 解析后的歌词 + 和弦 + 节奏 │ ┌─────────────────┴─────────────────┐ ▼ ▼ Kokoro TTS DSP合成器(自定义) └─────────────────┬─────────────────┘ ▼ output_lullaby.wav
可复现性说明
每条追踪记录是真实运行的一次见证,而非可复现的食谱。管道包含确定性阶段和随机性阶段:
- 确定性阶段:视觉推理(
do_sample=False)、基于解析歌词的DSP合成渲染。给定相同输入可完全复现。 - 随机性阶段:歌词模型以
temperature=0.85运行,Kokoro TTS具有自身采样机制。重新运行时输出相似但不完全相同。
追踪记录中保存了使用的随机种子和参数,可以精确复现确定性阶段,并在精神层面上比较随机性阶段。
相关资源
- 应用:https://huggingface.co/spaces/build-small-hackathon/lolaby(实时Gradio空间)
- 歌词模型:https://huggingface.co/build-small-hackathon/lolaby-llama-3b(Fine-tuned Llama 3.2 3B)
- 视觉模型:https://huggingface.co/openbmb/MiniCPM-V-4_6(解读绘图)
- 语音模型:https://huggingface.co/hexgrad/Kokoro-82M(朗读歌词)
来源与隐私
- 来源:这些追踪记录在开发者本地笔记本电脑上生成,所有模型均在设备本地运行,未调用任何云API。
- 隐私:所有追踪记录使用合成测试名称和开发者自己的测试绘图,不包含任何真实儿童数据。若需从真实用户处收集追踪记录,请先清除可识别信息。
许可证
CC0 1.0 Universal:无版权保留,可用于研究、教学、比较或其他任何用途,无需署名。但追踪记录中引用的模型和代码有其自身许可证,请参见相关资源部分。