sarasarahuss/ALIF_Urdu_Corpus_AUC
收藏资源简介:
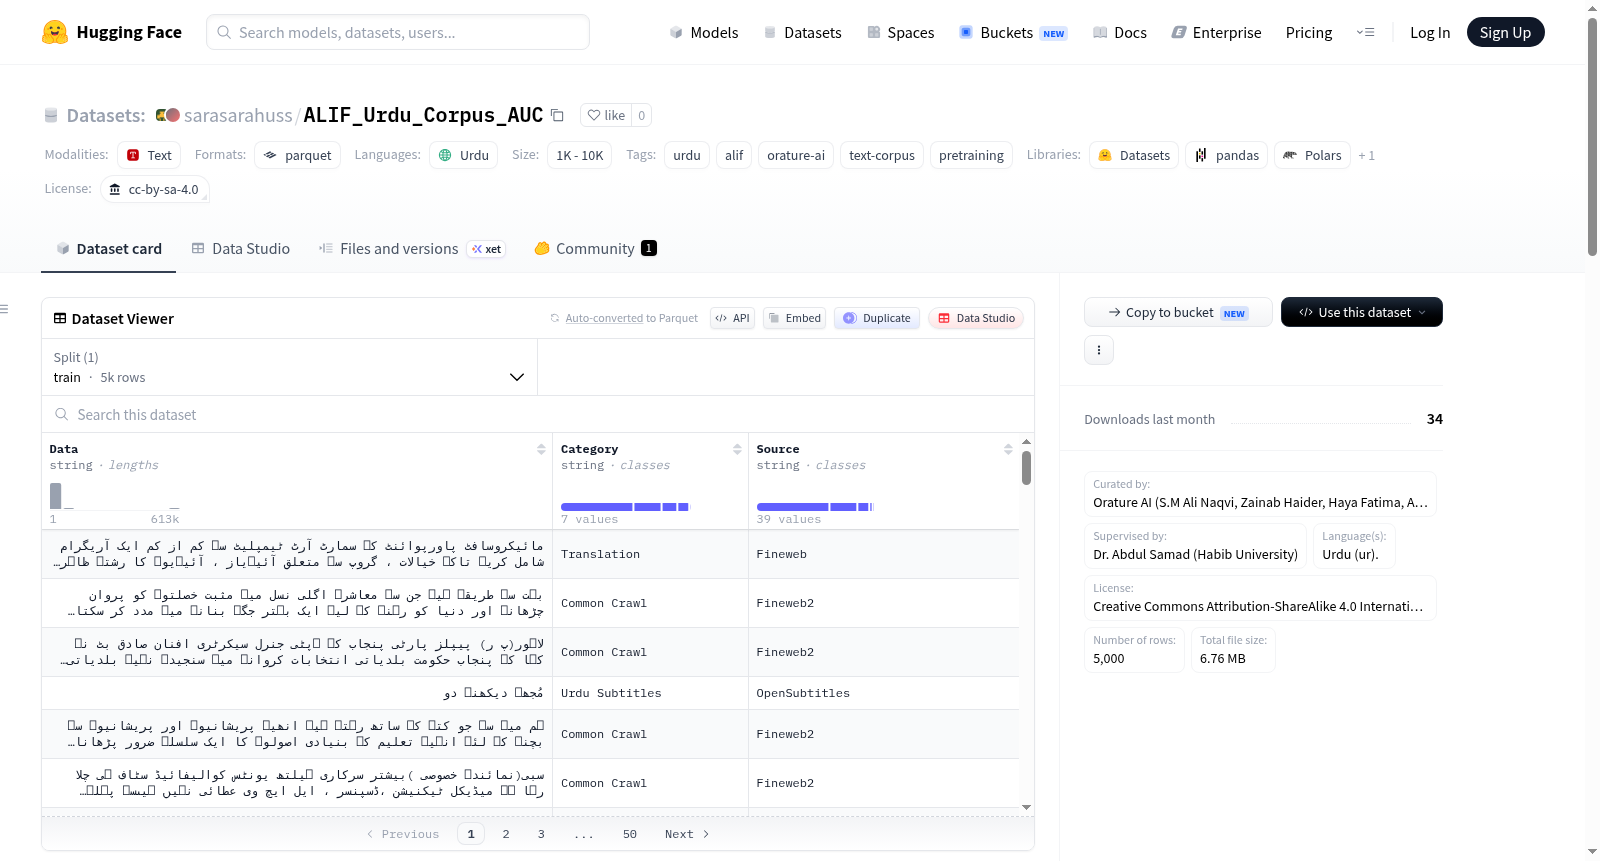
ALIF_Urdu_Corpus数据集是Orature AI的ALIF项目的一部分,专为乌尔都语语言模型的预训练而设计。该数据集是完整33GB数据集的预览版,包含5000个文本条目,总大小约为13.7MB。数据来源多样,包括Common Crawl Dumps、翻译数据、新闻网站、现有数据集、书籍和博客等。数据集经过严格的预处理,包括清理、编码规范化、语言过滤、去重和格式化。主要用途包括预训练语言模型、指令微调、NLP研究和基准测试。
The ALIF_Urdu_Corpus dataset is part of the ALIF project by Orature AI, curated for pretraining Urdu language models. It serves as a preview to the entire 33GB dataset, containing 5000 text entries with a total size of about 13.7MB. The data was collected from diverse sources including Common Crawl Dumps, translated data, news websites, existing datasets, books, and blogs. The dataset underwent rigorous preprocessing steps such as cleaning, encoding normalization, language filtering, deduplication, and formatting. Its primary intended uses include pretraining language models, instruction fine-tuning, NLP research, and benchmarking.