marketeam/FineWeb-Marketing
收藏资源简介:
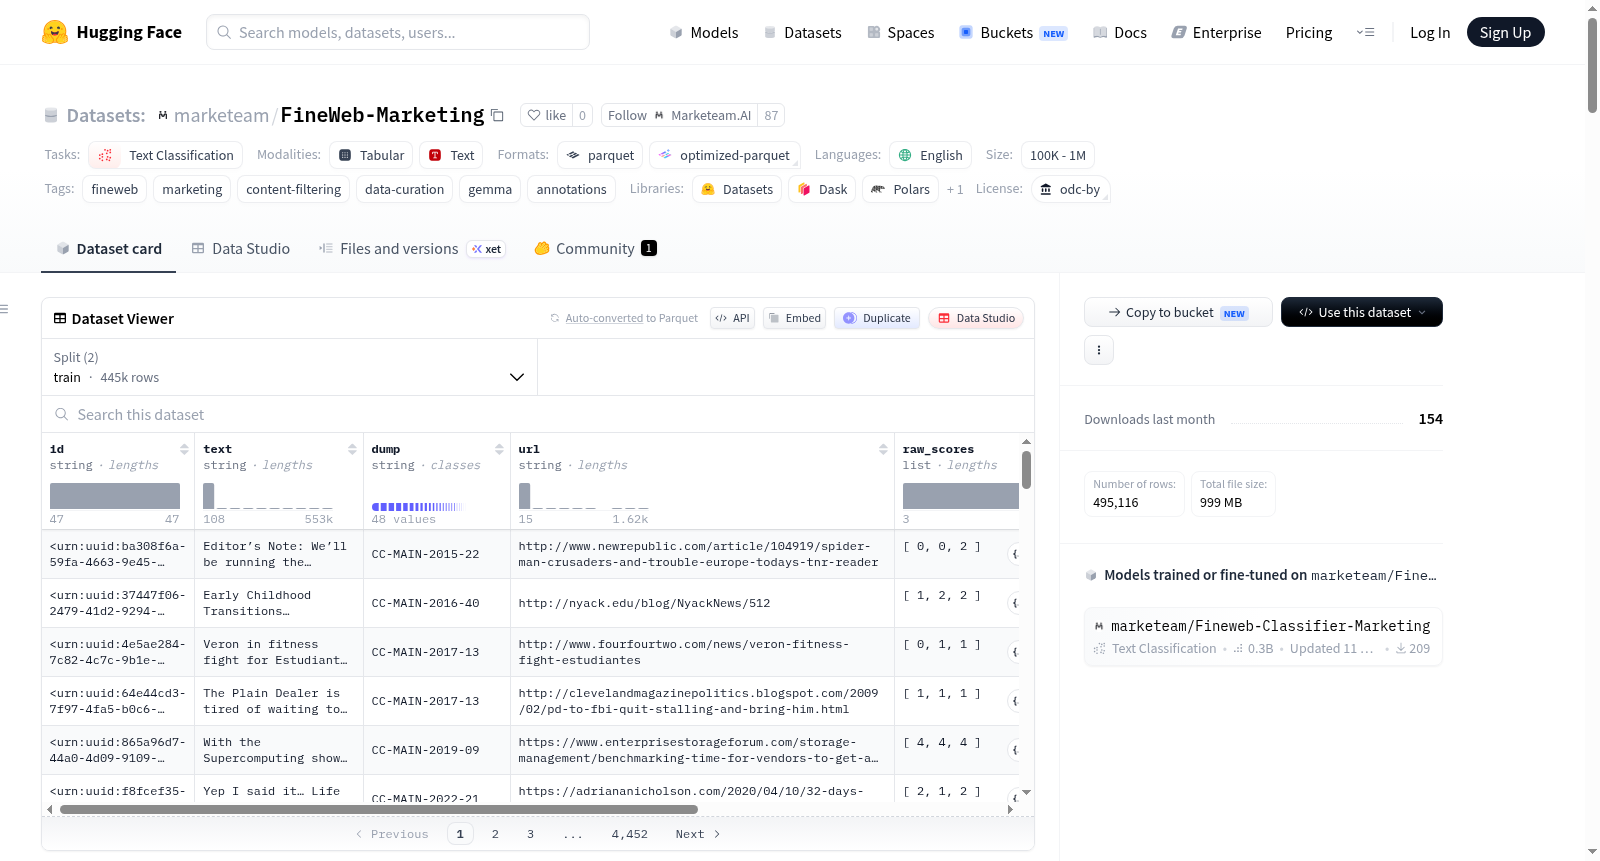
该数据集名为FineWeb-Marketing Annotations,包含495,116个从FineWeb采样的文档,每个文档由Gemma-3-27B-it模型根据营销内容质量在0-5分范围内进行评分。这些注释数据用于支持marketeam/Fineweb-Classifier-Marketing分类器的训练。每个文档通过三次独立提示Gemma模型获得原始评分,并聚合为最终分数:如果三次样本中至少两次一致,则采用多数投票结果;否则取三次评分的平均值。数据集分为训练集(445,128行)和验证集(49,988行),与分类器的训练和评估分割完全匹配。数据字段包括:文档ID、完整文本、来源Common Crawl转储、URL、三次原始评分列表、聚合分数、整数化分数(四舍五入并裁剪到0-5)以及数据分割标识。注释方法基于FineWeb-Edu的流程,并采用JQL研究验证的改进方法,包括从FineWeb的sample-350BT子集中采样500,000个文档,使用Gemma-3-27B-it作为注释模型(因其在人类基准测试中表现出最高的Spearman相关性),通过特定提示要求模型基于五个标准(相关性、专业性、专业性、专家级和卓越性)进行推理并给出评分,最后过滤掉少于两次成功解析评分的文档。数据集适用于训练营销质量分类器、预训练语料库筛选研究以及LLM作为评判者的研究(如样本间一致性分析)。文本来源为FineWeb数据集,采用ODC-By 1.0许可证;注释模型为Gemma-3-27B-it。局限性包括:评分基于Gemma模型的主观判断、仅限英语内容、分数分布左偏(高分文档较少)以及使用单一注释模型。
Each row is one document sampled from FineWeb, scored on a 0–5 marketing-quality scale by prompting Gemma-3-27B-it three independent times and aggregating the results. This is the annotation data behind marketeam/Fineweb-Classifier-Marketing. The dataset ships as two splits, matching exactly what marketeam/Fineweb-Classifier-Marketing was trained and evaluated on: train (445,128 rows) and validation (49,988 rows). Annotation methodology mirrors the FineWeb-Edu process, adapted to the marketing domain with refinements validated by JQL research, including sampling from FineWebs sample-350BT subset, using Gemma-3-27B-it as the annotator model, evaluating documents with a G-Eval-style prompt based on five rubric criteria, and filtering documents with fewer than two successfully parsed scores. Applications include training quality classifiers, pretraining corpus curation research, and LLM-as-judge studies. Source text is from FineWeb under ODC-By 1.0 license; annotation model is Gemma-3-27B-it. Limitations: scores reflect Gemmas judgment, English-only content, left-skewed distribution, and single-annotator-model labels.