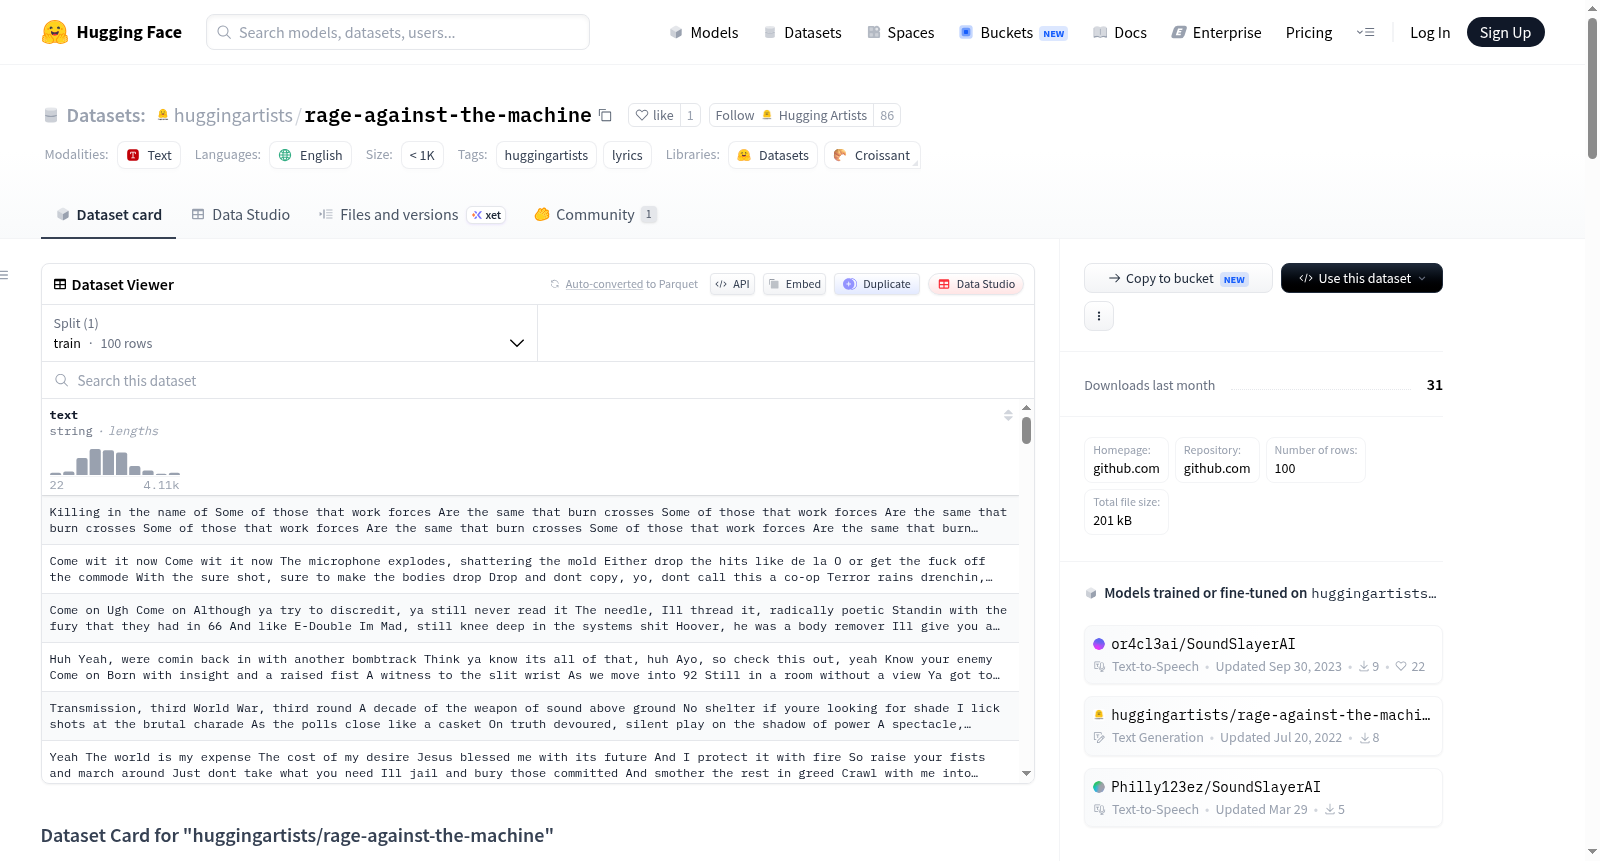
huggingartists/rage-against-the-machine
收藏资源简介:
--- language: - en tags: - huggingartists - lyrics --- # Dataset Card for "huggingartists/rage-against-the-machine" ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [How to use](#how-to-use) - [Dataset Structure](#dataset-structure) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [About](#about) ## Dataset Description - **Homepage:** [https://github.com/AlekseyKorshuk/huggingartists](https://github.com/AlekseyKorshuk/huggingartists) - **Repository:** [https://github.com/AlekseyKorshuk/huggingartists](https://github.com/AlekseyKorshuk/huggingartists) - **Paper:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Point of Contact:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Size of the generated dataset:** 0.216212 MB <div class="inline-flex flex-col" style="line-height: 1.5;"> <div class="flex"> <div style="display:DISPLAY_1; margin-left: auto; margin-right: auto; width: 92px; height:92px; border-radius: 50%; background-size: cover; background-image: url('https://images.genius.com/2158957823960c84c7890b8fa5e6d479.1000x1000x1.jpg')"> </div> </div> <a href="https://huggingface.co/huggingartists/rage-against-the-machine"> <div style="text-align: center; margin-top: 3px; font-size: 16px; font-weight: 800">🤖 HuggingArtists Model 🤖</div> </a> <div style="text-align: center; font-size: 16px; font-weight: 800">Rage Against the Machine</div> <a href="https://genius.com/artists/rage-against-the-machine"> <div style="text-align: center; font-size: 14px;">@rage-against-the-machine</div> </a> </div> ### Dataset Summary The Lyrics dataset parsed from Genius. This dataset is designed to generate lyrics with HuggingArtists. Model is available [here](https://huggingface.co/huggingartists/rage-against-the-machine). ### Supported Tasks and Leaderboards [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Languages en ## How to use How to load this dataset directly with the datasets library: ```python from datasets import load_dataset dataset = load_dataset("huggingartists/rage-against-the-machine") ``` ## Dataset Structure An example of 'train' looks as follows. ``` This example was too long and was cropped: { "text": "Look, I was gonna go easy on you\nNot to hurt your feelings\nBut I'm only going to get this one chance\nSomething's wrong, I can feel it..." } ``` ### Data Fields The data fields are the same among all splits. - `text`: a `string` feature. ### Data Splits | train |validation|test| |------:|---------:|---:| |100| -| -| 'Train' can be easily divided into 'train' & 'validation' & 'test' with few lines of code: ```python from datasets import load_dataset, Dataset, DatasetDict import numpy as np datasets = load_dataset("huggingartists/rage-against-the-machine") train_percentage = 0.9 validation_percentage = 0.07 test_percentage = 0.03 train, validation, test = np.split(datasets['train']['text'], [int(len(datasets['train']['text'])*train_percentage), int(len(datasets['train']['text'])*(train_percentage + validation_percentage))]) datasets = DatasetDict( { 'train': Dataset.from_dict({'text': list(train)}), 'validation': Dataset.from_dict({'text': list(validation)}), 'test': Dataset.from_dict({'text': list(test)}) } ) ``` ## Dataset Creation ### Curation Rationale [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Source Data #### Initial Data Collection and Normalization [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the source language producers? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Annotations #### Annotation process [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the annotators? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Personal and Sensitive Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Discussion of Biases [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Other Known Limitations [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Additional Information ### Dataset Curators [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Licensing Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Citation Information ``` @InProceedings{huggingartists, author={Aleksey Korshuk} year=2021 } ``` ## About *Built by Aleksey Korshuk* [](https://github.com/AlekseyKorshuk) [](https://twitter.com/intent/follow?screen_name=alekseykorshuk) [](https://t.me/joinchat/_CQ04KjcJ-4yZTky) For more details, visit the project repository. [](https://github.com/AlekseyKorshuk/huggingartists)
数据集卡片 for "huggingartists/rage-against-the-machine"
数据集描述
- 生成的数据集大小: 0.216212 MB
数据集概述
该数据集是从Genius解析的歌词数据集,旨在使用HuggingArtists生成歌词。模型可在此处获取:HuggingArtists Model。
支持的任务和排行榜
语言
en
如何使用
使用datasets库直接加载此数据集的方法:
python from datasets import load_dataset
dataset = load_dataset("huggingartists/rage-against-the-machine")
数据集结构
train的示例如下:
json { "text": "Look, I was gonna go easy on you Not to hurt your feelings But Im only going to get this one chance Somethings wrong, I can feel it..." }
数据字段
所有分区的数据字段相同:
text: 一个string特征。
数据分割
| train | validation | test |
|---|---|---|
| 100 | - | - |
Train可以通过几行代码轻松分割为train、validation和test:
python from datasets import load_dataset, Dataset, DatasetDict import numpy as np
datasets = load_dataset("huggingartists/rage-against-the-machine")
train_percentage = 0.9 validation_percentage = 0.07 test_percentage = 0.03
train, validation, test = np.split(datasets[train][text], [int(len(datasets[train][text])train_percentage), int(len(datasets[train][text])(train_percentage + validation_percentage))])
datasets = DatasetDict( { train: Dataset.from_dict({text: list(train)}), validation: Dataset.from_dict({text: list(validation)}), test: Dataset.from_dict({text: list(test)}) } )
数据集创建
策划理由
源数据
初始数据收集和规范化
源语言生产者是谁?
注释
注释过程
注释者是谁?
个人和敏感信息
使用数据的注意事项
数据集的社会影响
偏见的讨论
其他已知限制
附加信息
数据集策展人
许可信息
引用信息
@InProceedings{huggingartists, author={Aleksey Korshuk}, year=2021 }