A Comprehensive Dataset for Human vs.AI Generated Text Detection
收藏资源简介:
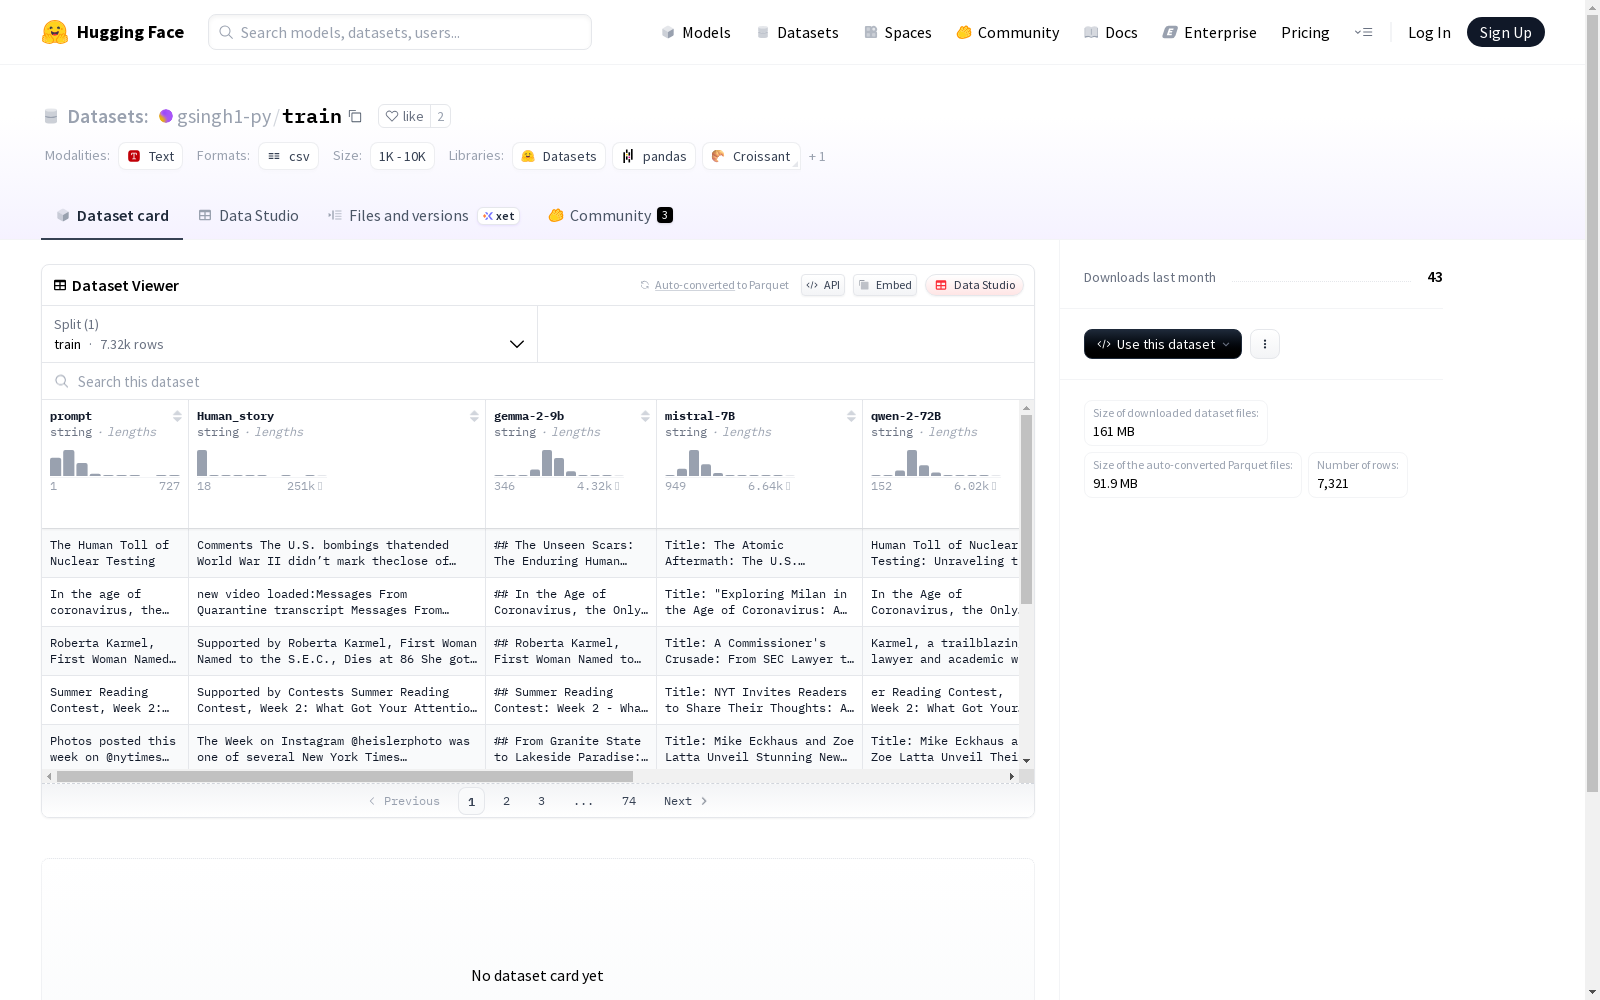
该数据集由来自《纽约时报》的真实新闻文章和由多个最先进的语言模型生成的合成版本组成,旨在推动AI生成文本的检测和归因方法的发展。数据集包含超过5.8万个文本样本,涵盖了真实的新闻文章摘要和由Gemima-2-9b、Mistral-7B、Qwen-2-72B、LLaMA-8B、Yi-Large和GPT-4-o等模型生成的合成文本。数据集的构建过程包括从《纽约时报》提取文章摘要作为提示,并使用这些提示生成AI文本输出。数据集可用于开发、训练和评估AI内容检测系统,并支持多项研究,包括开发鲁棒的分类器、特征工程、跨模型泛化、基准测试和模型评估、虚假信息和不真实性的影响以及混合内容推荐系统。
This dataset comprises real news articles from The New York Times and their synthetic variants generated by multiple state-of-the-art language models, with the goal of advancing the development of AI-generated text detection and attribution methodologies. It contains over 58,000 text samples, including authentic news article abstracts and synthetic text produced by models such as Gemima-2-9b, Mistral-7B, Qwen-2-72B, LLaMA-8B, Yi-Large, and GPT-4-o. The dataset construction process entails extracting news article abstracts from The New York Times as prompts, and utilizing these prompts to generate AI text outputs. This dataset can be employed to develop, train, and evaluate AI content detection systems, and supports a broad spectrum of research initiatives, including the development of robust classifiers, feature engineering, cross-model generalization, benchmarking and model evaluation, the impacts of disinformation and inauthenticity, as well as hybrid content recommendation systems.