waxal-ethiopian-asr-v5
收藏资源简介:
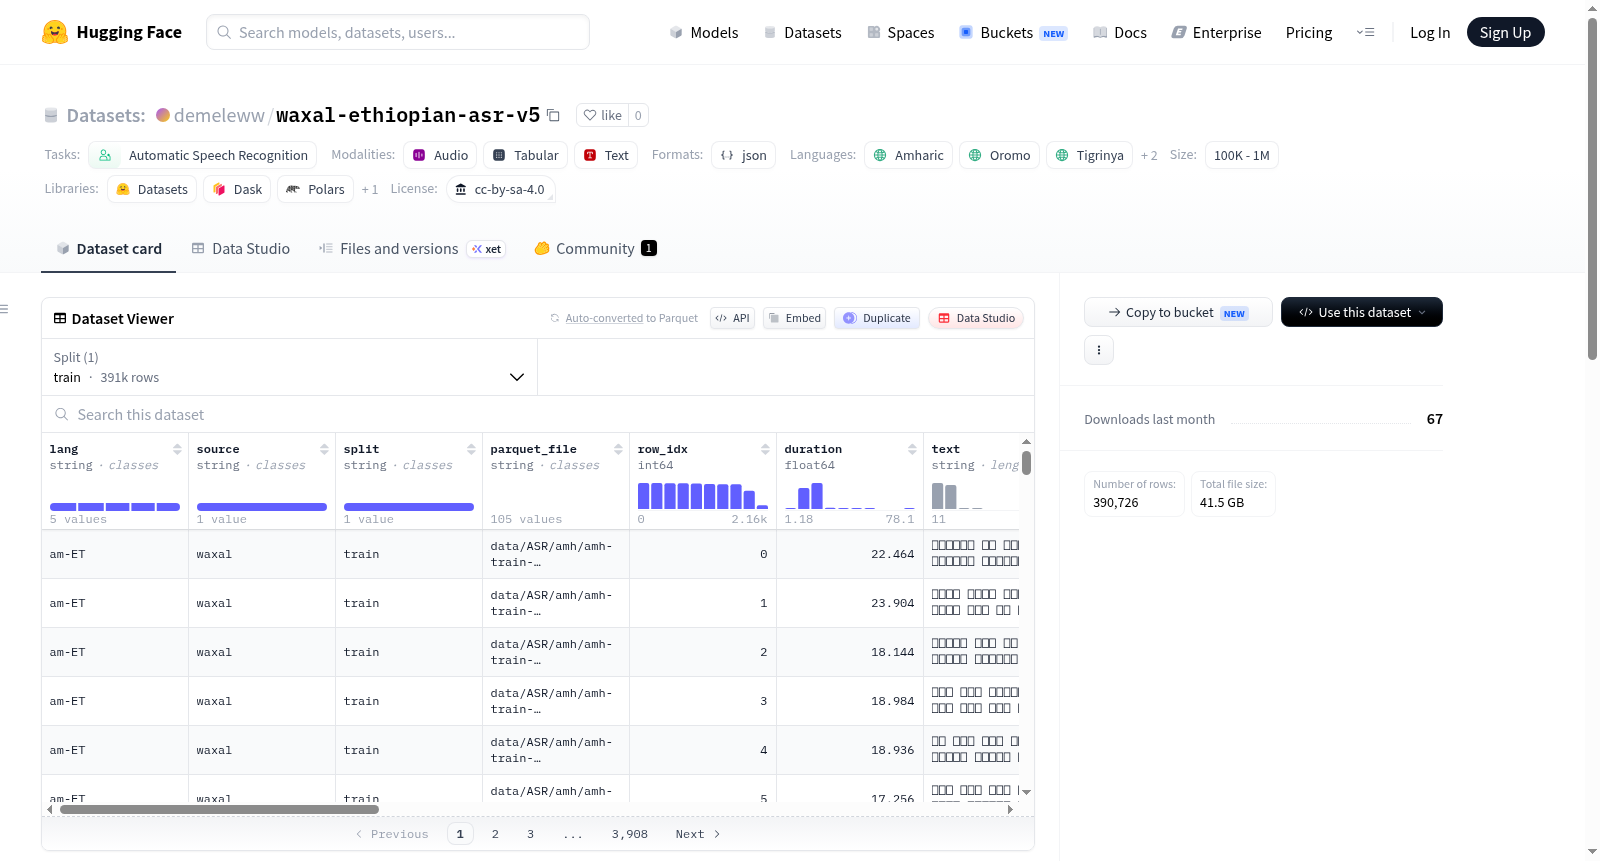
Waxal 埃塞俄比亚ASR语料库 v5(平衡、审计版)是一个精选的训练索引,基于 Google/WaxalNLP 数据集,覆盖五种埃塞俄比亚语言:阿姆哈拉语(am)、奥罗莫语(om)、提格里尼亚语(ti)、锡达马语(sid)和沃莱塔语(wal)。该索引包含总计 195,363 个音频片段,总时长 940.35 小时,每种语言约 190 小时,实现自然平衡。数据集包含以下内容:一个合并清单(train_all.jsonl,195,363 行)、每个语言的单独清单(train_{lang}.jsonl)、语言统计报告(dataset_v5_report.json,含片段数、时长、标记数、说话人数)以及教师假设目录(teacher_hypotheses/),其中包含基于 Ethio-ASR-600M 和 w2v-bert-2.0-uf 模型对 WAXAL 验证集的假设,可用于知识蒸馏。每条记录包含 16 个字段:lang(语言)、source(来源,固定为waxal)、split(分割,固定为train)、parquet_file(Parquet 文件路径)、row_idx(行索引,用于定位音频)、duration(秒)、text(原始文本)、text_normalized(规范化文本)、speaker_id(说话人ID)、audio_fp(音频指纹)、text_hash(文本哈希)、char_count(字符数)、token_est(估计词元数)、token_rate(词元率)、char_per_sec(每秒字符数)、quality_score(质量分数)、flags(质量标志)、leakage(泄漏标记)、duplicate_in_train(训练集内重复标记)。数据集经过严格的审计流程:规范归一化(NFC、标签剥离、大小写折叠、分隔符处理);保留集泄漏检测(确保规范化文本、音频、说话人与验证集和测试集无重叠,有泄漏的行被删除);精确音频重复检测(基于原始字节MD5)和规范化文本碰撞检测(重复项被删除);质量标志(时长异常、错误脚本、高词元率、高字符率、文本过短/过长等,仅标记不删除,供后续人工审核)。说话人ID被保留用于说话人分离检查。音频来源为 WAXAL(google/WaxalNLP),采用 CC-BY-SA-4.0 / CC-BY-4.0 许可。本仓库仅为精选的索引/清单,不托管音频文件,用户需通过 parquet_file 和 row_idx 定位器从 google/WaxalNLP 获取音频并生成 16kHz 单声道 WAV 文件。该数据集适用于自动语音识别(ASR)模型的训练、评估和知识蒸馏。
Waxal Ethiopian ASR Corpus v5 (Balanced, Audited) is a curated training index based on the Google/WaxalNLP dataset, covering five Ethiopian languages: Amharic (am), Oromo (om), Tigrinya (ti), Sidama (sid), and Wolaytta (wal). The index contains a total of 195,363 audio clips with a total duration of 940.35 hours, approximately 190 hours per language, achieving natural balance. The dataset includes: a merged manifest (train_all.jsonl, 195,363 lines), per-language manifests (train_{lang}.jsonl), a language statistics report (dataset_v5_report.json with clip count, duration, token count, speaker count), and a teacher hypotheses directory (teacher_hypotheses/) containing hypotheses on the WAXAL validation set based on Ethio-ASR-600M and w2v-bert-2.0-uf models, which can be used for knowledge distillation. Each record has 16 fields: lang, source (fixed as waxal), split (fixed as train), parquet_file, row_idx, duration (seconds), text, text_normalized, speaker_id, audio_fp, text_hash, char_count, token_est, token_rate, char_per_sec, quality_score, flags, leakage, and duplicate_in_train. The dataset underwent a rigorous audit process: canonical normalization (NFC, tag stripping, case folding, separator handling); held-out set leakage detection (ensuring normalized text, audio, and speakers do not overlap with validation and test sets, with leaked rows removed); exact audio deduplication (based on raw byte MD5) and normalized text collision detection (duplicates removed); quality flags (duration anomalies, wrong scripts, high token rate, high character rate, text too short/long, etc., flagged but not removed for manual review). Speaker IDs are retained for speaker separation checks. Audio source is WAXAL (google/WaxalNLP), licensed under CC-BY-SA-4.0 / CC-BY-4.0. This repository only contains curated indices/manifests, not audio files; users must use parquet_file and row_idx locators to fetch audio from google/WaxalNLP and generate 16kHz mono WAV files. The dataset is suitable for training, evaluation, and knowledge distillation of automatic speech recognition (ASR) models.
WAXAL Ethiopian ASR Corpus v5(平衡、审计版)
这是一个针对五种埃塞俄比亚语言的自动语音识别(ASR)训练数据索引集,基于google/WaxalNLP完整训练集进行策划与审计。
数据集规模
- 总音频片段:195,363条
- 总时长:940.35小时
- 语言平衡性:五种语言各约190小时,天然均衡
覆盖语言
- 阿姆哈拉语(am)
- 奥罗莫语(om)
- 提格里尼亚语(ti)
- 锡达马语(sid)
- 沃莱塔语(wal)
数据内容
train/train_all.jsonl:合并清单(195,363行)train/train_{am-ET,om-ET,ti-ET,sid-ET,wal-ET}.jsonl:各语言独立清单dataset_v5_report.json:各语言统计信息(片段数、时长、标记数、说话人数)teacher_hypotheses/:Ethio-ASR-600M与w2v-bert-2.0-uf模型在验证集上的伪标签(用于蒸馏)
数据行字段格式
每条记录包含:语言、来源、分割、parquet文件定位符、行索引、时长(秒)、原始文本、规范化文本、说话人ID、音频文件路径、文本哈希、字符数、token估计数、token速率、每秒字符数、质量评分、质量标记、泄漏标记、训练集中重复标记。
审计流程
- 规范化处理:执行NFC标准化、标签移除、大小写折叠、分隔符处理
- 泄漏检测:与验证集+测试集进行规范化文本/音频/说话人完全零重叠,任何泄漏行均被删除
- 重复检测:通过原始字节MD5检测精确音频重复,并检测规范化文本冲突(均删除)
- 质量标记:标记时长异常、错误字符集、token速率过高、字符速率过高、文本过短/过长(仅标记不删除,供人工筛查)
- 说话人ID保留:支持说话人不重叠检查
来源与许可
- 音频来源于WAXAL(
google/WaxalNLP),遵循CC-BY-SA-4.0 / CC-BY-4.0许可 - 本仓库仅为策划索引/清单,不包含音频字节,需通过
parquet_file+row_idx定位符从google/WaxalNLP获取音频,并转换为16kHz单声道WAV格式