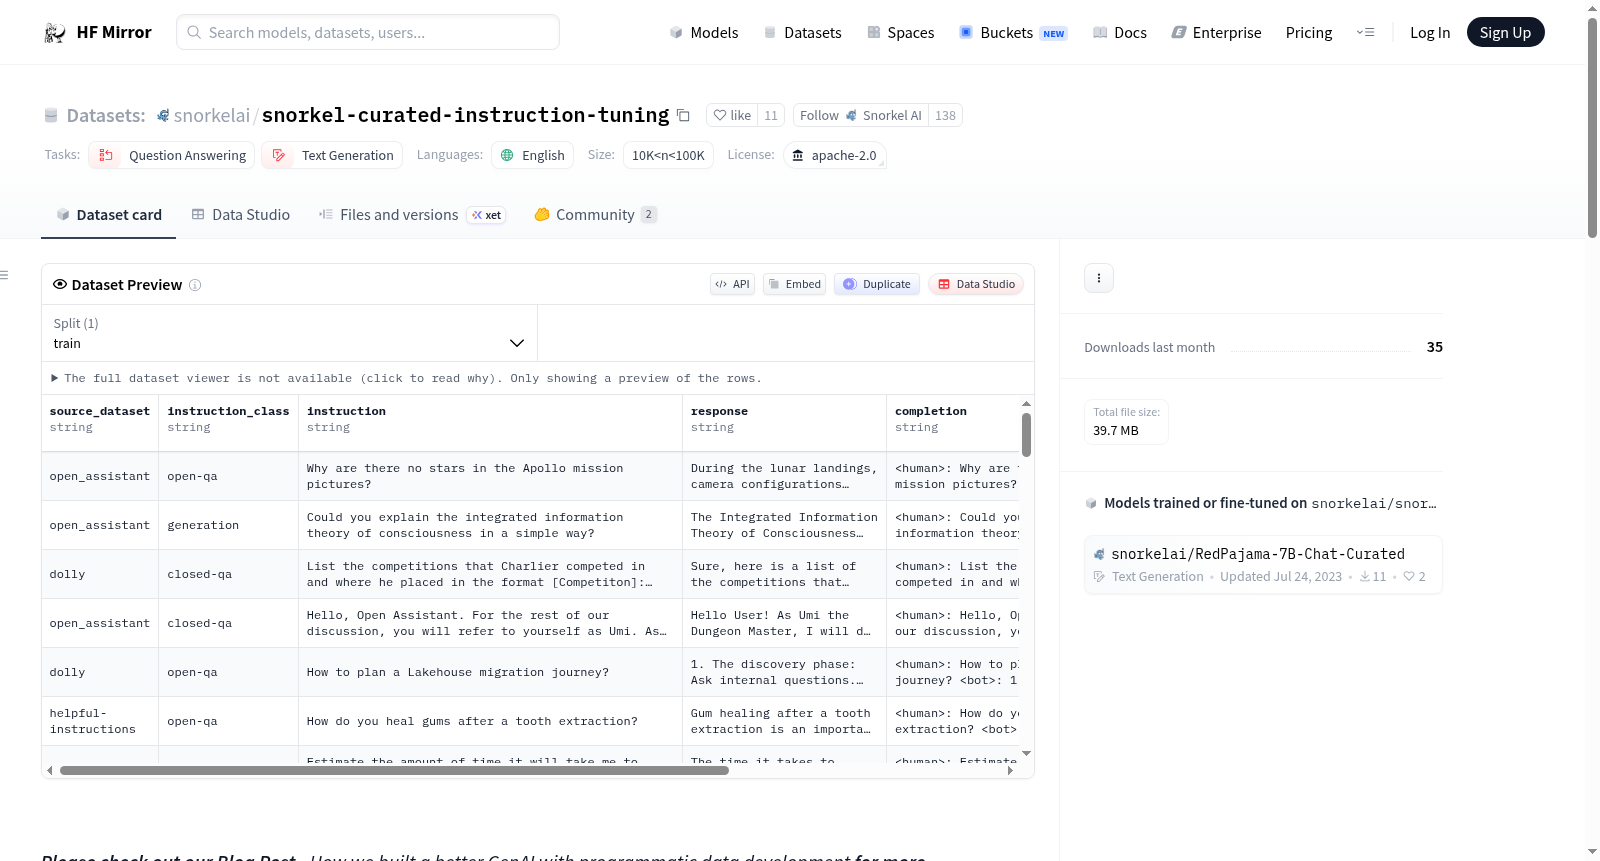
snorkelai/snorkel-curated-instruction-tuning
收藏资源简介:
--- license: apache-2.0 task_categories: - question-answering - text-generation language: - en size_categories: - 10K<n<100K --- ***<p style="font-size: 20px">Please check out our Blog Post - [How we built a better GenAI with programmatic data development](https://snorkel.ai/how-we-built-better-genai-with-programmatic-data-development/) for more details!</p>*** ## Summary `snorkel-curated-instruction-tuning` is a curated dataset that consists of high-quality instruction-response pairs. These pairs were programmatically filtered with weak supervision from open-source datasets [Databricks Dolly-15k](https://huggingface.co/datasets/databricks/databricks-dolly-15k), [Open Assistant](https://huggingface.co/datasets/OpenAssistant/oasst1), and [Helpful Instructions](https://huggingface.co/datasets/HuggingFaceH4/helpful_instructions). To enhance the dataset, we also programmatically classified each instruction based on the InstructGPT paper. For a more comprehensive understanding of our methodology, please visit our [blog](https://snorkel.ai/how-we-built-better-genai-with-programmatic-data-development/). ## Dataset Overview & Methodology Instruction tuning is an important step in developing effective [large language models (LLMs)](https://snorkel.ai/large-language-models-llms/) for generative AI tasks. While proprietary datasets have been used by LLM-backed chatbots, the open-source community has created similar datasets accessible to everyone. However, the quality of responses collected by volunteers has been inconsistent, affecting the quality of open-source models. Furthermore, there is currently no standard classification of instructions across datasets (many lack classification altogether), which can complicate measurements of instruction diversity when compiling from multiple sources. Snorkel, with its expertise in converting noisy signals into high-quality supervision, addressed this issue by programmatically scoring, sampling, and filtering open-source datasets. The curated dataset and methodology are now available for public use. Please refer to our [blog](https://snorkel.ai/how-we-built-better-genai-with-programmatic-data-development/) for more details on methods and evaluation. ## File descriptions - `snorkel_curated_11k.jsonl`: 11k high-quality instruction-response pair selected from the mentioned open-source dataset. This is then used to instruction-tune the [snorkelai/RedPajama-7B-Chat-Curated](https://huggingface.co/snorkelai/RedPajama-7B-Chat-Curated/). - `snorkel_hold_out_set.jsonl`: A hold-out set for evaluation, comparing human preferences between models. ## Intended Uses - Instruction-tuning LLMs For more detailed information, please refer to our blog post available at [How we built a better GenAI with programmatic data development](snorkel.ai/how-we-built-a-better-genai-with-programmatic-data-development). ## License/Attribution **Copyright (2023) Snorkel AI, Inc.** This dataset was developed at [Snorkel AI](https://snorkel.ai/) and its use is subject to the Apache 2.0 license. This work comes with the collaboration with Together Computer in releasing the [snorkelai/RedPajama-7B-Chat-Curated](https://huggingface.co/snorkelai/RedPajama-7B-Chat-Curated/) model. Please refer to the licenses of the data subsets you use. - [Open Assistant](https://huggingface.co/datasets/OpenAssistant/oasst1) is under Apache 2.0 license. - [Helpful Instructions](https://huggingface.co/datasets/HuggingFaceH4/helpful_instructions) is under Apache 2.0 license. - [Databricks Dolly-15k](https://huggingface.co/datasets/databricks/databricks-dolly-15k) is under CC BY-SA 3.0 license. Certain categories of material in the dataset include materials from the following sources, licensed under the CC BY-SA 3.0 license: Wikipedia (various pages) - https://www.wikipedia.org/ Copyright © Wikipedia editors and contributors. Databricks (https://www.databricks.com) Copyright © Databricks ## Language English ## Version Version: 1.0 To cite this dataset, please use: ``` @software{snorkel2023instructiontuning, author = {Snorkel AI}, title = {Applying programmatic data development to Generative AI with Snorkel}, month = June, year = 2023, url = {https://huggingface.co/datasets/snorkelai/snorkel-curated-instruction-tuning} } ``` **Owner: Snorkel AI, Inc.** ## Community Join us on [Snorkel AI Slack](snorkel.ai/slack)
许可证:Apache 2.0 任务类别: - 问答 - 文本生成 语言: - 英语 规模类别: - 10,000 < 样本量 < 100,000 ***<p style="font-size: 20px">请查阅我们的博客文章——《如何通过程序化数据开发构建更优秀的生成式AI》,以获取更多细节!</p>*** ## 数据集摘要 `snorkel-curated-instruction-tuning` 是一个精选数据集,包含高质量的指令-回复对。这些数据对通过弱监督技术,对开源数据集 [Databricks Dolly-15k](https://huggingface.co/datasets/databricks/databricks-dolly-15k)、[Open Assistant](https://huggingface.co/datasets/OpenAssistant/oasst1) 以及 [Helpful Instructions](https://huggingface.co/datasets/HuggingFaceH4/helpful_instructions) 进行了程序化筛选。 为进一步优化数据集质量,我们还基于 InstructGPT 论文对每条指令进行了程序化分类。 如需更全面了解我们的研究方法,请访问我们的[博客](https://snorkel.ai/how-we-built-better-genai-with-programmatic-data-development/)。 ## 数据集概览与研究方法 指令微调是开发适用于生成式AI任务的高效[大语言模型(Large Language Model,LLM)](https://snorkel.ai/large-language-models-llms/)的关键步骤。尽管基于大语言模型的聊天机器人曾使用专有数据集,但开源社区已推出可供所有人使用的同类数据集。然而,志愿者收集的回复质量参差不齐,严重影响了开源模型的性能表现。此外,当前各数据集之间尚无统一的指令分类标准(多数数据集甚至完全未进行分类),这会在多源数据集整合时大幅增加指令多样性评估的复杂度。 Snorkel凭借其将噪声信号转化为高质量监督信号的专业技术,通过程序化评分、采样与筛选的方式解决了上述痛点。本精选数据集与相关研究方法现已面向公众开放使用。 如需了解更多方法与评估细节,请参阅我们的[博客](https://snorkel.ai/how-we-built-better-genai-with-programmatic-data-development/)。 ## 文件说明 - `snorkel_curated_11k.jsonl`:从上述开源数据集中筛选出的11,000条高质量指令-回复对,可用于对[snorkelai/RedPajama-7B-Chat-Curated](https://huggingface.co/snorkelai/RedPajama-7B-Chat-Curated/)模型进行指令微调。 - `snorkel_hold_out_set.jsonl`:用于模型评估的预留测试集,可用于对比不同模型的人类偏好评分。 ## 预期用途 - 大语言模型的指令微调 如需获取更详细的信息,请参阅我们的博客文章《如何通过程序化数据开发构建更优秀的生成式AI》,链接为:https://snorkel.ai/how-we-built-a-better-genai-with-programmatic-data-development。 ## 许可与归因 **版权所有(2023)Snorkel AI, Inc.** 本数据集由[Snorkel AI](https://snorkel.ai/)开发,使用需遵循Apache 2.0协议。 本工作与Together Computer合作发布了[snorkelai/RedPajama-7B-Chat-Curated](https://huggingface.co/snorkelai/RedPajama-7B-Chat-Curated/)模型。 请参阅您所使用的数据子集的许可协议: - [Open Assistant](https://huggingface.co/datasets/OpenAssistant/oasst1) 采用Apache 2.0协议。 - [Helpful Instructions](https://huggingface.co/datasets/HuggingFaceH4/helpful_instructions) 采用Apache 2.0协议。 - [Databricks Dolly-15k](https://huggingface.co/datasets/databricks/databricks-dolly-15k) 采用CC BY-SA 3.0协议。 本数据集中部分类别的素材源自以下来源,均已获得CC BY-SA 3.0协议授权: 维基百科(各页面)——https://www.wikipedia.org/ 版权归维基百科编辑者与贡献者所有。 Databricks(https://www.databricks.com)版权归Databricks所有。 ## 语言 英语 ## 版本 版本:1.0 如需引用本数据集,请使用以下格式: @software{snorkel2023instructiontuning, author = {Snorkel AI}, title = {Applying programmatic data development to Generative AI with Snorkel}, month = June, year = 2023, url = {https://huggingface.co/datasets/snorkelai/snorkel-curated-instruction-tuning} } **所有者:Snorkel AI, Inc.** ## 社区 加入我们的[Snorkel AI Slack社区](snorkel.ai/slack)
数据集概述
snorkel-curated-instruction-tuning 是一个精选数据集,包含高质量的指令-响应对。这些对是通过弱监督程序从开源数据集中筛选出来的,包括 Databricks Dolly-15k、Open Assistant 和 Helpful Instructions。
为了增强数据集,我们还根据 InstructGPT 论文程序化地对每个指令进行了分类。
数据集概览与方法论
指令调优是开发有效的生成式 AI 任务的大型语言模型(LLMs)的重要步骤。虽然专有数据集已被 LLM 支持的聊天机器人使用,但开源社区也创建了类似的数据集供所有人访问。然而,志愿者收集的响应质量参差不齐,影响了开源模型的质量。此外,目前跨数据集的指令分类没有标准,这在从多个来源编译时可能会使指令多样性的测量复杂化。Snorkel 通过程序化地评分、采样和过滤开源数据集,解决了这一问题。精选数据集和方法现已公开可用。
文件描述
snorkel_curated_11k.jsonl: 从提到的开源数据集中选出的 11k 高质量指令-响应对,用于指令调优 snorkelai/RedPajama-7B-Chat-Curated。snorkel_hold_out_set.jsonl: 用于评估的保留集,比较模型之间的人类偏好。
预期用途
- 指令调优 LLMs
许可/归属
版权 (2023) Snorkel AI, Inc. 该数据集由 Snorkel AI 开发,其使用受 Apache 2.0 许可证约束。
此工作与 Together Computer 合作发布 snorkelai/RedPajama-7B-Chat-Curated 模型。
请参考您使用的数据子集的许可证:
- Open Assistant 受 Apache 2.0 许可证约束。
- Helpful Instructions 受 Apache 2.0 许可证约束。
- Databricks Dolly-15k 受 CC BY-SA 3.0 许可证约束。
数据集中的某些类别材料来自以下来源,受 CC BY-SA 3.0 许可证约束:
- Wikipedia (各种页面) - https://www.wikipedia.org/ 版权 © Wikipedia 编辑和贡献者。
- Databricks (https://www.databricks.com) 版权 © Databricks
语言
英语
版本
版本:1.0
引用此数据集时,请使用:
@software{snorkel2023instructiontuning, author = {Snorkel AI}, title = {Applying programmatic data development to Generative AI with Snorkel}, month = June, year = 2023, url = {https://huggingface.co/datasets/snorkelai/snorkel-curated-instruction-tuning} }
所有者:Snorkel AI, Inc.